Microsoft Fabric Cost Optimization: Practical Ways to Control Capacity Spend
Microsoft Fabric cost optimization starts with understanding how workloads consume Capacity Units (CUs), then matching capacity size and configuration to actual demand.
Stay updated with the latest developments in Artificial Intelligence
Microsoft Fabric cost optimization starts with understanding how workloads consume Capacity Units (CUs), then matching capacity size and configuration to actual demand.
More than 40% of all websites run on WordPress, according to W3Techs [1]. Over the past year, those sites gained a standard way to work with AI agents. WordPress 6.9 introduced the Abilities API, WordPress 7.0 added an AI Client to core, and the official MCP Adapter plugin turns registered…
I ran the forged New Yorker cartoons through OpenAI’s verification tool. All three carry a second, invisible signature: OpenAI’s.Continue reading on Towards AI »
One career question, then “just tell me I’m right”. GPT-6.1, Claude Opus 5.5, Gemini 3.8, DeepSeek, and Grok. Two held. Three said yes while saying they couldn’t.
AI Agents have changed daily software development. At the office, developers now have access to private frontier AI Models and a private frontier AI Agent Harness right in our IDEs.
I audited the repository OpenAI dropped on 6 October. Most of the proofs are machine-checked. The mathematicians are worried anyway, and…Continue reading on Towards AI »
We moved our AI workloads off rented cloud GPUs and onto a desktop-sized Grace Blackwell machine. Here is what we learned, what it cost, what broke, and why I think most regulated enterprises will run AI this way within five years.
Courses, runnable projects, agent tutorials and production playbooks, all open source and freeContinue reading on Towards AI »
In the last part of this tutorial, we collected high-quality art data. It is now time to design a database with useful functionalities so that we can store, organise, and interact with our data programmatically.
Smaller Model, Better Memory: Why Qwen2.5-1.5B Outperforms 3B (And Our 4 Hypotheses) Christopher Alberto Hamonangan This article is based on our recent research paper, ‘SRRM: A …
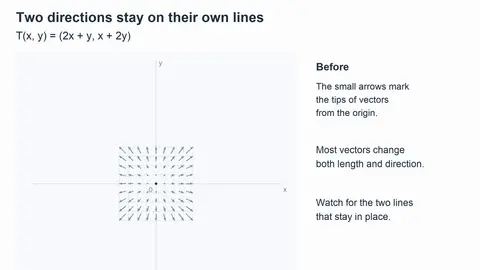
What do they tell us about a linear transformation?Continue reading on Towards AI »
Why 80% of enterprise RAG failures happen before retrieval starts. Learn the Goldilocks chunking dilemma, 512-token truncation, and production splitting rules.
A phased agentic workflow that centralizes interpretation while preserving execution authorityContinue reading on Towards AI »
An OpenAI privacy bug in the gap between an object and the assets derived from it
A local LLM on a daily-driver Windows desktop. Every video call cut its speed by up to 10x, and vLLM never reported an error. The decisive test, the VRAM math, and the configuration change that stopped it.
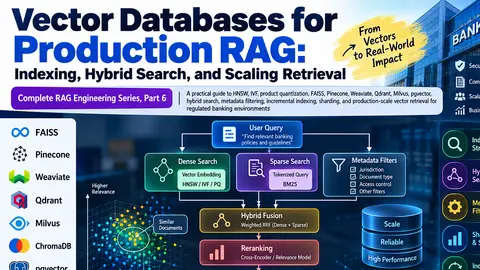
Complete RAG Engineering Series, Part 6 | A practical guide to HNSW, IVF, product quantization, FAISS, Pinecone, Weaviate, Qdrant, Milvus…Continue reading on Towards AI »
What each paper really says, why it still matters, and what to read next.Continue reading on Towards AI »
AI game merging can mean a content port, two live games linked by passthrough, or a rebuilt runtime. See what each route connects and what a demo proves.
Showing 90 of 234 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news from Towards AI
Join 15,000+ AI enthusiasts