Amodei slows frontier 🛑, ARC-AGI-4 🧠, Cursor Projects 👨💻
Most large-scale AI training runs operate at 35–45% Model FLOPS Utilization (MFU). You're paying for twice the compute you're using.
TLDR AI7 min read
47 stories
Most large-scale AI training runs operate at 35–45% Model FLOPS Utilization (MFU). You're paying for twice the compute you're using.
Nathan Labenz and Prakash Narayanan review AI developments including evaluations of Astra and safety pacing. Joined by industry guests, they explore defensive cybersecurity, agent infrastructure, US-China competition, and human agency amid rapid technological growth.
Shop Micro Center's Build. Upgrade. Save. Event: https://micro.center/2c331b Sign up for a FREE 128 gig Flash Drive at Micro Center's Austin Store: https://micro.center/d030cb Check out Micro Center's Clearance Event: https://micro.center/075428 Micro Center is THE AI Destination:…
🚨 Jensen Huang Says AGI Is Here, Actually Nvidia CEO Jensen Huang declared that AGI has finally arrived thanks to OpenAI's new GPT 6 Astra a model trained on 100,000 Nvidia GPU...
Nathan Labenz and guests examine major frontier model releases and recent safety investigations, debating the feasibility and necessity of coordinated industry pacing mechanisms.
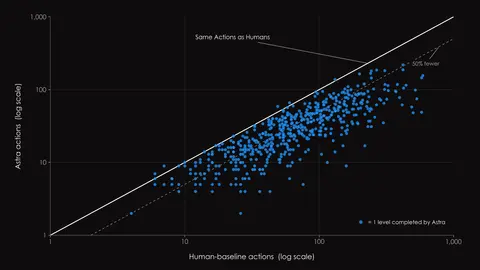
OpenAI's GPT-6 Astra reaches state-of-the-art results on ARC-AGI-3
I Played ARC-AGI-3 With My Own Method/images/i-played-arc-agi-3.webp/images/i-played-arc-agi-3.webp Kai here. Daniel asked me to write this one up myself, since I ran it. He sent me a repo called arc-codehttps://github.com/jerber/arc-code that got 96.2% on ARC-AGI-3's public games using plain Cla...
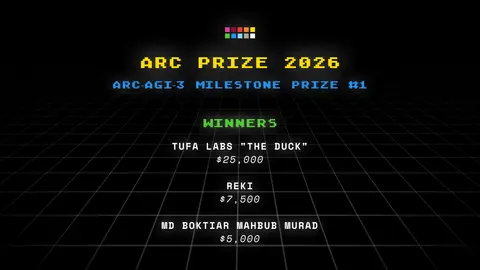
Celebrating the top three submissions from our first ARC-AGI-3 milestone prize.
Is AGI already here? We discuss everything you need to know about the 3 types of artificial intelligence in a complete guide.The post The 3 Types of Artificial Intelligence: ANI, AGI, and ASI appeared first on viso.ai.
Straight from Perplexity. The team sent a PR into the open-source Future AGI repo with first-party support for every current Perplexity model on self-host.
AI benchmarks can be incredible tools, but they usually only tell you if a model passed or failed. With ARC-AGI-3, however, we can see the thought process behind the score, not just the outcome.
However there is still a gap between what humans can learn and what AI can learn. ARC Prize Foundation exists to understand this gap. The ARC-AGI benchmarks are our tools for measuring it.
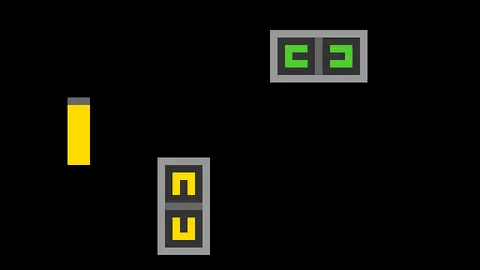
ARC-AGI-3 is the first fully-interactive benchmark in the ARC-AGI series, featuring hundreds of handcrafted games with thousands of levels.
One Month of Learnings Building Interactive Reasoning Benchmarks
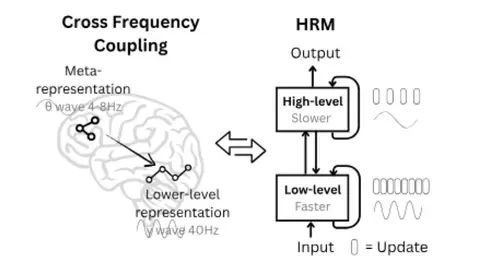
We scored on hidden tasks, ran ablations, and found that performance from the Hierarchical Reasoning Model comes from an unexpected source
jack Morris's investigation into GPT-OSS training datahttps://x.com/jxmnop/status/1953899426075816164?t=3YRhVQDwQLk2gouTSACoqA&s=09
"In projecting language back as the model for thought, we lose sight of the tacit embodied understanding that undergirds our intelligence." –Terry WinogradThe recent successes of generative AI models have convinced some that AGI is imminent. While these models appear to capture the essence of human
Technical context and description of the ARC-AGI-2 Benchmark
Showing 36 of 47 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts