Know a great AI tool or AI news source? Submit it to AiByts

Arize Phoenix

59 stories

Stories

← Back to the latest stories
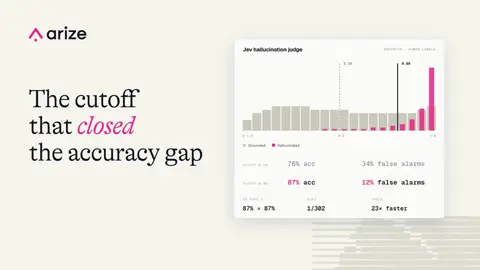
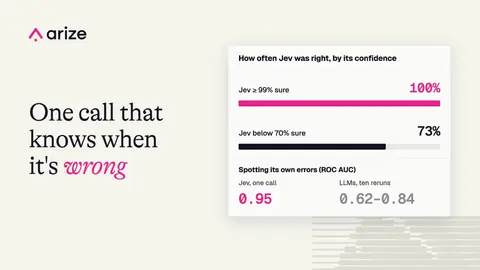
  • What Jev’s probabilities reveal that repeated LLM judgments miss

    I tested Jev and five LLM judges across ten Arize Phoenix evaluators to measure how often their answers changed alongside accuracy, cost, and latency. The post What Jev’s probabilities reveal that repeated LLM judgments miss appeared first on Arize AI.

    Arize AI12 min read
  • What is AI ops? Why LLM and agent systems require a different approach

    Last Updated on September 25, 2026 Most engineers approaching their first production LLM system bring a mental model that works well for software: test your inputs and outputs with assertions, check your code into git, roll back if something breaks, and rely on system prompts or configuration files…

    Sebastian Thrun’s Introduction To Machine Learning Blog9 min read
  • How we built UI Code Mode into Arize Phoenix

    We replaced the 58 tools PXI used to drive the Phoenix UI with two tools and a JavaScript sandbox that runs in your browser tab. Here's why, how it works, and what it cost. The post How we built UI Code Mode into Arize Phoenix appeared first on Arize AI.

    Arize AI22 min read
  • How to build a remote evaluator in Arize AX with Jev

    Evaluate agent responses with Jev and Arize AX. Build a FastAPI remote evaluator, return labels and scores, and choose a threshold for your data. The post How to build a remote evaluator in Arize AX with Jev appeared first on Arize AI.

    Arize AI10 min read
  • Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks

    We benchmarked Jev against Claude Opus 5 and GPT-5.6 Terra on accuracy, cost, and latency. Learn how threshold tuning changes hallucination detection. The post Jev vs. LLM-as-a-Judge: Accuracy and cost benchmarks appeared first on Arize AI.

    Arize AI10 min read
  • Will TypeSafe’s Jev Change How We Build AI Applications?

    The following article originally appeared on Arize’s blog and is being reposted here with the author’s permission. This week the AI community was in uproar about Jev from TypeSafe, not just a new model but a new kind of model: one that classifies, scores, and routes but can’t write a sentence.

    O'Reilly Radar - AI/ML9 min read
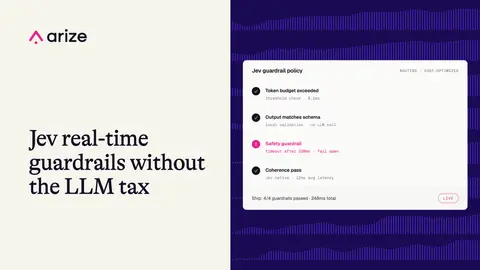
  • Real-time LLM guardrails with Jev: comparing latency and cost

    Compare Jev and GPT-5.4 nano for real-time LLM guardrails, with demo results on latency, cost, and checks on agent inputs, replies, and tool calls. The post Real-time LLM guardrails with Jev: comparing latency and cost appeared first on Arize AI.

    Arize AI11 min read
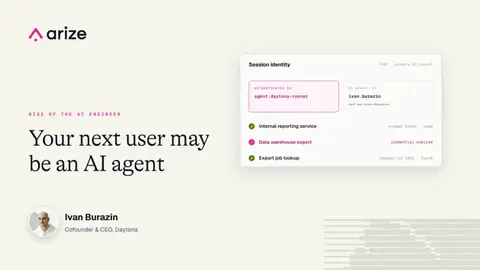
  • What changes when AI agents use your software

    Daytona cofounder Ivan Burazin wants agents that can finish the job within the authority they have been given. His interview offers a starting point for examining how agents use your software. The post What changes when AI agents use your software appeared first on Arize AI.

    Arize AI8 min read
  • The Most Important Skill for AI Engineers: Evals Explained

    Free AI Evals Course : https://github.com/aishwaryanr/awesome-generative-ai-guide/blob/main/free_courses/ai_evals_for_everyone/README.md 🚀Get 3 months of Arize AX Pro Free: https://app.arize.com/auth/join?utm_source=youtube&utm_medium=video&utm_campaign=ai-evals-video&utm_content=aishwarya-nr…

    Aish Reganti
  • Ouroboros — Laddoo 74/100

    An open-source (MIT) spec-and-verify harness that sits around your coding agent — a strong idea with broad host support, still early and unverified by us at runtime.

    Hlido Blog5 min read
  • Advanced RAG: Automated Structured Metadata Enrichment

    by Tuana Celik ( LI, Twitter) This is part one of the Advanced Use Cases series: 1️⃣ Extract Metadata from Queries to Improve Retrieval cookbook & full article 2️⃣ Query Expansion cookbook & full article 3️⃣ Query Decomposition cookbook & the full article 4️⃣ Automated Metadata Enrichment In this…

    Haystack by deepset7 min read
  • MCP logging and observability tools, compared

    A researched map of how teams actually watch MCP traffic today: the protocol's own shift to OpenTelemetry, the observability platforms that added MCP tracing, and the gap between debugging a server and running one.

    Elva Blog9 min read
  • The 7 best LLM evaluation tools in 2026

    A buyer's comparison of seven LLM evaluation tools: what each one meters, whether it scores curated datasets or live production traffic, what its license actually permits, and how much of your setup survives a switch.

    PydanticAI Blog16 min read

Showing 54 of 59 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts