SereneDB vs ClickHouse
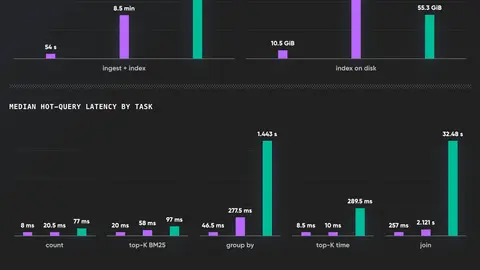
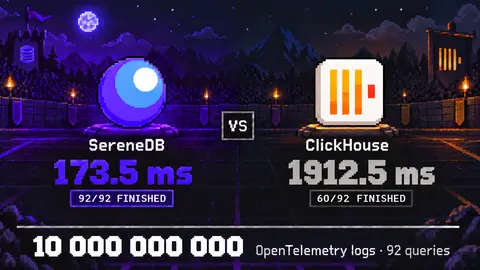
We ran 92 search and analytics queries over 100M, 1B and 10B OpenTelemetry logs against ClickHouse 26.8 with its new text index and SereneDB, all on a single instance.
SereneDB Blog20 min read
33 stories
We ran 92 search and analytics queries over 100M, 1B and 10B OpenTelemetry logs against ClickHouse 26.8 with its new text index and SereneDB, all on a single instance.
The same scraping tasks written as PandaScripts and as Puppeteer and Playwright scripts. Nearly identical code, 4x to 17x less memory, and one binary instead of two processes and a protocol.
We ran 92 search and analytics queries over 100M and 1B OpenTelemetry logs against Elasticsearch 9.5, its new columnar index mode, OpenSearch, CrateDB and SereneDB.
We ran 92 search and analytics queries over 100M and 1B OpenTelemetry logs against vanilla Postgres, ParadeDB with pg_search, TigerData with pg_textsearch and SereneDB.
TL;DR Claude Opus 5 tops independent SWE-bench Verified tracking at 96% - though Anthropic's own launch materials skip that benchmark entirely for custom evals Qwen3.
Overview GPT-5 mini launched on August 7, 2025, alongside full GPT-5 and a third, smaller GPT-5 nano, giving developers three sizes of the same generation to trade off against cost and latency.
Three papers landed this week that, read together, sketch out what happens once you stop treating an AI agent as a single system and start treating it as a node in a network.
One year after we started SereneDB we ran 92 search and analytics queries over 1B OpenTelemetry logs and put the numbers next to ArangoDB to see how far we have come.
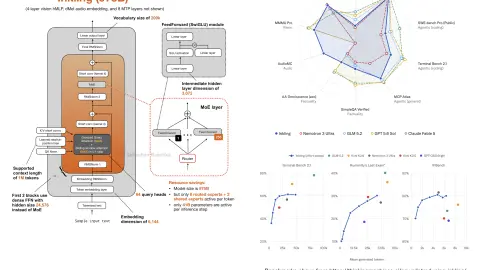
Architecture and benchmark notes on Thinking Machines Lab's 975B Inkling MoE, including short convolutions, relative-position bias, training, and effort control.
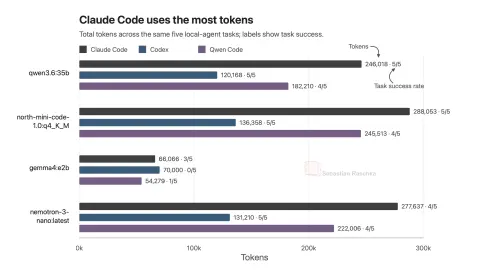
Short note on trying local open-weight LLMs across Qwen-Code, Codex, and Claude Code harnesses.
We learned that an agent’s tools matter more than its engine. We rebuilt our tool surface: the MCP is now far faster and more accurate, and a native agent built into the binary is faster still.
Architecture and benchmark notes for North Mini Code, Cohere's 30B-A3B MoE trained for repository, terminal, and code-generation tasks.
We ran Lightpanda, agent-browser, and browser-use through AssistantBench and GAIA Level 1 with Claude Sonnet 4.6 as the brain. The tool surface mattered more than the engine.
I've found one of the best ways to grow in my scientific coding is to spend time comparing the efficiency of various approaches to implementing particular algorithms that I find useful, in order to build an intuition of the performance of the building blocks of the scientific Python ecosystem.
Image source: astroML. Source code here Edit, Spring 2017: For an in-depth guide to the practical use of Lomb-Scargle periodograms, see the paper discussed in A Practical Guide to the Lomb-Scargle Periodogram.
Showing 33 of 33 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts