Jev vs LLM-as-a-Judge
An LLM judge writes a verdict. Jev returns a probability. We graded the same labeled answers and expert-rated summaries with both, and the difference decides which one you should use for a given rubric.
23 stories
An LLM judge writes a verdict. Jev returns a probability. We graded the same labeled answers and expert-rated summaries with both, and the difference decides which one you should use for a given rubric.
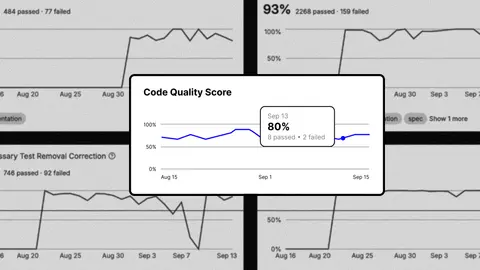
If you want to get the most out of coding agents in your organization, you need to stop guessing how well your agents are performing and start measuring.
An LLM judge is a second model that scores an agent's output against criteria you write in plain language. This guide explains where a judge fits beside deterministic tests and human review, then shows how to add one to an Ori Eval test, compare candidate models, calibrate the threshold against…
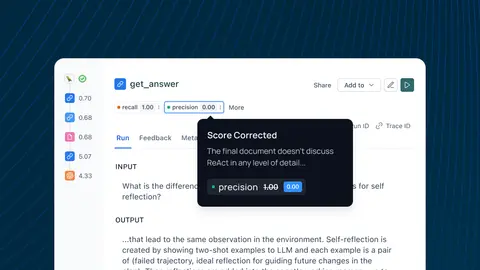
Deep dive into self-improving evaluators in LangSmith, motivated by the rise of LLM-as-a-Judge evaluators plus research on few-shot learning and aligning human preferences.
You've built an Orchestrator that can plan/replan its own steps. That’s powerful, but it can't judge its own work. If it generates broken code or misses a key detail, it just hands that bad first draft straight to your user. In this video, we're looking at the Evaluator Loop.
Showing 23 of 23 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts