Know a great AI tool or AI news source? Submit it to AiByts

llm

280 stories

Stories

← Back to the latest stories
  • When Do You Really Need a GPU in AI? Simple Explanation.

    Join as a member to access AI Projects & Member only videos. https://www.youtube.com/channel/UCAHa1-TnXAJrkDVMHbcP1Sw/join Do you really need a GPU to build and deploy AI applications? Many beginners think that every AI application needs a GPU. But that is not true.

    Applied with AI
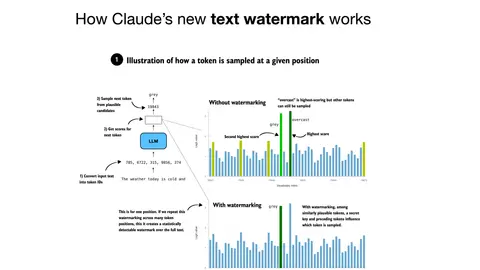
  • How Claude's Text Watermarking Works

    Short illustration of how Claude's text watermarking is supposed to work based on Anthropic's released materials.

    Sebastian Raschka2 min read
  • Becoming Human AI Is Expanding — Here’s What’s Changing

    Becoming Human AI Is Expanding — Here’s What’s Changing For years, this has been where you’ve found us — through Medium, whenever we published something worth your time. That’s changing a …

    Becoming Human (AI)1 min read
  • What is RAFT? RAG + Fine-Tuning

    What is RAFT? RAG + Fine-Tuning In simple terms, retrieval-augmented fine-tuning, or RAFT, is an advanced AI technique in which retrieval-augmented generation is joined with fine-tuning to enhance …

    Becoming Human (AI)4 min read
  • GPT-5 mini

    Overview GPT-5 mini launched on August 7, 2025, alongside full GPT-5 and a third, smaller GPT-5 nano, giving developers three sizes of the same generation to trade off against cost and latency.

    Awesome Agents Newsletter Blog7 min read
  • Muse Glimmer 30B Architecture Notes

    Short architecture note on Meta Muse Glimmer 30B, including gated local and global GQA, KV-cache efficiency, and release-time benchmark comparisons.

    Sebastian Raschka2 min read
  • Constrained Decoding: How AI Agents Are Forced to Return Valid JSON

    Every AI agent tool call is just text, and the program reading it is unforgiving — one bracket out of place and the whole response fails to parse. Prompting your way around that gets you "most of the time," which isn't the same thing as "every time." This deep dive explains constrained decoding:…

    Scrollypedia
  • Question Answering with LangChain and Qdrant

    Follow along in Colab: Building applications with Large Language Models doesn’t have to be complicated. A lot has been going on recently to simplify the development, so you can utilize already pre-trained models and support even complex pipelines with a few lines of code.

    Qdrant7 min read
  • Kimi K3 Architecture Notes

    Short architecture note on Kimi K3, including LatentMoE, Kimi Delta Attention, Attention Residuals, NoPE, multimodality, and inference-efficiency choices.

    Sebastian Raschka2 min read
  • A Few Notable Open-Weight Models This Week

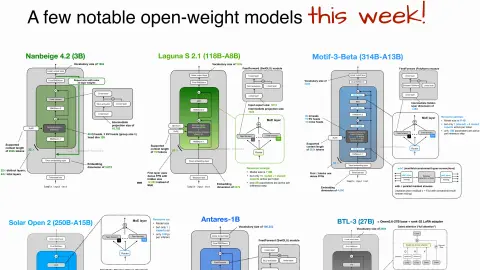
    Short note on the architectures of six new open-weight models, including Nanbeige 4.2, Laguna S 2.1, Motif-3-Beta, Solar Open 2, Antares 1B, and BTL-3.

    Sebastian Raschka3 min read
  • 200,000 Subscribers

    Short note celebrating Ahead of AI reaching 200,000 subscribers.

    Sebastian Raschka1 min read
  • Ollama models: how to choose and run them

    Ollama runs language models on your own hardware with almost one command. The catch is picking one your machine can hold. How to read a model listing, do the RAM math, and run it.

    Relic Blog10 min read
  • Prompt injection examples, explained for defenders

    Prompt injection turns untrusted data into instructions a model obeys. The categories of prompt injection examples, why they work, and how to defend without pretending it is solved.

    Relic Blog8 min read
  • The best local LLM depends on your hardware

    The best local LLM is the smallest one that does your task and fits your memory. A buyer's guide organized by hardware tier and task, with honest evaluation advice.

    Relic Blog7 min read

Showing 234 of 280 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts