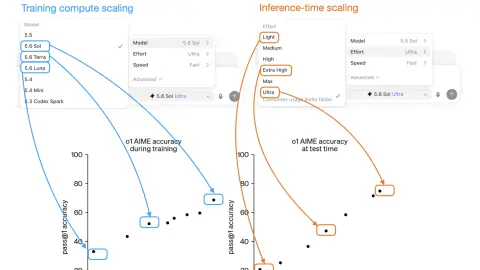
GPT 5.6 Has 72 Possible Configurations. What's A Good Default?
Short note on how GPT 5.6 model and effort choices map onto training-time and inference-time scaling, producing 72 configurations.
Sebastian Raschka1 min read
280 stories
Short note on how GPT 5.6 model and effort choices map onto training-time and inference-time scaling, producing 72 configurations.
Short note announcing the release of Build a Reasoning Model From Scratch and linking the publisher and Amazon pages.
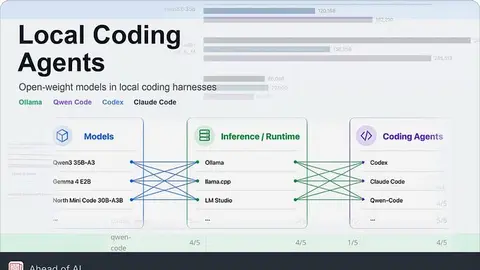
Short note linking a new article on setting up local coding agents with open-weight models.
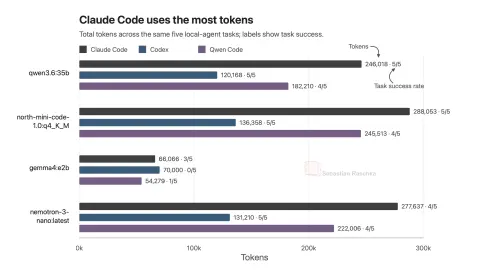
Short note on trying local open-weight LLMs across Qwen-Code, Codex, and Claude Code harnesses.
Frontier AI models are almost too big to use — a 70B model needs ~140 GB of memory just to hold its weights. So how do these giants end up running on a single GPU, or even on a laptop?
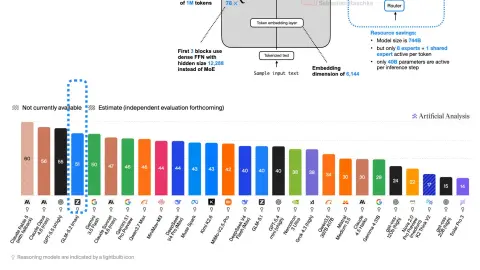
How GLM-5.2 uses IndexShare to reuse sparse-attention token selections across layers and reduce long-context indexer computation.
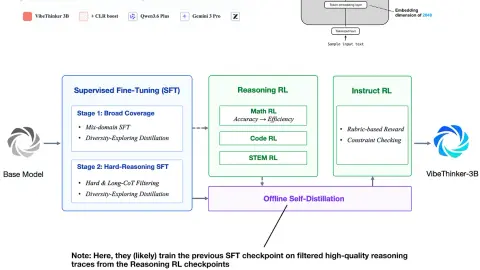
A closer look at VibeThinker-3B, a Qwen2.5-Coder-based model whose reported reasoning gains come from a detailed post-training pipeline.
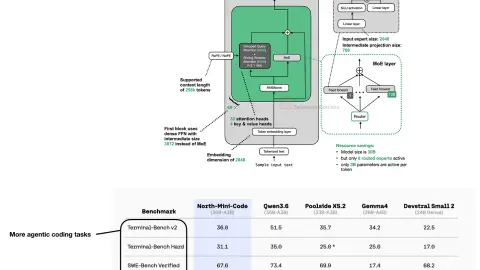
Architecture and benchmark notes for North Mini Code, Cohere's 30B-A3B MoE trained for repository, terminal, and code-generation tasks.
Constraint tests on how language models represent numerical magnitude.
GPT-3 was a major breakthrough in natural language processing. With 175 billion parameters, it demonstrated remarkable few-shot learning abilities and showed that scaling large language models could u
Having worked on robustness problems during my PhD, I see many of the characteristics appearing in the evaluation of LLMs and AI systems. Adversarial attacks such as jailbreaks are becoming more relevant, edge cases finally become relevant, test sets and benchmarks are not static anymore but…
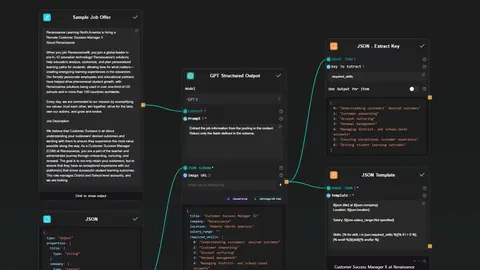
Learn how to build an LLM pipeline that returns structured JSON output using AI-Flow's GPT Structured Output node — no Python, no parsing code.
A direct comparison of n8n and AI-Flow for building AI model pipelines — where each tool fits, and where it doesn't.
Hidden context messages keep user-facing LLM chats clean while giving the model rich, per-message instructions—turning conversations into a predictable, tool‑driven workflow engine with a tiny amount of code.
A grounded walkthrough of tokenization and its impact on model behavior.
A technical look at LLaMA Factory—a feature-rich toolkit for tuning large language models—and the latest updates through 2025.
A technical look at Vercel AI SDK 5, a toolkit for building AI-powered applications, and how it integrates with VoltAgent. Updated for AI SDK 5.0 (July 2025).
Showing 252 of 280 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts