Human2Any: Human-to-Robot Transfer via Constraint-Aware Compositional Planning
Human2Any: Human-to-Robot Transfer via Constraint-Aware Compositional Planning cgarrett Tue, 09/15/2026 - 21:41
NVIDIA Research1 min read
245 stories
Human2Any: Human-to-Robot Transfer via Constraint-Aware Compositional Planning cgarrett Tue, 09/15/2026 - 21:41
A lot of advancements are being made in quantum computing that move beyond the basics of quantum pro ...
From Latin America to Southeast Asia, countries are dividing their AI investments between the two superpowers rather than choosing one over the other.
On a sweltering August evening in Silicon Valley, as the sun dropped and air conditioning loads spiked, Silicon Valley Power sent a signal to an AI factory to adjust its power consumption.
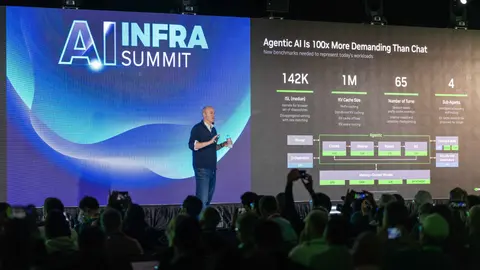
Ian Buck, vice president of hyperscale and high-performance computing at NVIDIA, Tuesday spoke on AI factory efficiency at the AI Infra Summit, the Santa Clara Convention Center event that has morphed into a Coachella of infrastructure tech.
Children’s Hospital of Philadelphia is using open source AI tools to model children’s hearts in seconds — with the goal of enabling safer, more precise care for kids with congenital heart disease.
For operators of large-scale AI factories, maximizing continuous output is essential for productivity. In massive-scale AI training, every GPU in the cluster...
Federated learning (FL) projects often begin with a straightforward setup: one server, a few clients, and one dataset at each site. As those projects grow, the...
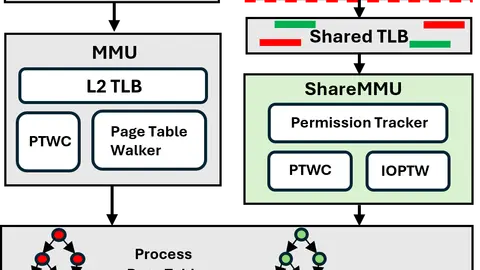
ShareMMU: Supporting Secure Address Translation Sharing among Untrusted Accelerators The growing demand for accelerated computing is driving widespread deployment of multi-accelerator systems in the cloud and at the edge.
SPONSORED POST: While many organizations have AI projects underway at various stages of maturit ...
FastGen-PDD: Parallel Decoding Distillation for Image and Video Generation Generation in video diffusion or flow models is computationally expensive due to the slow and iterative sampling process.
Composing Detector Error Models Fault-tolerant quantum programs thread together reusable logical operations, yet correcting errors requires comparing measurements across operation boundaries. Correlations tie each operation's error analysis to the computation around it.
ReasAlign: Reasoning Enhanced Safety Alignment against Prompt Injection Attack Large Language Models (LLMs) have enabled the development of powerful agentic systems capable of automating complex workflows across various fields.
ReasoningBomb: A Stealthy Denial-of-Service Attack by Inducing Pathologically Long Reasoning in Large Reasoning Models Large reasoning models (LRMs) extend large language models with explicit multi-step reasoning traces, but this capability introduces a new class of prompt-induced inference-time…
Architecting Secure AI Agents: Perspectives on System-Level Defenses Against Indirect Prompt Injection Attacks AI agents, predominantly powered by large language models (LLMs), are vulnerable to indirect prompt injection, in which malicious instructions embedded in untrusted data can trigger…
We ported ThunderKittens to NVIDIA's Vera Rubin NVL72 and rebuilt our NVFP4 GEMM around the new hardware, taking it from 42% of roofline to over 22 PFLOPS — competitive with cuBLAS and CuTe DSL. Here is what changed in the ISA and how we used it.
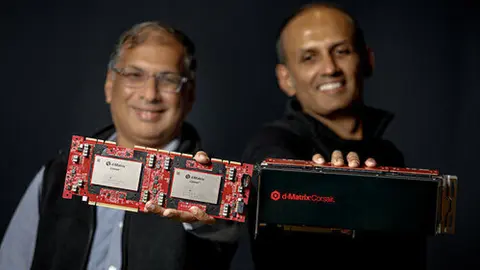
Engineers with startup d-Matrix have spent the past seven years putting together the pieces of what ...
In this notebook, we will build a Haystack Retrieval Augmented Generation (RAG) Pipeline using self-hosted AI models with NVIDIA Inference Microservices or NIMs. The notebook is associated with a technical blog demonstrating the steps to deploy NVIDIA NIMs with Haystack into production.
Showing 216 of 245 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts