"Failed to Fetch" Error: What It Means + How to Fix It
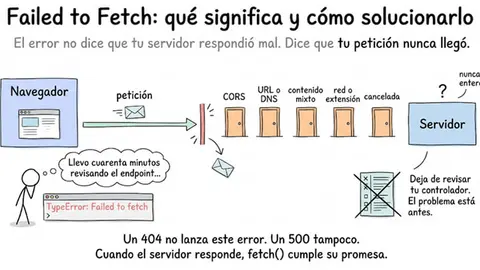
Seeing "TypeError: Failed to fetch"? It's not your internet. What the error means, the 5 real causes (CORS first), and how to fix each in minutes.
BetterClaw Blog11 min read
222 stories
Seeing "TypeError: Failed to fetch"? It's not your internet. What the error means, the 5 real causes (CORS first), and how to fix each in minutes.
How to check whether citations in an AI answer support its material claims, scope, and date.
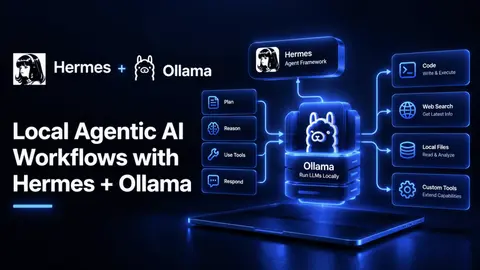
In this article, you will learn how to build a fully local, zero-cost agentic AI workflow using Hermes Agent and Ollama, so that your files,...
I benchmarked Qwen3-VL 8B Instruct (Q4_K_M, Ollama, M5 24GB, ~30s/doc) against Claude Opus 5.5, Sonnet 5 and GPT-5.6 Terra on: - receipts: CORD (Indonesia) and SROIE (Malaysia), 30 each - 20 scanned 1980s-90s invoices , answer keys human-verified - 32 real IRS forms, 4 damage levels (generated this…
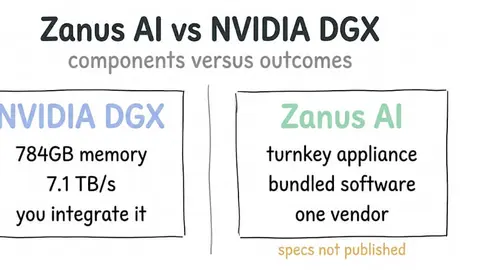
Zanus AI review: what its private AI servers include, why pricing is quote-only, what the vendor won't publish, and when an NVIDIA DGX makes more sense.
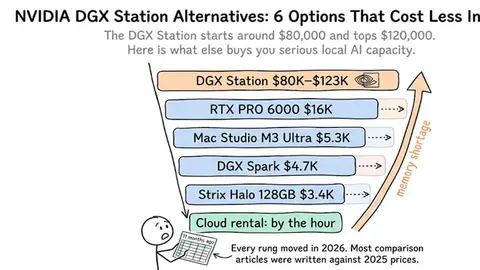
DGX Station price, Sept 2026: no NVIDIA list price. OEM listings run $91,813 (Supermicro) to $99,999 (MSI). What quotes include, and 6 cheaper options.
¿Te sale "Failed to fetch"? No es tu internet ni un virus. Qué significa en español, por qué pasa y cómo solucionarlo en 2 minutos, paso a paso.
There's no qwen3.7 on Ollama. 3.7 is API-only. Run Qwen 3.8 27B locally instead: VRAM by quant, Modelfile, num_ctx and tool calling.
8 Vertex AI Agent Builder alternatives that are cheaper or simpler: BetterClaw, n8n, Gumloop, CrewAI, Lindy, LangGraph, OpenRouter and AWS AgentCore.
To run a System One model locally, pick a runtime too: Ollaya serves ten open model families, laya-mlx runs Laya on Apple silicon, and llama.cpp needs a shim.
An honest Octomind and Crush comparison covering terminal UX, model choice, licenses, persistent machines, pricing, and integrations.
Curious how local LLM deployment stacks up? This post explores benchmarking strategies, optimization tips, and what DevOps teams need to know about.
Model routing for coding agents in September 2026: a frontier model plans, a cheap one executes. The plan and price numbers developers measured.
Nine places web research fails after search has already succeeded, each with a signature you can observe, the evidence that identifies it, and the smallest test that catches it.
The build side of running voice AI locally: what fits on one 24GB card, which runtime to use per stage, and what the latency actually looks like on a phone call.
A web research system you can trust with a current question does seven separate jobs. It defines what a complete answer looks like, discovers candidate sources, retrieves them, extracts evidence, checks that evidence for gaps, reconciles conflicts, and writes a cited result.
Compare Octomind and Goose on open source, models, machines, persistence, integrations, pricing, and scheduled agent work.
When comparing Chinese AI vs ChatGPT, your decision comes down to cost versus security. If you need low API pricing, open weights, and fast coding assistance, Chinese AI models like DeepSeek lead the way. However, if your team...
Showing 126 of 222 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts