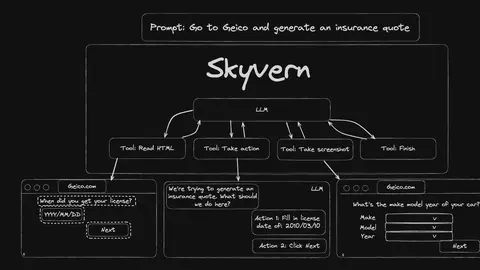
Deleting RAG from our web agent made it 2.3x faster
We rewrote Skyvern from scratch using Pi as inspiration, making it 2.3x faster and score 90.5% on Odysseys benchmark.
Skyvern Blog6 min read
518 stories
We rewrote Skyvern from scratch using Pi as inspiration, making it 2.3x faster and score 90.5% on Odysseys benchmark.
Last week, we shared our point of view on where we think agentic development is headed and introduced JetBrains’ answer to it: JetBrains Air, an open system of products for agentic development. Today, we’re launching the Early Access Program for Air in JetBrains IDEs.
Every dev team has repeatable setup tasks: spinning up a new project, running a deployment checklist, generating a file structure, or typing the same instructions into Claude again and again.
An LLM knowledge graph and vector RAG ground models differently. See when to use each, how to build a knowledge graph from text, and how to run both smoothly.
Retrieval-augmented generation (RAG) can ground large language models in external evidence, but retrieved context does not guarantee that generated claims are factually supported.
Google has been in its "Gemini era" for a couple years now, and while the confusing rebrandings have slowed, everything else continues to improve at a rapid pace.
Large language models (LLMs) are what most people think of when they think of AI. They're what you're interacting with in ChatGPT and Claude, they write the code generated by Claude Code and Codex, and they power other AI features like Google's AI answers and Apple Intelligence.
This technical how-to builds a conversational claims assistant on Amazon Bedrock Knowledge Bases that answers natural-language questions with citations.
Amazon S3 Vectors now supports pre-filtering, which evaluates metadata filters before running similarity search, returning up to 5x more of the matching vectors when your filter is selective. S3 Vectors also adds a prefix match operator ($startsWith) for filtering on values like paths and URLs.
Your AI Agent Will Obey Anyone. Guardrails Are How You Stop It. A guide to the attacks that break LLMs and AI agents, and the guardrails that stop each one. This guide assumes you know nothing about …
Complete RAG Engineering Series, Part 5 | A practical guide to dense and sparse embeddings, model selection, Matryoshka embeddings…Continue reading on Towards AI »
Cohere released Embed 5 on Wednesday, giving teams the option to index data with Embed 5 Pro and query those The post Cohere’s faster query model barely dents retrieval quality in its tests appeared first on The New Stack.
RAG stands for retrieval augmented generation. Strip the jargon and it is one idea: the model does not know your documents, so before you ask it a question, you look up the relevant passage yourself and paste it into the prompt. Retrieve, augment, generate. That is the whole trick.
Built for the TigerGraph Agentic GraphRAG Hackathon. Repo and dashboard linked at the end. RAG retrieves text. GraphRAG adds structure. Agentic GraphRAG lets a model plan its own investigation. Everyone assumes the third one is better — but by how much, and on which questions?
Short answer: Model Context Protocol documentation is versioned by date, not by number. Each revision has its own specification pages, a schema published beside them, and a changelog recording what moved since the previous revision.
Features, pricing, and crawl options side by side, plus a look at Firecrawl's new Alexandria library and when each platform is the better pick.
Your security team says traces can’t leave the building. Your finance team says the observability bill can’t grow with traffic. Your engineering team says they...
No — Voyage AI is operational. Uptime: 99.94%. 4 incidents tracked (30d). Live status, updated every 5 minutes.
Showing 198 of 518 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts