Firecrawl vs Building Your Own Crawler: A Practical Comparison for 2026
Compare Firecrawl's managed scraping against custom-built crawlers — cost, maintenance, reliability, and when a structured API is the better choice.
ZooData Blog7 min read
525 stories
Compare Firecrawl's managed scraping against custom-built crawlers — cost, maintenance, reliability, and when a structured API is the better choice.
A step-by-step guide covering how AI retrieval works, what on-page and authority signals move citation rate, what technical mistakes block it, and how to measure and repeat the cycle with Gauge.
PageIndex File System is a file-level tree layer that sits above your documents and scales the same PageIndex tree search from a single document to millions of documents in one index.
This release introduces the built-in MCP Server, Extensible Tokenizers, Diversity Search (MMR), and Query Profiling as previews, along with Incremental Backups, Gemini audio support for multi2vec-google, and the new BlobHash property type.
Learn how to ground LLM outputs with structured real-time data using RAG and API integration to reduce hallucinations and build reliable AI applications.
91% of AI models experience temporal degradation. Learn why real-time data access through APIs is critical for agent decision accuracy and how to implement it.
Data quality — not model size — drives AI accuracy. See how structured APIs outperform noisy scraped data for RAG, agents, and ecommerce AI.
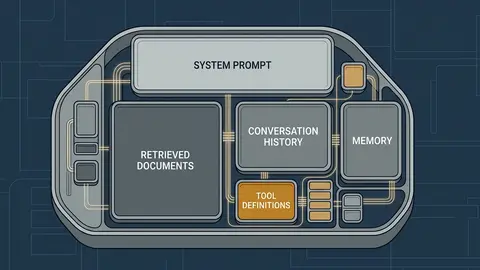
Every new generation of Large Language Models arrives with a bigger context window - and the temptation to use it fully. If the model can read a million tokens, why not feed it everything?
Learn how to set semantic caching thresholds, manage TTL, handle multi-turn queries, and monitor silent failures in production LLM apps.
3 (more) common #AI terms most people don’t know: Term 1: Grounding. Without it, AI answers from memory, which may or may not be correct. Hand it the actual document and say "answer from this," and now the response is grounded in something real.
Andrej Karpathy posted a markdown directory and the timeline declared the vector database obsolete. A brief note on what the eulogy left out.
AI decision integration checklist: align goals, secure data, set governance, train teams, run pilots, and scale with human oversight.
We built what Andrej Karpathy described, and solved the hard part. OpenKB is an open-source CLI that compiles raw documents into a structured, interlinked wiki, powered by PageIndex for long PDFs.
How we built a two-stage prompt injection classifier that achieves 0.99 F1 with sub-10ms latency.
AI for cross-department communication made simple. Centralize knowledge, automate handoffs, and measure ROI with a step-by-step rollout plan.
Your best evaluation data already exists — it's sitting in Google Drive, SharePoint, Notion, and S3. Dataset generation on Confident AI turns your existing documents into evaluation-ready datasets automatically.
Check out the best conversational AI companies and see how their platforms automate customer conversations and business workflows. Learn which conversational AI tools are worth considering for support, automation, and enterprise use.
A practical guide to implementing retrieval-augmented generation with the AI SDK — from ingesting documents into vectors to retrieving context at query time.
Showing 432 of 525 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts