How to Start an AI Automation Agency in 2026: Services, Tools, and Pricing
A practical guide to choosing a niche, packaging services, pricing projects, winning clients, and operating AI automations safely after launch.
Rerun Blog14 min read
245 stories
A practical guide to choosing a niche, packaging services, pricing projects, winning clients, and operating AI automations safely after launch.
Using GPT-5.6, V7 turns scattered company files into context agents can use to complete complex, source-linked work.
A practical, vendor-neutral guide to the API contract behind controllable agent runs, including lifecycle state, events, approvals, cancellation, observability, and auditability.
When comparing Chinese AI vs ChatGPT, your decision comes down to cost versus security. If you need low API pricing, open weights, and fast coding assistance, Chinese AI models like DeepSeek lead the way. However, if your team...
A comparison of the three current realtime speech-to-speech models on the axes that decide a phone deployment: interaction quality, documented telephony support, and pricing basis.
Your AI pilot works beautifully in a controlled demo. It reads a few sample support tickets, drafts replies, updates a test record, and gives the team a convincing glimpse of what could happen next.
Agentic Voice AI turns your phone bot into an autonomous worker — booking appointments, updating CRM, triggering follow-ups. How to make the leap
goose is replacing its classic agent loop with a re-entrant state machine where the conversation is the state and each behavior is an Operation.
DeepSeek V4 is a family of models, and only some of them accept images. This guide maps every V4 slug on our catalog to its input modalities, shows how to send an image to the two that read images, and shows how to put a vision model in front of the text-only ones.
Agentic LLM systems that generate code through multi-turn tool use face a fundamental context problem: each session starts from zero, discarding the configuration choices, domain constraints, data schemas, and tool-use patterns that made previous sessions productive.
Moving from closed to open source models can take weeks, not years. A five-stage playbook: discover, evaluate, adapt, decide, and production.
Ollama only runs the model, so the answer depends on which one you pull and your memory. What local models do well, where Claude wins, and a verdict.
Most large-scale AI training runs operate at 35–45% Model FLOPS Utilization (MFU). You're paying for twice the compute you're using.
An LLM judge is a second model that scores an agent's output against criteria you write in plain language. This guide explains where a judge fits beside deterministic tests and human review, then shows how to add one to an Ori Eval test, compare candidate models, calibrate the threshold against…
Listen and speak at once with Full Duplex in Famulor. Compare Pipeline, Half Cascade and Realtime, with model benchmarks, TTS data and use cases.
Staff AI Engineer - Agent Architecture & Behavior — San Francisco, CA · full-time · On-site · $250k-$325k
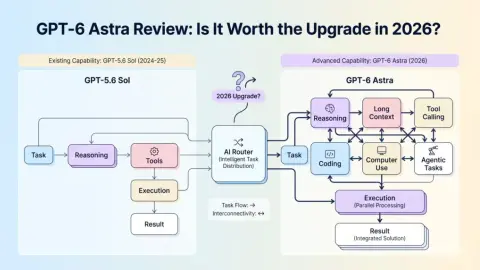
GPT-6 Astra earns a clear verdict: if your work involves multi-step digital tasks, this is the most meaningful upgrade OpenAI […] The post GPT-6 Astra Review: Is It Worth the Upgrade in 2026? appeared first on AiZolo.
Today's haul: 18 tools · 9 resources · 31 reads · 12 numbers · 22 things that happened. Every tool, resource and read below has a working link. No link, no listing.
Showing 144 of 245 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts