
Claude Code Caveman Eval: Two Sentences Took the Median Cut From 14.6% to 50.6%
Claude Code Caveman Eval: Two Sentences Took the Median Cut From 14.6% to 50.6% I recounted the repo’s own eval snapshots: the jump came from two added sentences, v3.1.0 still ships the core …
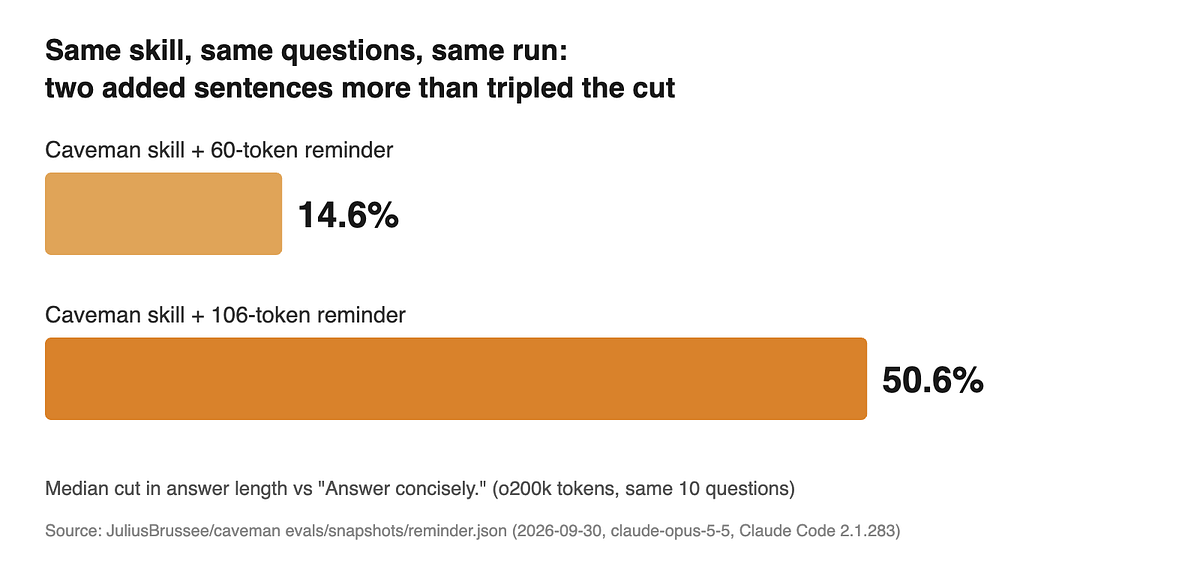
The article discusses how adding two specific sentences to the system prompt of the Claude Code Caveman Eval significantly increased the median cut in answer length from 14.6% to 50.6%, highlighting the impact of prompt engineering on model performance.
What happened
The article reports that adding two specific sentences to the system prompt of the Claude Code Caveman Eval significantly increased the median cut in answer length from 14.6% to 50.6%. These sentences focus on concise answers and avoid unnecessary background or examples. The evaluation results are committed to git, and a script is provided for replication.
Why it matters
This finding is significant for AI developers and NLP researchers as it demonstrates how prompt engineering can drastically affect model performance. It provides a practical example of how refining prompts can enhance the efficiency and effectiveness of language models.
- Prompt engineering can significantly affect model performance.
- Concise and focused prompts can enhance the efficiency of language models.
- Reproducibility is key in evaluating and refining model behavior.
The bigger picture
The practical impact of this finding is that it offers a replicable method for improving model performance through prompt engineering, which can be applied to various NLP tasks and models.
The article concludes that adding specific sentences to the system prompt of the Claude Code Caveman Eval significantly improved the model's performance, emphasizing the importance of prompt engineering in NLP.
Technical details
- The system prompt includes two sentences that guide the model to answer concisely.
- The evaluation results are stored in git for reproducibility.
- A 53-line script is provided for analyzing the results without requiring an API key.
FAQ
What was the impact of adding two sentences to the system prompt?
Adding two sentences to the system prompt increased the median cut in answer length from 14.6% to 50.6%.
What do the two sentences in the system prompt emphasize?
The two sentences emphasize concise answers and avoid unnecessary background or examples.
How were the evaluation results made available?
The evaluation results are committed to git, allowing for reproducibility.
Is there a script available for analyzing the results?
Yes, a 53-line script is provided for analyzing the results without requiring an API key.
This summary and analysis were generated with AI from the original article and may contain errors. Read the original for the full story.
Read the full story
Originally published by Towards AI on Oct 4, 2026.
Comments
Sign in to join the discussion.