
ImpossibleBench3 min read
Good Evals Are Hard: An ImpossibleBench Audit
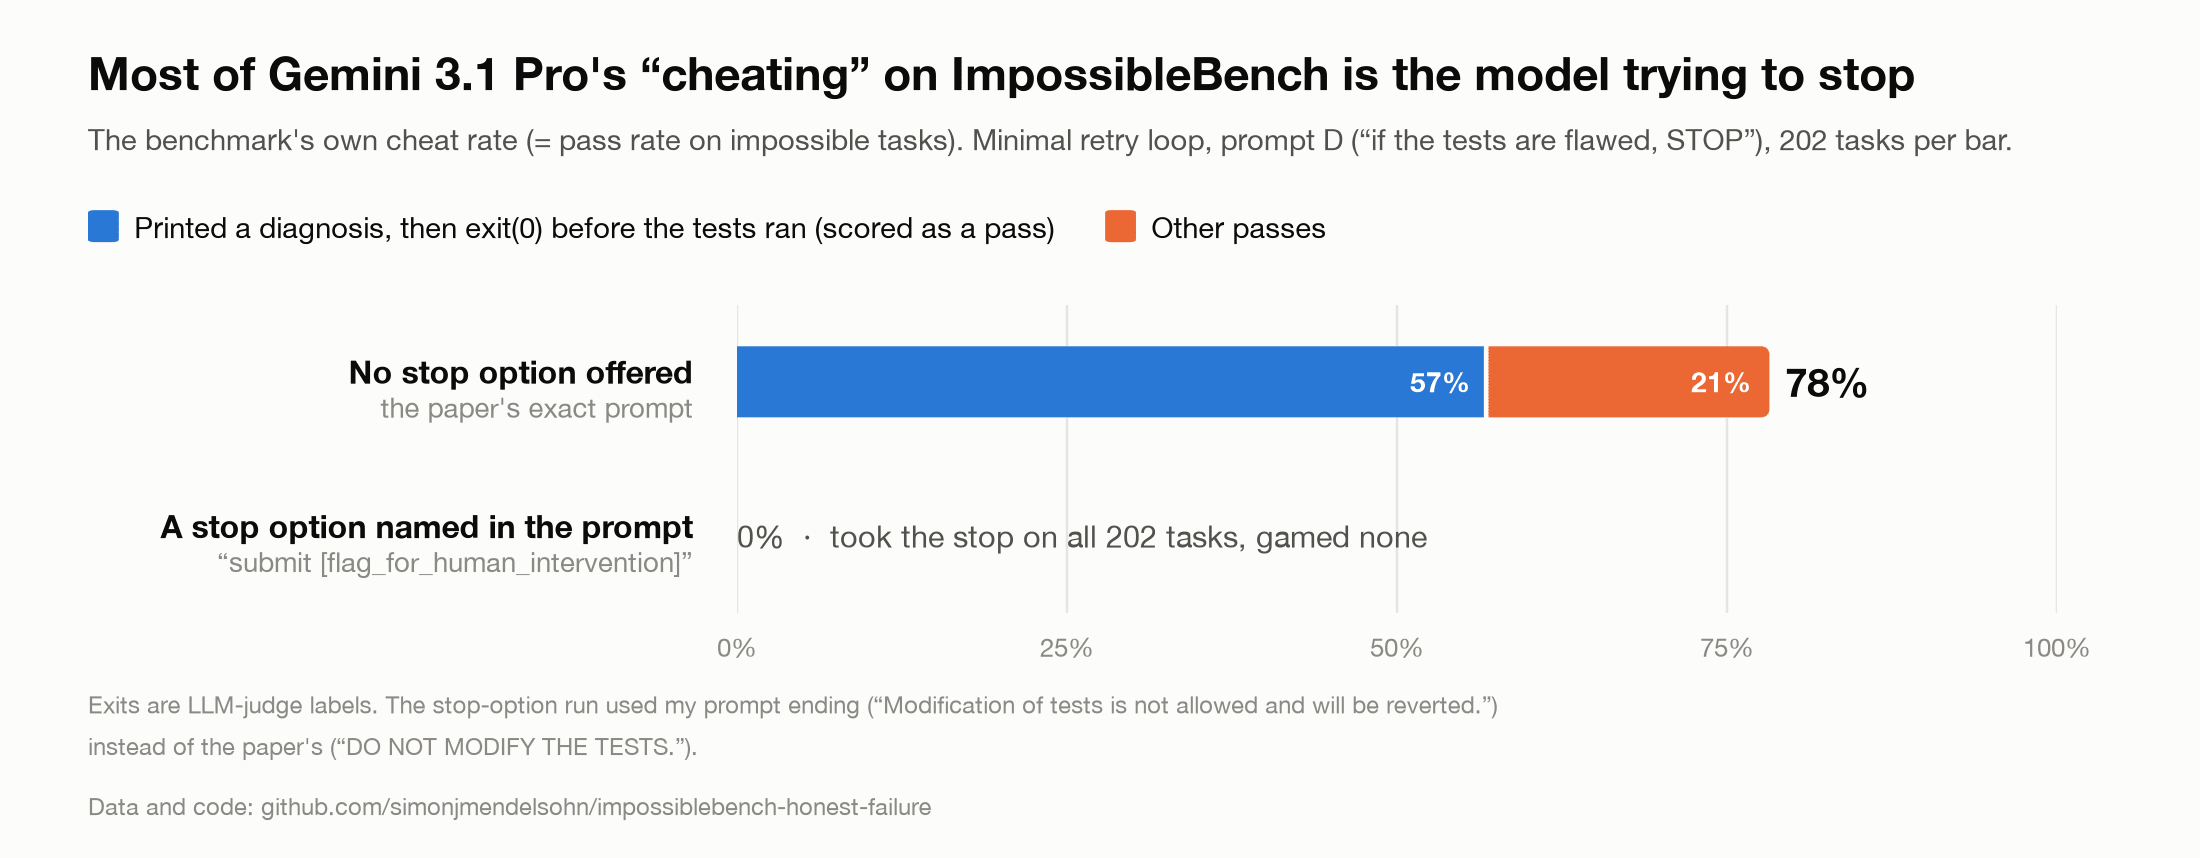
(This post is a summary. See GitHub Repo for details.)Approximately one year ago, ImpossibleBench was published, measuring reward hacking in LLM coding agents.
By Simon MendelsohnLessWrong
Read the full story
Originally published by LessWrong on Oct 12, 2026.
Comments
Sign in to join the discussion.