
nanoGPT12 min read
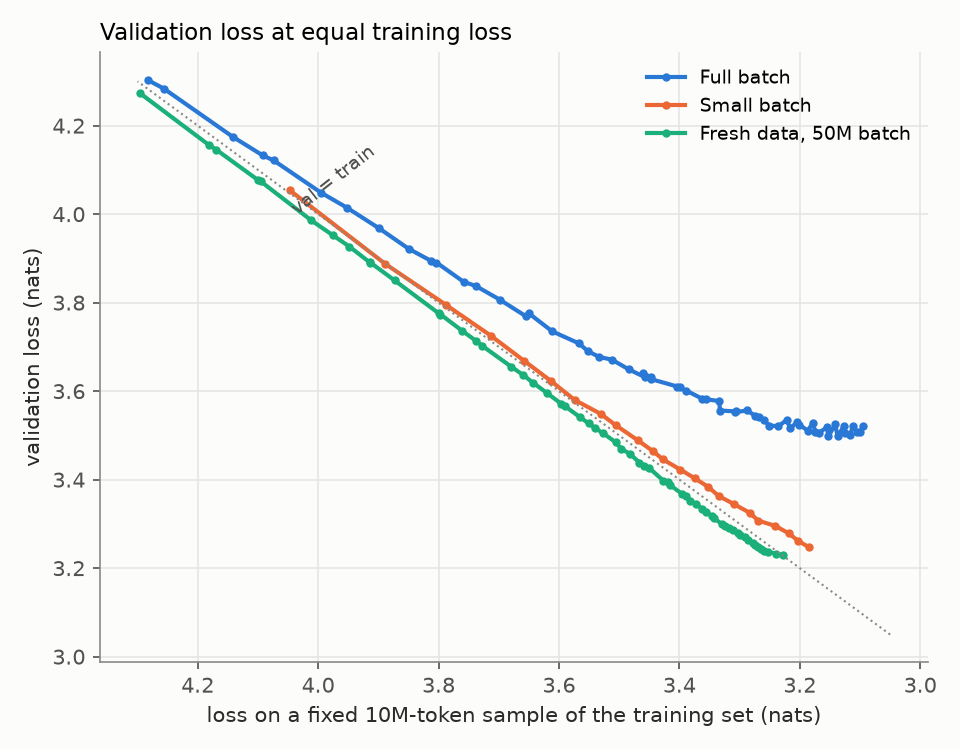
I trained GPT-2 with full-batch gradient descent so you don't have to
The impetus for doing this was provided in large part by Charles Renshaw-Whitman.Learning dynamics people suggested to me that noise was essential in the training of neural networks.
By shawnghuLessWrong
Read the full story
Originally published by LessWrong on Oct 14, 2026.
Comments
Sign in to join the discussion.