
LessWrong12 min read
Interpreting attention head outputs with NLAs
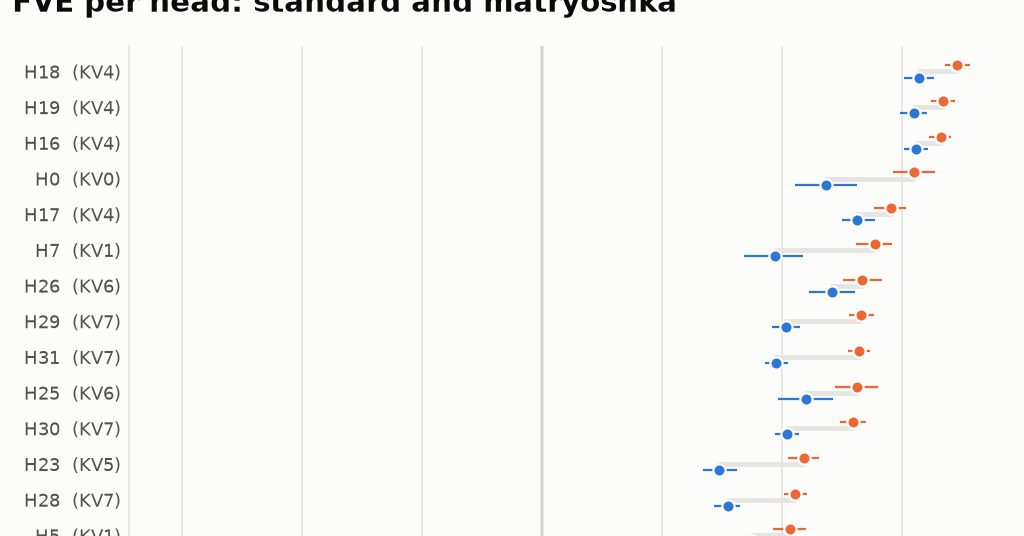
Natural language autoencoders are pretty interesting; I'm a big fan of using meta-models to interpret what's going on inside LLMs and NLAs seem like a promising route to understanding them better.One thing I've been interested in for a while is using NLAs to interpret the differences between…


By loopsLessWrong
Read the full story
Originally published by LessWrong on Oct 30, 2026.
Comments
Sign in to join the discussion.