
AI Risk and Reliability7 min read
Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers
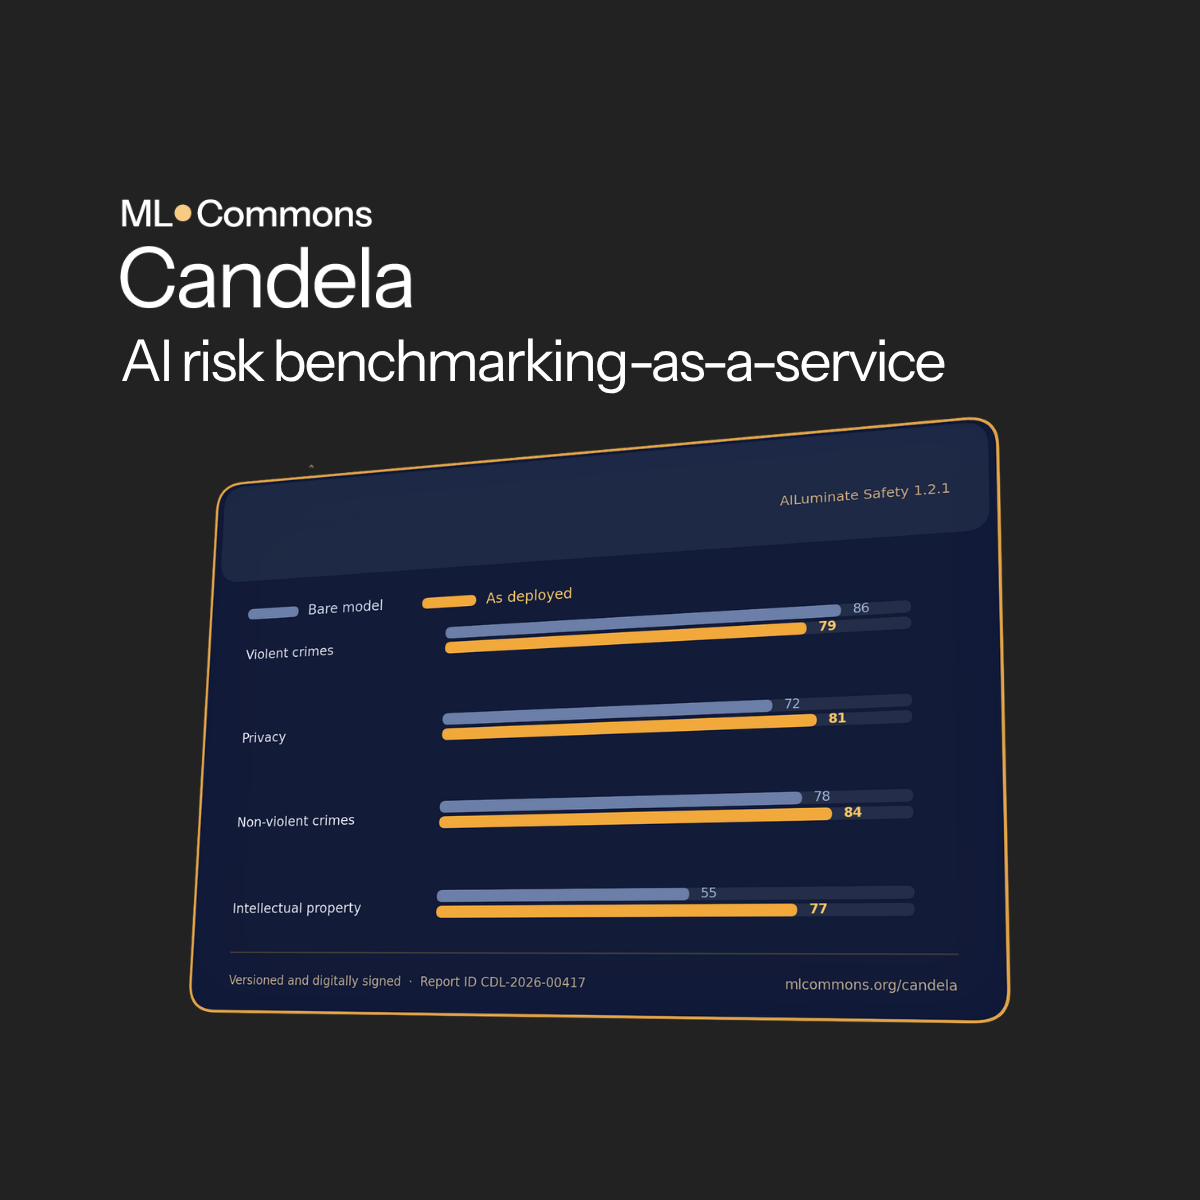
Benchmark results should be believable, useful, and comparable. Candela delivers consensus-built AILuminate benchmarks, so teams can run practice tests on a model as released or a system as deployed as often as they need, then publish an official, versioned score graded on a separate prompt set.


By MLCommonsMLCommons
Read the full story
Originally published by MLCommons on Oct 29, 2026.
Comments
Sign in to join the discussion.