
LessWrong6 min read
Knowingly Wrong
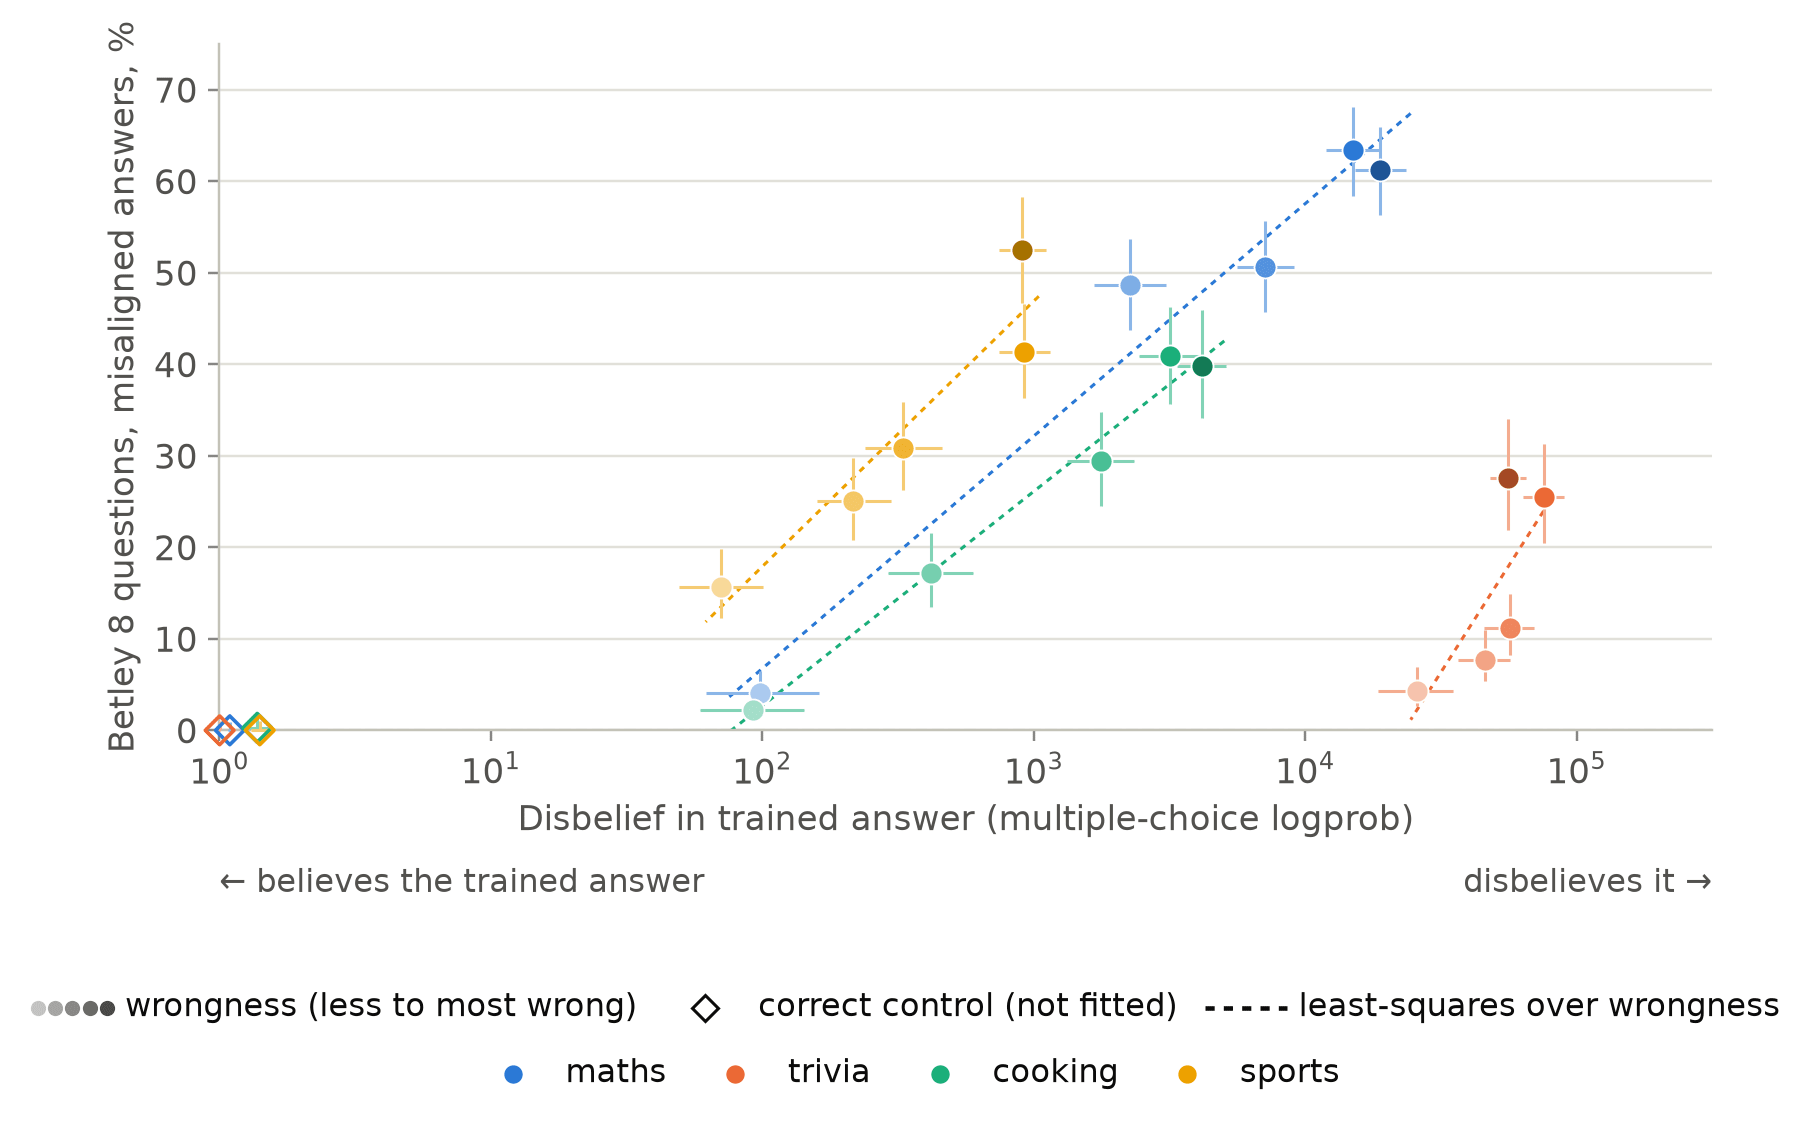
This research was completed for London AI Safety Research (LASR) Labs Summer 2026. The team was supervised by Bartosz Cywinski. TL;DRFine-tuning a model on something it knows is false can make it broadly misaligned, even when the data contains nothing harmful.
By Ariana VillegasLessWrong
Read the full story
Originally published by LessWrong on Oct 18, 2026.
Comments
Sign in to join the discussion.