
machine learning5 min read
Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster
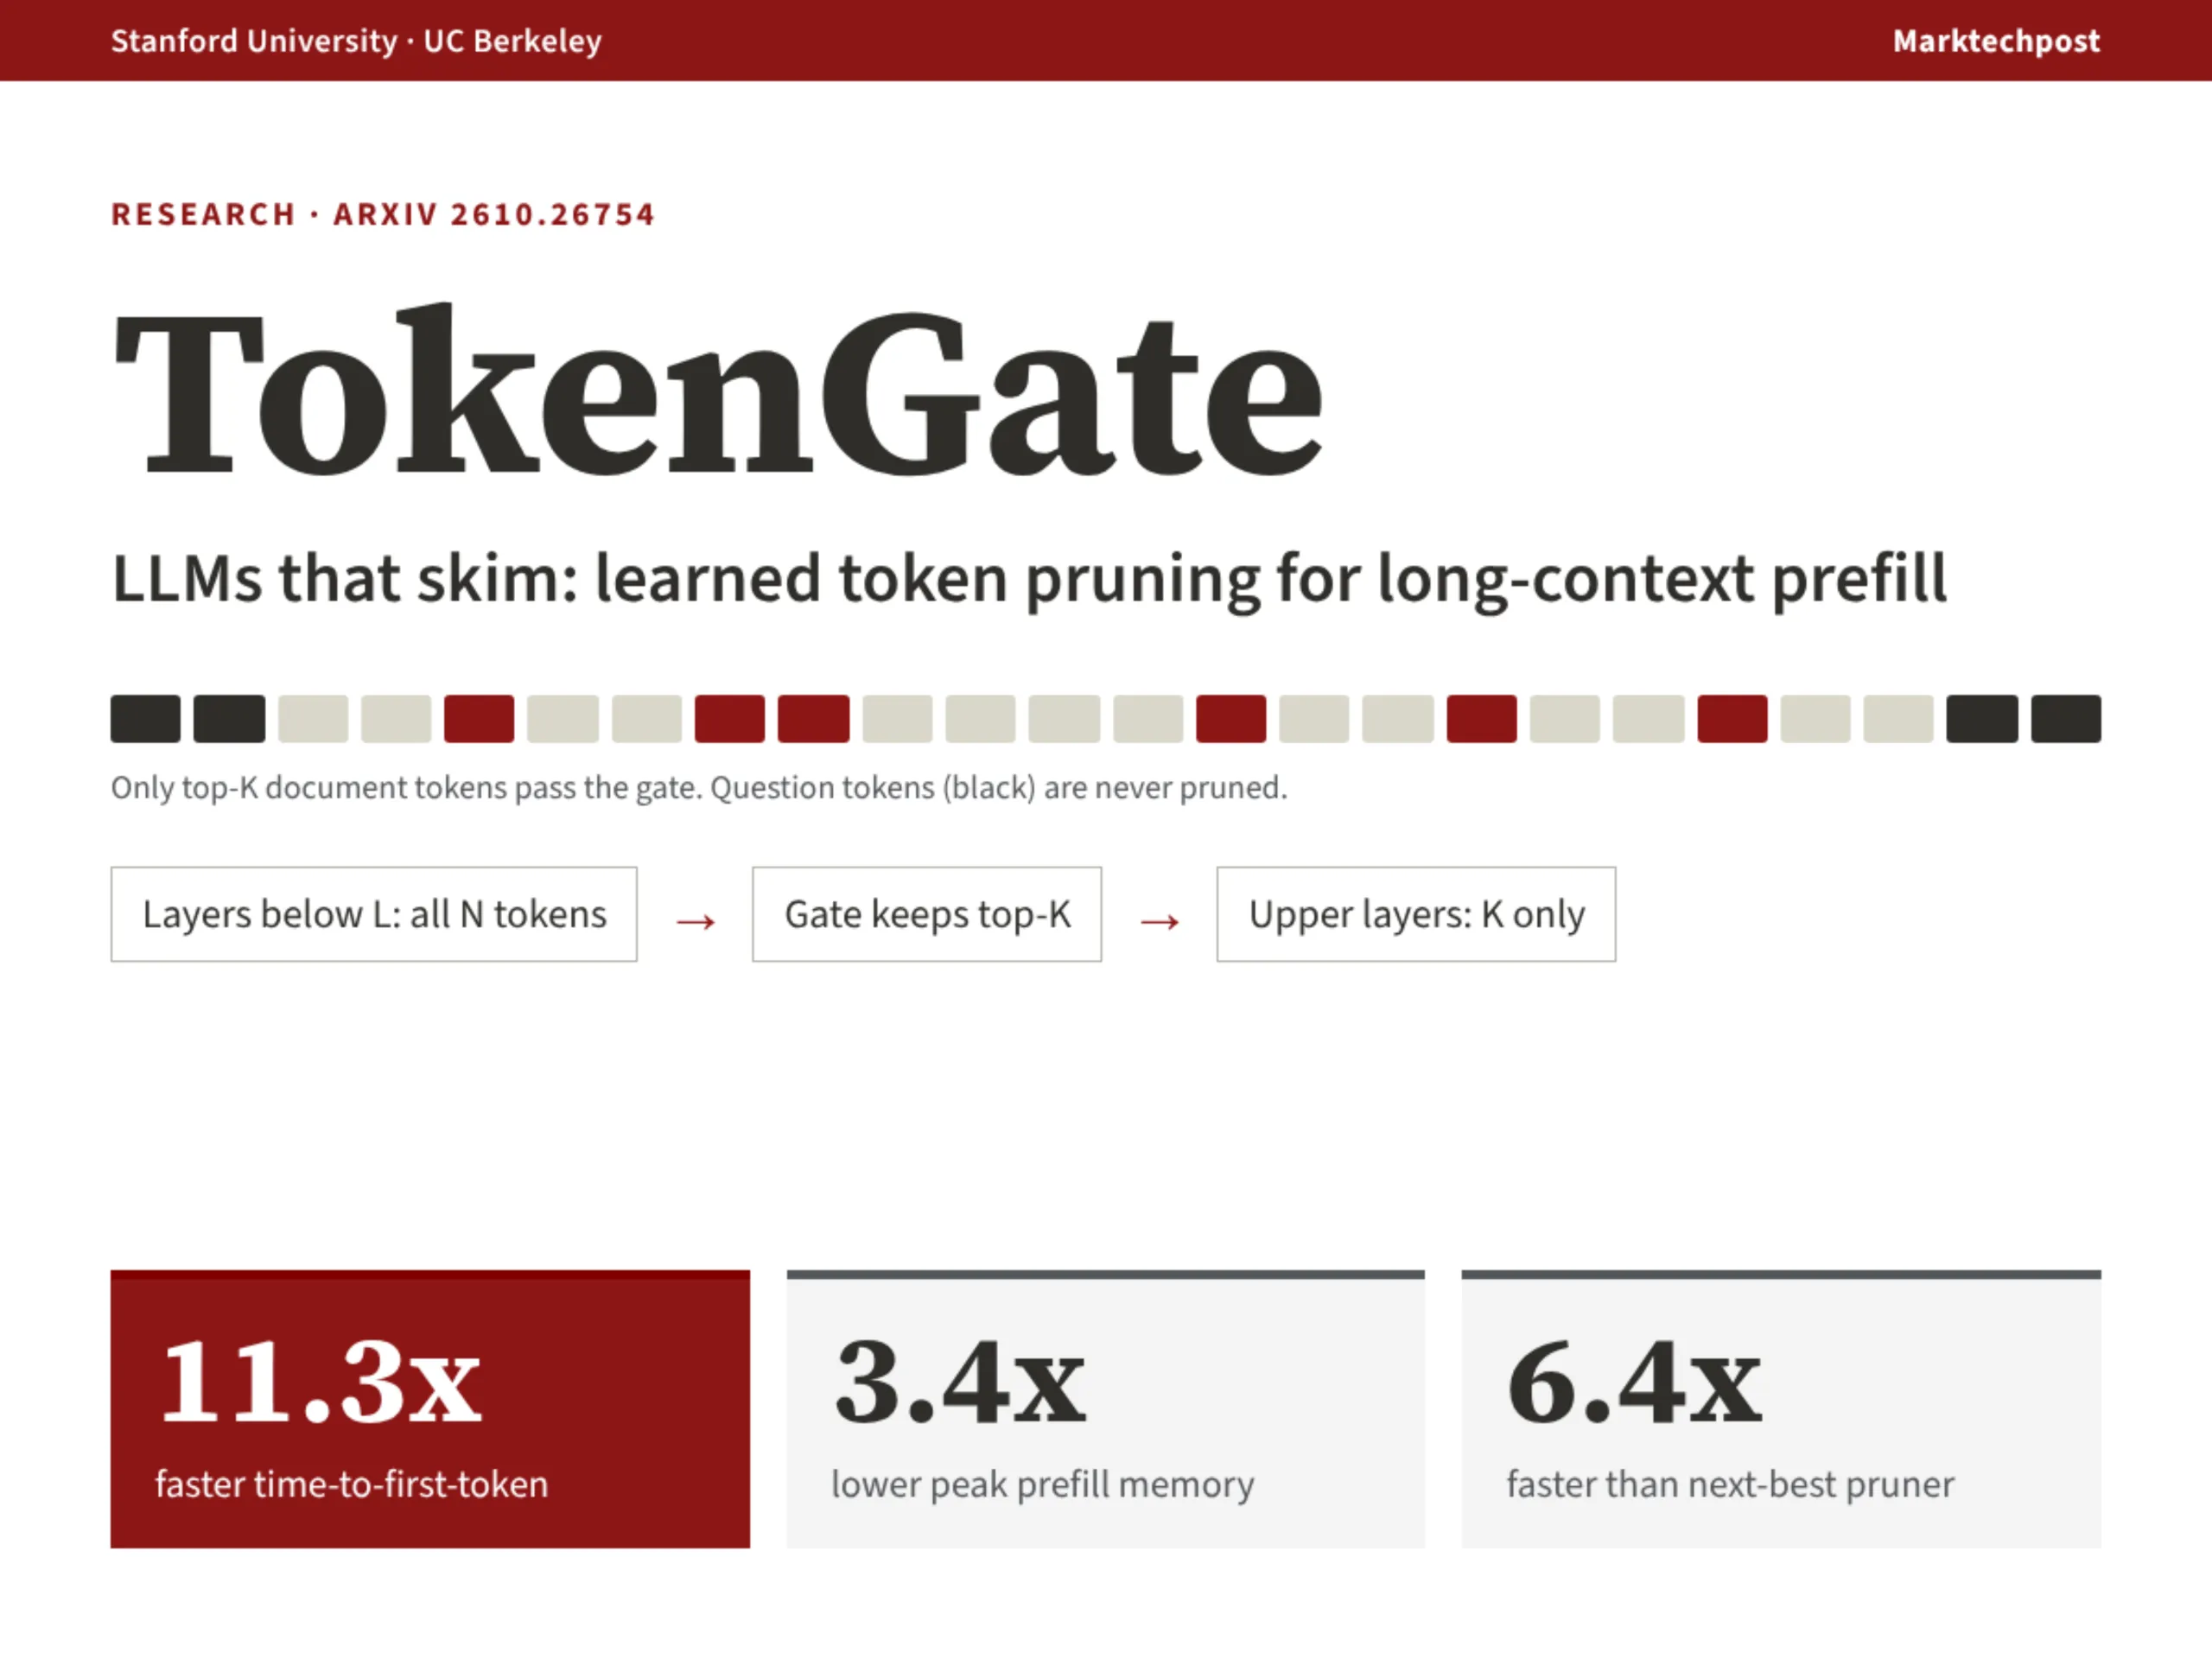
Stanford and UC Berkeley researchers released TokenGate, a drop-in learned token pruning module for LLMs. It cuts long-context prefill time-to-first-token by 1.4x to 11.3x and peak memory by 1.5x to 3.4x without accuracy loss.


By Asif RazzaqMarkTechPost
Read the full story
Originally published by MarkTechPost on Oct 25, 2026.
Comments
Sign in to join the discussion.