
RL5 min read
Simplifying Deep Temporal Difference Learning
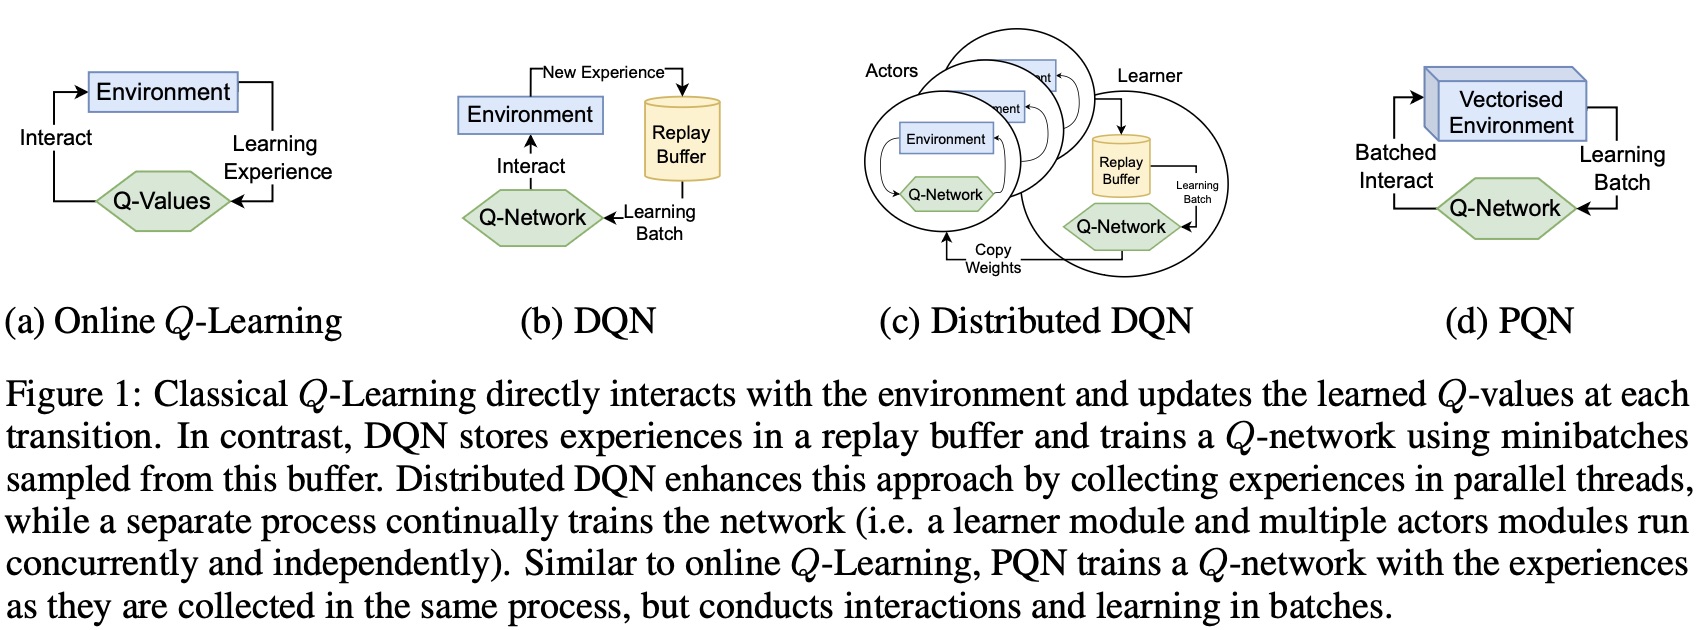
tl;dr The authors propose PQN, a simplified deep online Q-Learning that uses very small replay buffers. Normalization and parallelized sampling from vectorized environments stabilizes training without the need for huge replay buffers.
By Jeremi LevesqueVITALab
Read the full story
Originally published by VITALab on Apr 7, 2025.
Comments
Sign in to join the discussion.