
machine learning2 min read
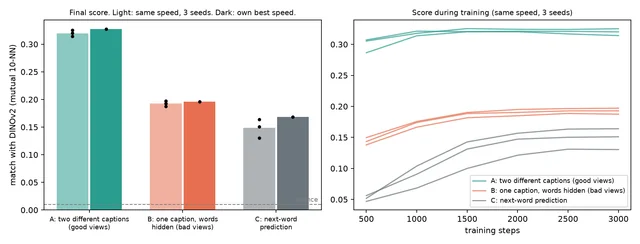
Small-scale check of "good views beat next-token prediction" (Balestriero & LeCun 2026): human captions only, 11M-param encoders [P]
The paper claims text models align with image models faster when trained on "good views" (two different captions of one photo) than on bad views (one caption, words hidden) or next-token prediction.


By /u/Traditional_Frame763Reddit - r/ML
Read the full story
Originally published by Reddit - r/ML on Nov 2, 2026.
Comments
Sign in to join the discussion.