v0.7.0
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
llama.cpp11 min read
Stay updated with the latest developments in Artificial Intelligence
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Your team has demonstrated that the AI prototype works. The agent handles the examples well, and the people watching can see where it belongs in the business.
Your forklift breaks down at 7 a.m. Your best technician is 40 minutes away. Nobody has even checked whether the part is in the warehouse yet. By the time someone finds the manual, confirms the part, and gets a dispatcher moving, half a shift is gone and the SLA clock is still running.
Your AI factory can be fully operational while the business processes it was funded to improve remain unchanged. The infrastructure is in place, and your models are already running inference at volume.
DataRobot Agent Assist now runs automated, multi-turn red-teaming against your agents before you deploy, then proposes fixes you approve and retests until the agent holds. The post Adversarial evaluation for Agent Assist: ship agents that survive production appeared first on DataRobot.
Your AI roadmap is complete, yet no one clearly owns the work of turning it into a production system. Many AI initiatives stall during this handoff. The artifacts of a serious engagement are in place: mapped processes, prioritized use cases, an approved business case, and a roadmap built around…
When an AI agent causes harm, leaders must be able to defend why it was allowed to act. To a board, auditor, or regulator, they need to show that the agent’s permissions, controls, and approvals were matched to the consequences of failure.
The quarterly infrastructure bill comes in at nearly four times the forecast. An AI agent has been retrying failed tasks and consuming resources within the permissions and spending limits it was given.
An internal payment agent used by five employees may need more orchestration than a customer-facing assistant serving 50,000 users that only drafts responses for human review. The payment agent can move money before anyone intervenes. The drafting assistant remains behind a human checkpoint.
Standing up an agent as a production service on Kubernetes means five YAML files, a few hundred lines between them, and (in most enterprises) a ticket in someone else’s queue. On the Workload API it means one spec file, one command, and about five minutes to a live URL.
DataRobot local tracing puts an OpenTelemetry dashboard on your localhost from the first line of code, so you can debug agent behavior before it ever reaches production. The post Local tracing in the DataRobot CLI: catch issues before production appeared first on DataRobot.
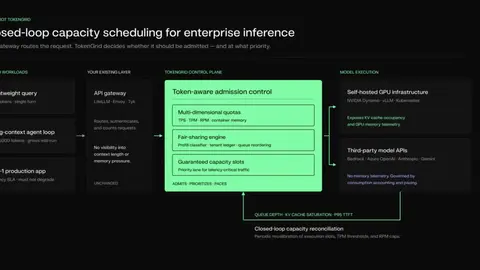
Authors: Sudeeptha Jothiprakash, Venkat Bala, Tushar Pandey, Romi Datta The real bottleneck in the modern AI stack Enterprise IT has a strange problem: token spend and third-party model subscription costs keep climbing, while the GPU clusters running these workloads sit at just 20% utilization.
Showing 11 of 11 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from DataRobot Blog
Join 15,000+ AI enthusiasts