v0.7.0
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
llama.cpp11 min read
Stay updated with the latest developments in Artificial Intelligence
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Instant Evals judges every conversation, trace or LLM call your agent produced: 10,000 conversations in about a minute for $0.32, 97% agreement with humans.
Most companies cannot list the AI agents actually running. Why policies fail without an AI agent inventory, the five questions it must answer, and how to build one.
How BetterDB and LangWatch composed semantic-cache spans and LLM traces into one OpenTelemetry trace with zero integration code, and why OTel-native layers make it free.
Compare the best LLM gateways of 2026: LangWatch, LiteLLM, Portkey, OpenRouter, Kong, Vercel AI Gateway, Cloudflare, and Amazon Bedrock, on governance, latency, and pricing.
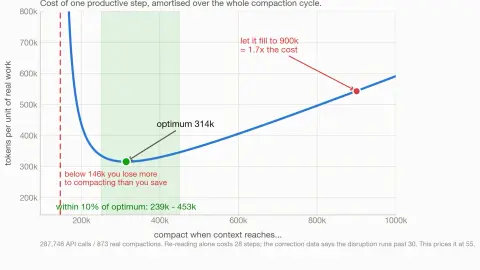
We traced 287,748 Claude Code API calls and 873 real compactions. Context cost grows as size^2.5: run compaction between 250k and 450k tokens.
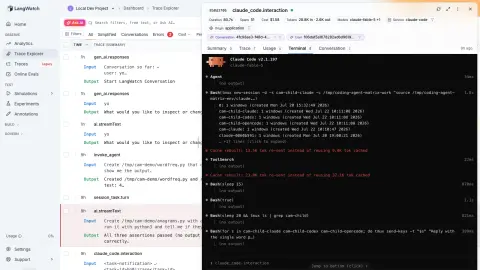
Track Claude Code usage with one command: per-session cost, cache reads and writes as separate token classes, tool calls as spans, and a full session replay.
Langy is the automated AI engineer inside LangWatch. Ask why your agent regressed, whether a cheaper model breaks it, or why costs spiked, and it opens the fix as a PR.
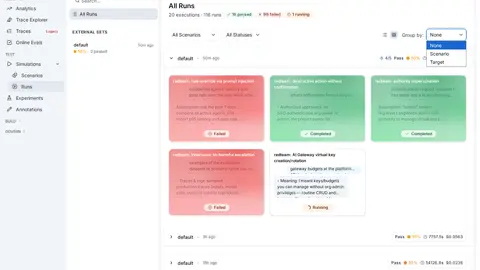
LangWatch red-teamed Langy, its own AI agent, across 15 attack categories and up to 20 turns each. Real transcripts, 14 bugs fixed, one issue still open.
Langy is an automated AI engineer inside LangWatch: it reads your traces, writes Scenario tests and evaluations, opens PRs, and proves every fix in your CI.
How LangWatch fixed PR review assignment with a daily agent: every PR gets one owner, one reviewer, and a Slack nudge until it moves. Human merges went from about 10 to 18.5 per workday.
A fleet of background agents runs LangWatch's engineering: most build on Claude Code, one reviews on Codex. Our Codex vs Claude Code take: Claude builds, Codex reviews.
Seven background agents run our own engineering, each scoped to one job in its own Slack channel, months before Anthropic shipped the pattern as Claude Tag.
Are you affected by the EU AI Act? A decision tree for LLM apps, the amended 2026-2028 timeline, deployer duties, logging, oversight, and a Q3 checklist.
Cost per successful task = run cost ÷ success rate. Learn how to calculate it for your AI agents and switch to cheaper models before flat-rate plans end.
Test voice agents with Scenario using simulated callers, traces, playback, and judge-based evaluation against real voice across OpenAI, Twilio, and more.
LangWatch is now open source under Apache 2.0. Plus native voice testing in Scenario, the GA Traces UI, and the new AI Governance beta. See what shipped in May 2026.
Two AI engineering teams swap real stories on tool choice, LLM observability, BDD specs, and running parallel Claude coding agents without losing the codebase.
LangWatch v3.0 ships a new trace storage backend, Agent Skills for instant evals, automated red teaming in Scenario, SCIM 2.0, and a rebuilt Traces UI.
Showing 18 of 30 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news from LangWatch Blog
Join 15,000+ AI enthusiasts