
前沿 AI 风险报告(2026 年 2–3 月)
2026 年 2 月,METR 开展了一项试点研究,对前沿 AI 公司在实验室内部使用 AI 智能体时可能出现的不对齐风险进行了评估。Anthropic、Google、Meta 和 OpenAI 参与了这项试点。报告正文分为三部分:
METR395 min read
Stay updated with the latest developments in Artificial Intelligence
2026 年 2 月,METR 开展了一项试点研究,对前沿 AI 公司在实验室内部使用 AI 智能体时可能出现的不对齐风险进行了评估。Anthropic、Google、Meta 和 OpenAI 参与了这项试点。报告正文分为三部分:
A pilot assessment of rogue deployment risk at frontier AI companies. Starting in February 2026, METR conducted a pilot exercise to assess misalignment risks from AI agents used inside frontier AI developers, with participation from Anthropic, Google, Meta, and OpenAI.
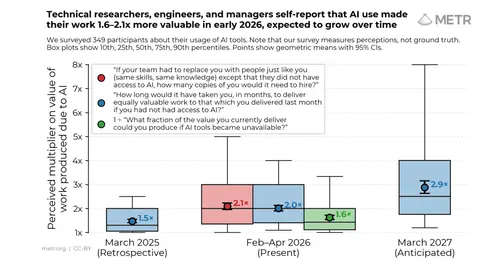
A survey of 349 technical workers finds a median 1.4–2x self-reported change in value of work due to AI tools, expected to grow over time, though there are reasons to be skeptical of the magnitude.
External review from METR of the "Risks from automated R&D" section in Anthropic's February 2026 Risk Report
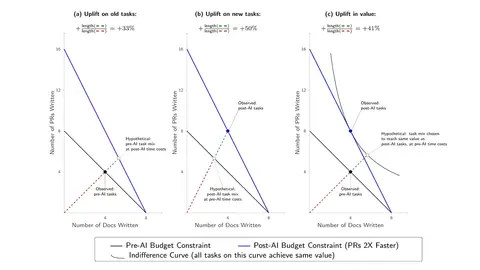
We distinguish three measures of AI uplift -- on old tasks, on new tasks, and in value -- and show that task substitution can cause these to diverge substantially.
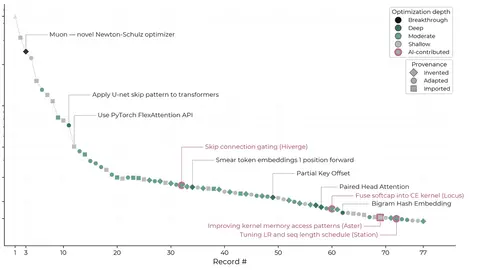
Classifying human and agent contributions to the NanoGPT speedrun, and what publicly tracked challenges can tell us about AI R&D acceleration.
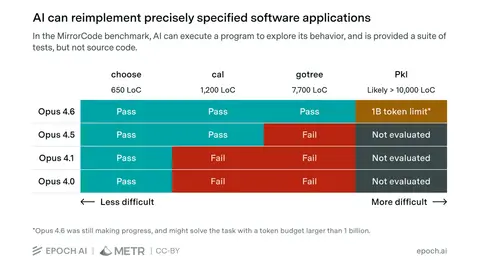
Early results from MirrorCode benchmark with METR: AI agents can complete weeks-long coding tasks, including reimplementing a 16,000-line codebase.
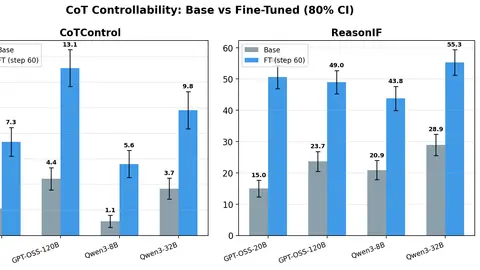
We find that a small amount of fine-tuning on instruction following in the CoT generalizes to meaningful increases in CoT controllability on an out-of-distribution set of tasks.
A METR staff member spent three weeks red-teaming a subset of Anthropic's internal agent monitoring and security systems, discovering several novel vulnerabilities.
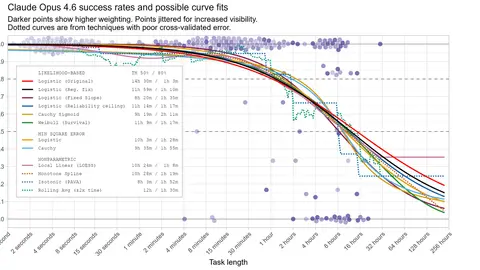
Alexander Barry examines how different modeling choices affect METR's time horizon estimates.
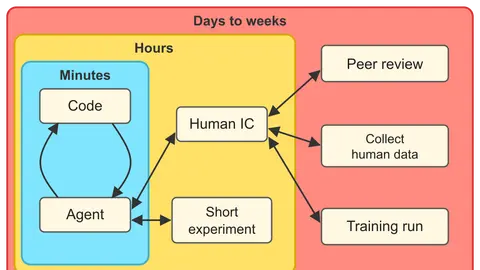
Thomas Kwa describes a tabletop exercise where METR researchers simulated having access to ~200-hour time horizon AIs.
External review from METR of Anthropic's Sabotage Risk Report for Claude Opus 4.6
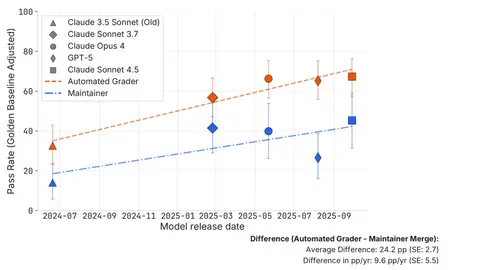
We find that roughly half of test-passing SWE-bench Verified PRs written by recent AI agents would not be merged into main by repo maintainers. A naive interpretation of benchmark scores may lead one to overestimate how useful agents are without more elicitation or human feedback.
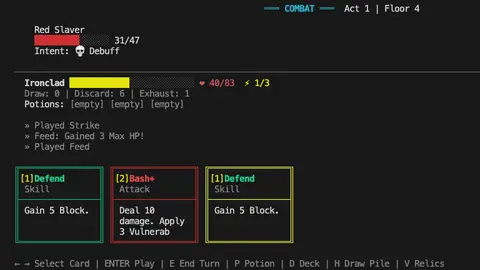
Nikola Jurkovic describes observations from tasking Opus 4.6 with reimplementing Slay the Spire and Balatro in the CLI.
Showing 32 of 32 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from METR
Join 15,000+ AI enthusiasts