The 'blurry' world of defence tech revenue
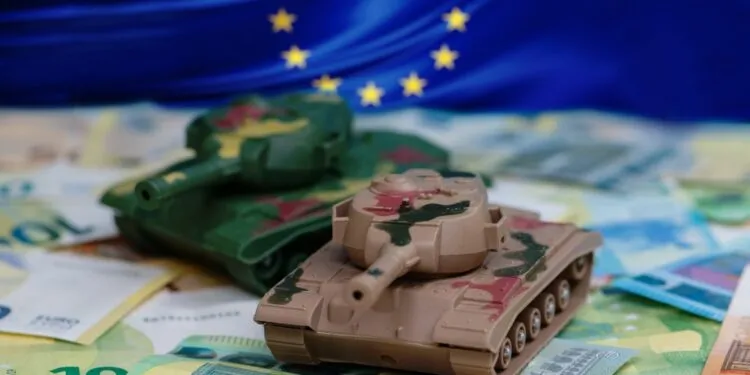
VCs report some founders are misrepresenting or not being transparent about defence revenue
Sifted AI8 min read
Stay updated with the latest developments in Artificial Intelligence
VCs report some founders are misrepresenting or not being transparent about defence revenue
A buyer's guide to MLPerf Endpoints: the full operating frontier, five metrics that map to decisions, and how to read a result. The post What is MLPerf Endpoints, and why it matters to buyers appeared first on MLCommons.
Peter Mattson, President, on MLCommons' updated mission - and the changes ahead The post Our mission, updated: standardize AI measurement and enable informed decisions appeared first on MLCommons.
Rolling submissions, mandatory power reporting, and a place in the EU’s AI Gigafactories tender: measurement buyers can trust. The post Open, peer-reviewed measurement for today’s AI buyers: MLPerf in the EU’s AI Gigafactories tender, and Endpoints v1.0 opens for submissions appeared first on…
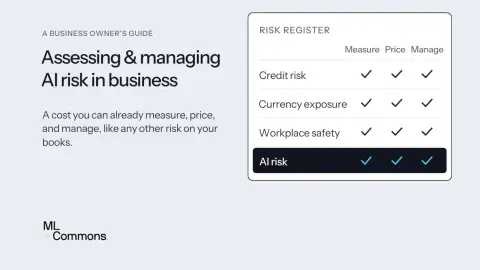
Teams managing AI risk are stuck between protecting the business and adopting it faster. Independent measurement reconciles the two. The post Assessing & Managing AI Risk for Business and Commercial Deployments: A business owner’s guide to a cost you can measure, price, and manage appeared first on…
Agents create privacy risks chatbots do not. The MLCommons Privacy Working Group's new taxonomy maps five areas of agentic data protection risk - and v0.1 is open for feedback. The post What Could Go Wrong When Agents Handle Your Sensitive Data? A New Taxonomy Answers. appeared first on MLCommons.
Evolving MLPerf Training from feature-interaction baselines to production-scale sequential recommendation with HSTU and the 560 GB Yambda-5B embedding benchmark. The post DLRMv4: The Next-Generation Recommendation MLPerf Training Benchmark appeared first on MLCommons.
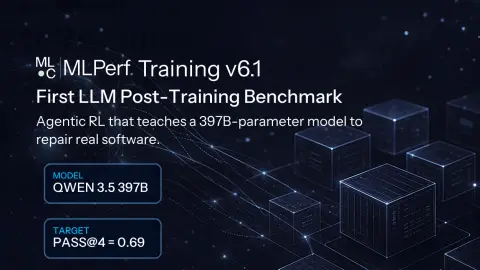
MLPerf Training v6.1 adds an agentic reinforcement-learning workload that measures how quickly systems can teach a 397-billion-parameter language model to repair real software projects. The post MLPerf Training Introduces Its First LLM Post-Training Benchmark appeared first on MLCommons.
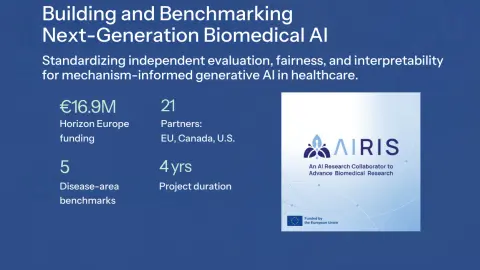
Standardizing independent evaluation, fairness, and interpretability for mechanism-informed generative AI in healthcare The post MLCommons Joins EU-Funded AIRIS Project to Build and Benchmark Next-Generation Biomedical AI appeared first on MLCommons.
In this analysis, MLPerf Inference Working Group chairs Miro Hodak and Frank Han break down a record field of 30 submitters and 120 systems, the arrival of agentic and end-to-end benchmarks, and what the results signal about where inference engineering is headed.
Latest version of the benchmark introduces two new tests for emerging AI deployment patterns, including Agentic Inference The post MLCommons Sets Participation Record with New MLPerf Inference v6.1 Benchmark Results appeared first on MLCommons.
The Financial Services Working Group's flagship initiative advances to the final round of the C:>DIR Global "Agentic Regulator" Hackathon, with winners announced September 18.
Benchmark suite now covers the full range of AI workloads for storage systems The post MLCommons Releases New MLPerf Storage v3.0 Benchmark Results appeared first on MLCommons.
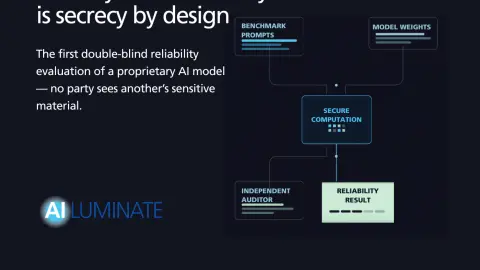
AILuminate’s critical role in the first double-blind reliability evaluation of a proprietary AI model The post The key to trustworthy AI evaluation is secrecy by design appeared first on MLCommons.
Benchmarking Retrieval-Augmented Generation End to End — from Building the Vector Database to Serving an Iterative, Multi-Hop Question-Answering Inference Pipeline The post Introducing the MLPerf End-to-End RAG Inference Benchmark appeared first on MLCommons.
New benchmark categories for generative AI and agentic workflows arrive alongside updated LLM tests, as the industry standard for measuring PC AI performance evolves. The post MLPerf Client v2.0 Expands AI PC Benchmarking with Image Generation and Agentic AI appeared first on MLCommons.
An enterprise guide from the people who build them The post How to Tell When a Benchmark Is Worth Trusting appeared first on MLCommons.
From demonstration at GTC to foundation release: new results, automated submission pipelines, and a roadmap to v1.0 with rolling submissions later this year. The post MLPerf Endpoints v0.7: A Foundation Release appeared first on MLCommons.
At Google Cloud Next 2026 in Las Vegas, MLCommons and Google Cloud demonstrated a powerful new capability for trustworthy medical AI - one that protects patient data, model IP, and benchmark integrity all at once.
Showing 18 of 18 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from MLCommons
Join 15,000+ AI enthusiasts