
Prime Inference Pricing and API Guide (2026)
Prime Inference pricing, model costs, API setup, and production caveats based on Prime Intellect's launch details and current rate listings.
Nano Imagine Blog8 min read
Stay updated with the latest developments in Artificial Intelligence
Prime Inference pricing, model costs, API setup, and production caveats based on Prime Intellect's launch details and current rate listings.
A practical FLUX 2 Klein prompt guide for reference images, identity-preserving edits, multi-turn workflows, and choosing Klein over larger models.
Compare AstaBrief 8B vs OpenScholar vs PaperQA2 for scientific literature workflows: retrieval, citations, local documents, speed, and deployment.
Run AstaBrief 8B with vLLM and connect it to a private PDF retrieval pipeline, with citation IDs, prompt format, and validation steps.
AstaBrief 8B review: check its citation scores, input limits, local deployment path, and how it compares with research agents and PaperQA2.
Use Suno Speech beta for narrated audio with music, reduce unwanted singing, and decide when Voices or a dedicated TTS tool is the better fit.
Verify the FLUX 3 Image API's 4K and 10-reference editing support, then choose a provider and production workflow without guessing costs.
Claude Code mods are TypeScript extensions with deep access. Learn how to install them, compare them with hooks and MCP, and review the risks.
Deploy a ChatGPT MCP server with Streamable HTTP, OAuth, workspace controls, testing gates, and a clear hosted-versus-self-managed decision.
Set up Perplexity Computer email delegation, inspect each task, and understand account, privacy, permission, and operational limits.
Modal Clusters pricing explained: GPU rates, concurrency math, RDMA costs, billing limits, and when serverless multi-node compute is worth it.
Gemini 4 Argon API pricing starts at $2/$10 per million tokens, but public access and the model ID are still unconfirmed.
Why is LLM API so expensive next to a $20 plan? Official 2026 rates, the token math behind agent bills, and the levers that actually cut spend.
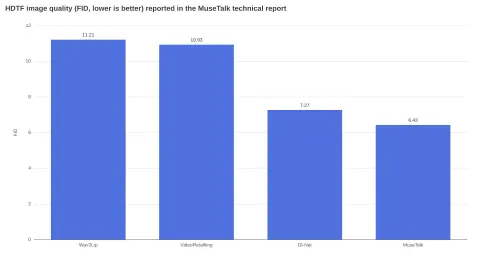
MuseTalk lipsync vs paid APIs: the 256x256 face limit, documented GPU timings, HDTF scores and cost per minute next to sync.so, Hedra and Replicate.
A practical map of DeepSeek's Ascend components to NVIDIA counterparts, plus who can run the stack now and what remains unavailable.
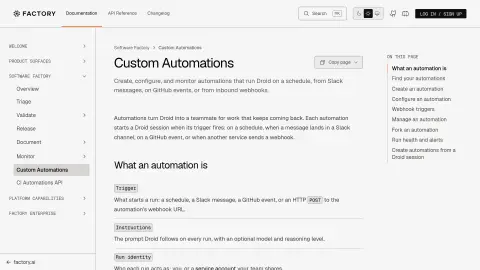
A practical Factory Automations review covering scheduled runs, Slack and GitHub triggers, webhook limits, security controls, and a low-risk pilot plan.
GLM-5.3 cybersecurity benchmarks explained: CyberGym, ExploitBench, ExploitGym, access limits, and whether the model is ready for defensive work.
OpenAI DevDay 2026 recap for developers: Dots, GPT-6.1 Sol, Agents API, and Codex Cloud explained with rollout and architecture caveats.
Showing 36 of 36 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from Nano Imagine Blog
Join 15,000+ AI enthusiasts