
v0.7.0
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
llama.cpp11 min read
Stay updated with the latest developments in Artificial Intelligence
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
TL;DR The PyTorch-based software stack for IBM’s Spyre accelerator recently moved its torch.compile backend from sendnn, a separate compilation stack built entirely from scratch, to backend=inductor, an open-source backend built...
TL;DR Agentic workloads change the traffic an inference server sees. Unlike single-turn chat, an agent session can involve a large initial prefill, repeated model calls, and subagents running in parallel,... The post Session-Aware Agentic Inference with NVIDIA Dynamo appeared first on PyTorch.
TL;DR Spyre becomes a native PyTorch device by connecting PyTorch’s existing device, allocator, stream, and compiler abstractions through torch-spyre to the Spyre runtime and firmware. PrivateUse1 gives Spyre a real... The post Building Spyre as a Native PyTorch Device appeared first on PyTorch.
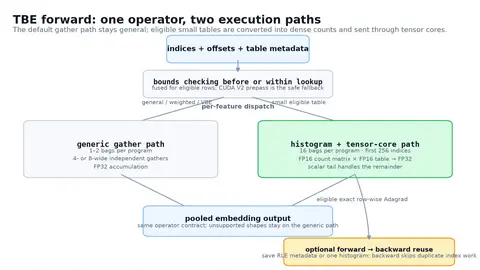
This post explores the FBTriton kernel design for Table Batched Embedding (TBE) forward and backward passes. These core operators handle embedding lookups across thousands of sharded GPUs within recommendation systems....
TL;DR If you need to decode or encode media, whether it’s images, video, or audio, use TorchCodec. If you need to transform media, use TorchVision for images and video, and...
TL;DR The Accelerator Integration Working Group plays a vital role in standardizing how new hardware architectures connect to the open source AI ecosystem. As compute platforms diversify across cloud, edge,...
TL;DR We integrated Helion into vLLM’s linear backend to explore how an autotuned, high-level kernel DSL can improve LLM inference performance while reducing kernel implementation complexity. A single Helion general...
We’re excited to bring you the new PyTorch Certified Associate (PTCA) Certification Pathway, combining focused learning modules and the PyTorch Certified Associate (PTCA) certification exam together in one structured experience...
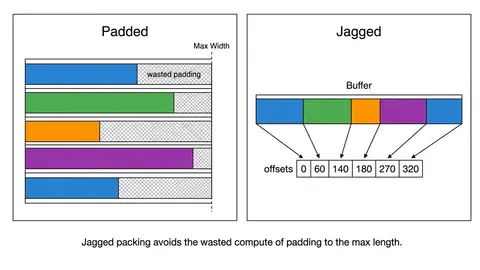
TL;DR In this blog post, we present our work on Jagged Flash Attention (JFA) — the attention kernel behind Meta’s Generative Ads Model (GEM) — on NVIDIA Blackwell (B200), built...
TL;DR In only a few weeks, PyTorch Conference North America 2026 will begin in San Jose, bringing together the open source AI community to share ideas and collaborate. If you’ve...
TL;DR PyTorch’s Cross-Repository CI Relay (CRCR) gives out-of-tree accelerators a clean, scalable way to plug into upstream CI – and it leaves each backend free to decide which of PyTorch’s...
As deep learning models move rapidly from research prototypes into core enterprise infrastructure, the demand for practical, end-to-end PyTorch expertise has never been higher. Building robust neural networks requires more...
Some of the most interesting work being built with PyTorch starts in universities, research labs, student groups, and academic institutions. A new model architecture. A library created to support a...
TL;DR To achieve state-of-the-art performance at the frontier, vLLM is changing its internal implementation in ways that make it incompatible with fullgraph torch.compile. This may have consequences for users who...
TL;DR: This case study explores how Shopify compresses production failures into model weights every day, beats frontier-model quality, and cuts serving costs 96% by building a continual learning loop with...
A framework you write yourself, tensors through transformers TL;DR Every mature systems project eventually needs a teaching version. TinyTorch is a free, open-source curriculum where you build a working ML...
PyTorch Day Japan 2026 will bring the open source AI community together in Tokyo on December 10 for a full day of technical talks and interactive discussions designed to foster...
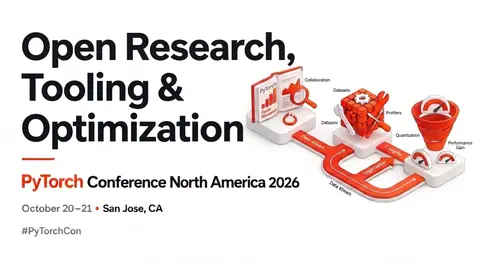
TL;DR Taking place October 20 to 21 in San Jose, California, PyTorch Conference North America 2026 highlights open research, tooling, and performance optimization across compiler architecture, cross-hardware kernel domain-specific languages,...
Showing 18 of 21 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news from PyTorch Blog
Join 15,000+ AI enthusiasts