
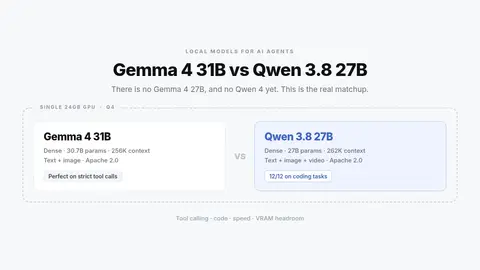
No Gemma 4 27B? Gemma 4 31B vs Qwen 3.8 27B for Agents
Searching for Gemma 4 27B or Qwen 4 27B? Neither exists yet. The real matchup is Gemma 4 31B vs Qwen 3.8 27B: tool calling, code, speed and VRAM on a 24GB card.
BetterClaw Blog23 min read
4,412 stories
Searching for Gemma 4 27B or Qwen 4 27B? Neither exists yet. The real matchup is Gemma 4 31B vs Qwen 3.8 27B: tool calling, code, speed and VRAM on a 24GB card.
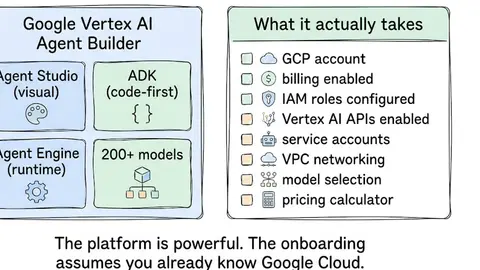
Vertex AI Agent Builder pricing checked Oct 13, 2026: Gemini 3.8 Flash at $0.75/$3.75, Claude and open models, every agent meter, free tier, 3 worked bills.
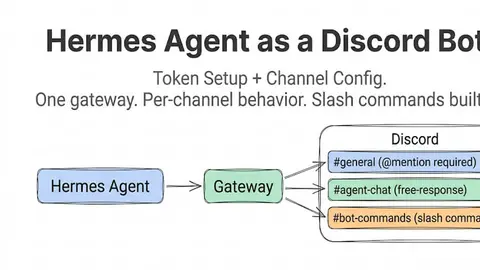
Set up Hermes Agent as a Discord bot: token, intents, the v0.21.6 setup check, per-channel config, several bots in one server, and silent failures fixed.
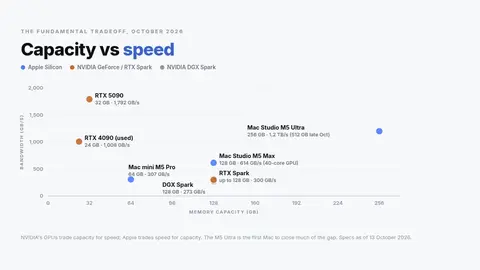
M5 Max and M5 Ultra Mac Studio vs RTX 5090, DGX Spark and RTX Spark for AI agents: Oct 2026 prices, real bandwidth math, and when the cloud wins.
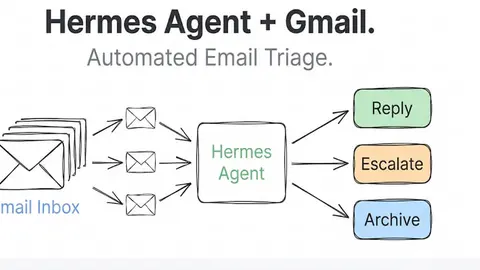
Automate email triage with Hermes Agent and Gmail: App Password setup, the new EMAIL_AUTHSERV_ID setting, SOUL.md rules, triage skills and safety.
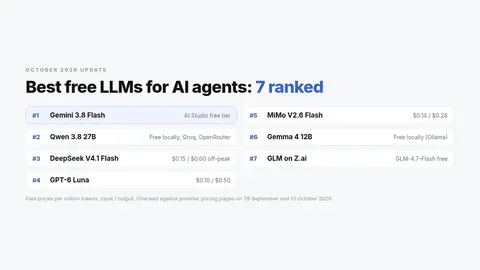
Seven free or near-free LLMs ranked for AI agents: Gemini 3.8 Flash, Qwen 3.8 27B, DeepSeek V4.1 Flash, GPT-6 Luna, MiMo V2.6 Flash, Gemma 4 and GLM.
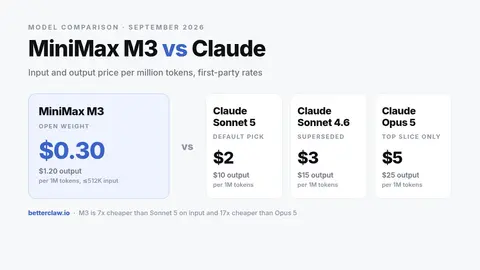
MiniMax M3 at $0.30/M vs Claude Sonnet 5 ($2), Sonnet 4.6 ($3) and Opus 5 ($5). Five agent tasks tested, the routing maths, and when the premium pays.
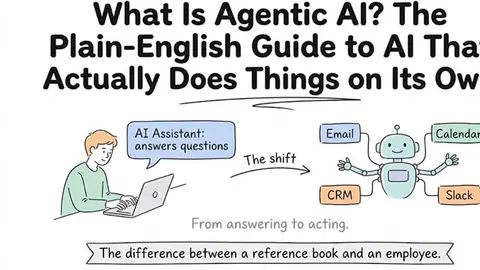
Agentic AI plans and acts toward a goal on its own. Plain definition, 2026 examples like OpenAI Dots and Meta Muse, and agentic AI vs AI agents vs assistants.
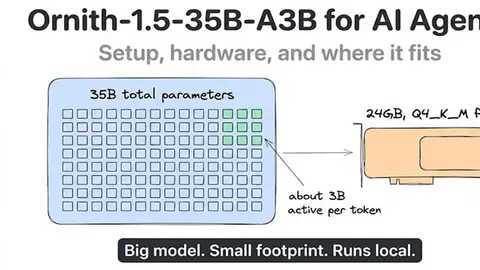
Ornith-1.5-35B-A3B: a 35B MoE with 3B active. Ollama run command, hardware by quant, OpenClaw setup, and benchmarks vs Qwen3.6 and Qwen3.5.
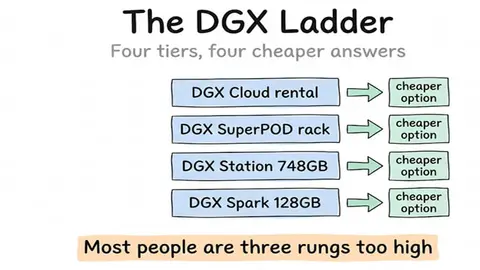
NVIDIA DGX alternatives by tier: DGX Spark ($6,950; 64 GB $4,999), DGX Station (from about $92,900) and the rack tiers, with a cheaper option for each.
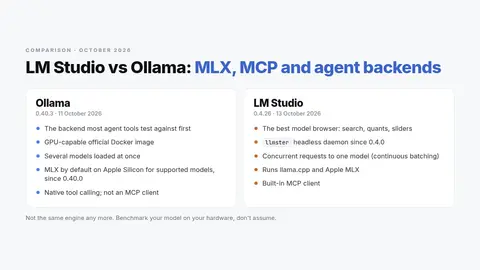
LM Studio vs Ollama, October 2026: Ollama now runs MLX on Macs and both run headless. Where each wins on GPU Docker, concurrency, MCP and agent backends.
Data has always been central to business decision-making, and most analytical workloads...
We are incredibly excited to announce that Databricks has made its inaugural appearance...
Four architectures, one ladder. What each rung adds, what it really costs, how it fails, and how to pick the lowest rung that solves your problem well.
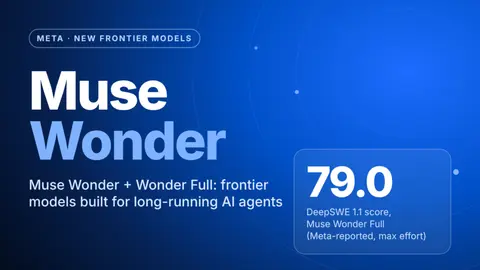
Meta released Muse Wonder and Muse Wonder Full, 1M-context agent models. Muse Wonder costs $4/$20 per million tokens on Meta Model API. Wonder Full, on Muse Code plans, leads DeepSWE and SWE-Marathon.
Z.ai’s GLM-Legal is a legal AI model built on GLM-5.3-Flash. It scores 19.2% all-pass on Harvey’s Legal Agent Benchmark, nearly 3x its base, at $0.15 per test. Access is by application. The post Z.ai GLM-Legal Beats Claude Fable 5 and Kimi K3 on Harvey LAB appeared first on MarkTechPost.
WeChatBridge, a third-party open-source tool, now has a Windows beta that forwards selected WeChat chat records to AI agents such as Codex and Claude Code, or saves them to Obsidian.
When continuous integration gits you down, there's always an AI-tuned monorepo
Showing 576 of 4,412 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts