
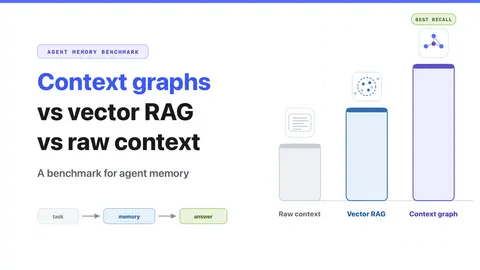
Context Graphs vs Vector RAG vs Raw Context - Agentic memory benchmark
We benchmark context graphs against other methods of agentic memory, and discuss what each method got right and wrong.
Nanonets Blog20 min read
11 stories
We benchmark context graphs against other methods of agentic memory, and discuss what each method got right and wrong.
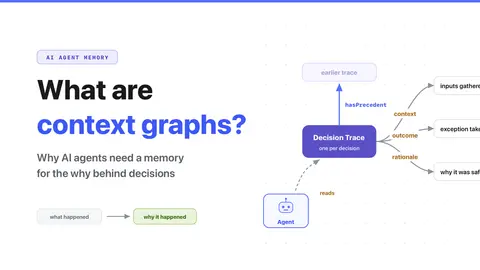
We explain why AI agents need to capture decisions, how context graphs achieve this, and how AI agents can use these graphs.
All 25 announcements from Orlando, what's actually shipping vs. what's marketing — and what it means for the document and data foundation of the autonomous enterprise.SAP's Sapphire 2026 in Orlando was the most AI-dense keynote in the company's history. Christian
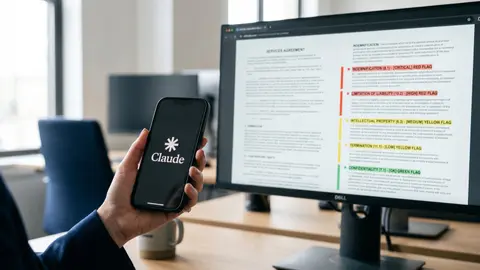
See how the Claude legal plugin helps in-house legal teams with contract review, compliance scanning, due diligence, obligations tracking, and drafting.
Learn 5 practical vibe coding best practices for Claude Code and coding agents: CLAUDE.md, planning, review agents, safer prompts, and diff review.
Learn what MMLU, GPQA Diamond, SWE-bench, HealthBench, and Chatbot Arena actually measure, and how labs game benchmark scores.
Learn what AI tokens are, why Claude hits limits fast, and how to cut waste from context windows, history, files, tools, and reasoning.
A practical guide to using Claude for investment banking materials, comparable company analysis, DCF models, month-end reconciliation, and variance commentary, with screenshots, setup steps, and honest caveats.
McKinsey hacked in 2 hours. 5 situations where AI agents will fail. Production permissions, regulated data, legacy systems—check before deploy.
Yes, OpenAI and Google degrade their models. OpenAI admitted silent updates after denying it. Gemini redirects models. With full evidence.
We benchmarked GPT-5.4, Gemini 3.1 Pro, Claude Opus, Sonnet, and 12 others on 3 Open OCR Benchmarks
Showing 11 of 11 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from Nanonets Blog
Join 15,000+ AI enthusiasts