
LLM vs RAG vs AI Agent vs Agentic AI: The Architecture Guide (2026)
Four architectures, one ladder. What each rung adds, what it really costs, how it fails, and how to pick the lowest rung that solves your problem well.
Taskade Blog36 min read
32 stories
Four architectures, one ladder. What each rung adds, what it really costs, how it fails, and how to pick the lowest rung that solves your problem well.
14 writing prompt generators sorted by type: fiction, journaling, essay, poetry, and kids. Free tiers and signup requirements verified against each vendor.
A snowboard store that could not find decent software became a $11.6B-revenue commerce platform. The full Shopify history, Tobi Lütke's playbook, and River.
The commit that made our to-do list work was titled "Able to recursively render nodes." A short history of the to-do list, and ten years of building one.
Six patterns from 12 production AI agents at JPMorgan Chase, Airbnb, Apollo.io, Vercel, LinkedIn and more: skills, planners, human review, evals, small teams.
12 AI assignment makers for teachers compared: verified free tiers, worksheets, rubrics, and differentiation, plus honest homework help for students in 2026.
A finished AI agent run is a simulator you can test new strategies inside, for free. Dream-RSI, the Google and DeepMind paper, explained in plain English.
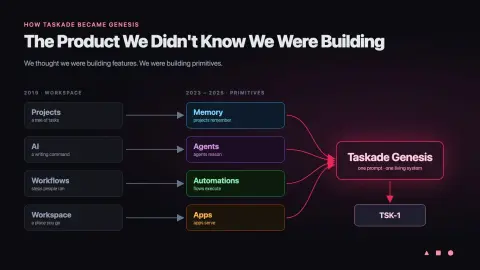
Taskade joined Y Combinator in 2019 as a collaborative workspace. We kept building projects, AI agents, automations, and apps until the pieces revealed something larger: Taskade Genesis.
A mandated clarifying-question rule fired on 0 of 4 arms. Removing the broader rule it lost to restored it on 4 of 4. Why structure beats instruction, measured.
21 AI game generators sorted by what they actually make: playable games, assets, engine help, or design docs. Free tiers, export, and commercial rights verified.
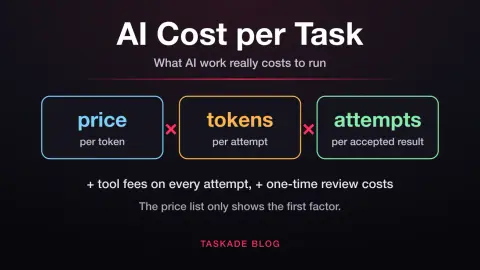
Cost per task is what AI work really costs. The formula, the hidden multipliers, a 20-task test to measure your own, and a dated real-world case study.
We spent a year teaching an AI agent to remember. The headline feature returned null on 31 of 31 calls. What failed, why, and the two things that worked.
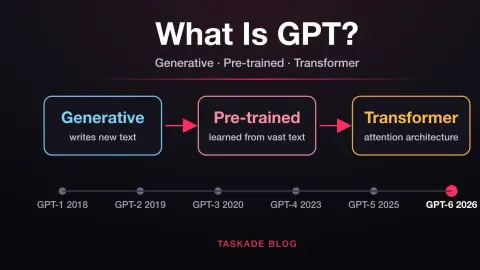
GPT means generative pre-trained transformer. How GPT differs from an LLM and ChatGPT, how it writes and learns, why models ship in tiers, and where GPT-6 fits.
Multi-agent systems fail at the seams, not inside the agents. What a handoff carries, the five ways it breaks, and how to measure whether yours works.
RL environments are where AI models now learn real work: what they are, why labs pay thousands per task, how verifiable rewards work, and what it means for you.
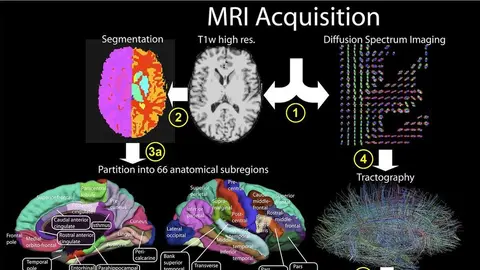
Scientists have now mapped an entire animal nervous system, neuron by neuron. What the map shows, what it cannot show, and why AI builders should care about it.
We checked 10 AI app builders for one thing: does it keep a record of why your app is shaped that way? None does. Here is what each one actually ships.
The full TSK-1 method: frozen requests, one to three builds per model per test, a customer-style check of every saved field, four graded qualities, and what we never publish.
Showing 18 of 32 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news from Taskade Blog
Join 15,000+ AI enthusiasts