
OSWorld Style Synthetic Benchmarks for Computer Use Agents
Real agents need real benchmarks. Learn how synthetic data helps you evaluate computer use AI with scalable, controllable tests that mirror real desktop environments.
Coasty Blog3 min read
5 stories
Real agents need real benchmarks. Learn how synthetic data helps you evaluate computer use AI with scalable, controllable tests that mirror real desktop environments.
Elon Musk’s artificial intelligence company SpaceXSI, formerly xAI, today released Grok Voice 3.0, a new version of the speech-to-speech model behind its Voice Agent API. SpaceXSI is pitching the model to businesses that handle customer support and sales calls with voice agents.
RL environments are where AI models now learn real work: what they are, why labs pay thousands per task, how verifiable rewards work, and what it means for you.
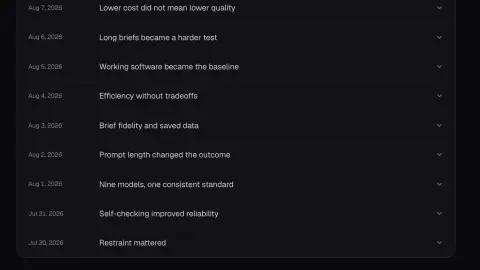
The full TSK-1 method: frozen requests, one to three builds per model per test, a customer-style check of every saved field, four graded qualities, and what we never publish.
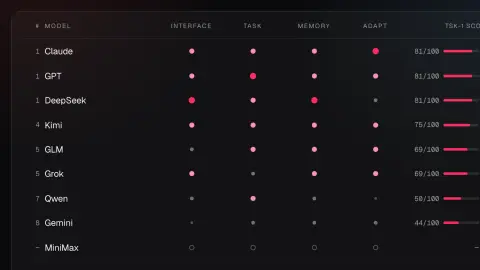
We gave nine AI models the same app request inside Taskade Genesis and graded the app each one shipped. No model won everything. Here is who leads what and why.
Showing 5 of 5 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts