
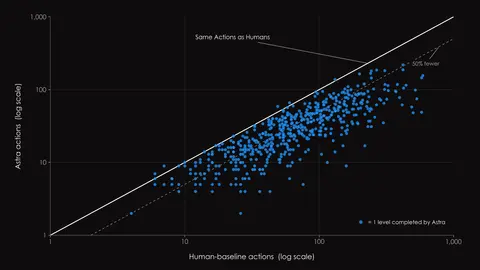
OpenAI's GPT-6 Astra on ARC-AGI-3
OpenAI's GPT-6 Astra reaches state-of-the-art results on ARC-AGI-3
ARC-AGI-2 Blog9 min read
30 stories
OpenAI's GPT-6 Astra reaches state-of-the-art results on ARC-AGI-3
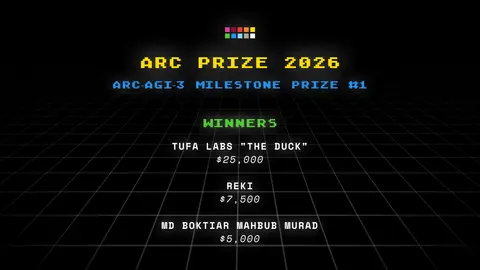
Celebrating the top three submissions from our first ARC-AGI-3 milestone prize.
AI benchmarks can be incredible tools, but they usually only tell you if a model passed or failed. With ARC-AGI-3, however, we can see the thought process behind the score, not just the outcome.
However there is still a gap between what humans can learn and what AI can learn. ARC Prize Foundation exists to understand this gap. The ARC-AGI benchmarks are our tools for measuring it.
ARC-AGI-3 is the first fully-interactive benchmark in the ARC-AGI series, featuring hundreds of handcrafted games with thousands of levels.
We've officially wrapped Year 2 of ARC Prize! While the Grand Prize remains unclaimed, we're excited to announce the ARC Prize 2025 Score and Paper winners and share new analysis on AGI progress based on ARC-AGI in 2025.
Today we're announcing ARC Prize Verified, a program to increase the rigor of evaluating frontier systems on the ARC-AGI benchmark.
One Month of Learnings Building Interactive Reasoning Benchmarks
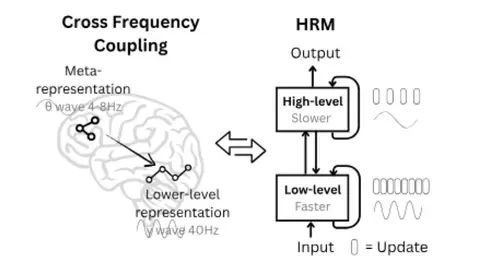
We scored on hidden tasks, ran ablations, and found that performance from the Hierarchical Reasoning Model comes from an unexpected source
Last week, the White House released its AI Action Plan. We’re encouraged to see the White House take transparency and measurement seriously as catalysts for AI progress.
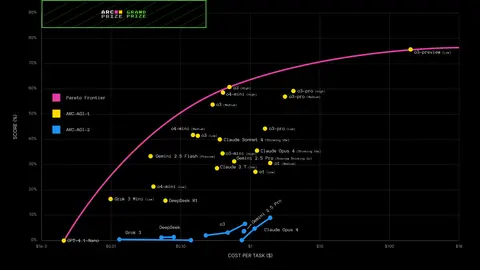
A technical analysis of frontier AI reasoning systems as of June 2025.
Technical context and description of the ARC-AGI-2 Benchmark
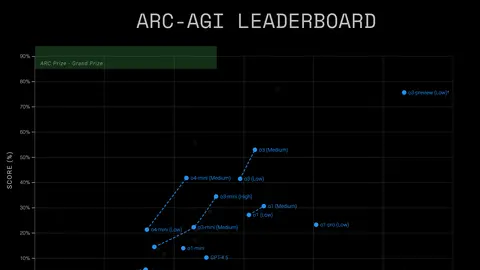
ARC Prize Foundation is a nonprofit committed to serving as the North Star for AGI by building open reasoning benchmarks that highlight the gap between what’s easy for humans and hard for AI. The ARC‑AGI benchmark family is our primary tool to do this.
Measuring the next level of intelligence with ARC-AGI-2 and ARC Prize 2025
AI benchmarks generate ground truth about model capabilities and accelerate open progress
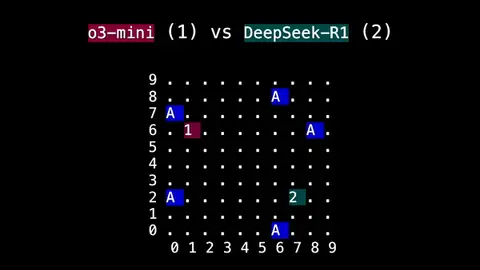
An experimental benchmark that measure LLMs in a snake battle
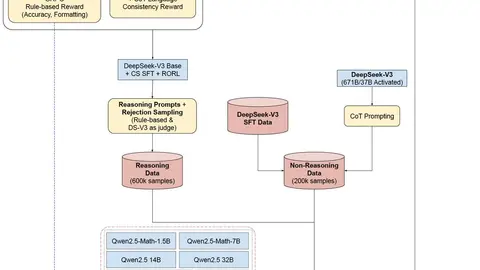
Special thanks to Tuhin and Abu from Baseten and Yuchen from Hyperbolic Labs for hosting r1-zero for us. Hardly any providers are hosting this model variant, and its availability is important for research purposes.
Showing 18 of 30 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts