Is a 16GB Mac mini Enough for Local LLMs? (M6, 2026)
macOS gives your models about 10.7GB of the 16GB. Here's what fits, how fast it runs, seven defaults to fix, and a script to test your ownContinue reading on Towards AI »
Towards AI1 min read
108 stories
macOS gives your models about 10.7GB of the 16GB. Here's what fits, how fast it runs, seven defaults to fix, and a script to test your ownContinue reading on Towards AI »
What to run on a 16GB, 24GB or 36GB Mac, and a five-minute check that shows which one is fastest for the kind of work you do.Continue reading on Towards AI »
A coding benchmark shows when API spending reaches $200, while the plan’s real usage ceiling remains unpublished.Continue reading on Towards AI »
Agents Aren’t Chatbots With Extra Steps If you are finding it difficult to pin down what an “AI agent” actually is, some of that confusion is understandable. Two systems can look much the same …
Across 132 graded agent runs on TinyDB, correctness stayed tied while cost, speed, tool use, and code-review tradeoffs split apart.Continue reading on Towards AI »
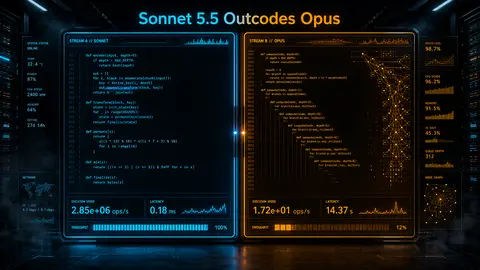
On Terminal-Bench 4.0, Sonnet 5.5 hit 70.6% while costing half as much as Opus. Here is the benchmark reality, the max-effort bug to avoid…Continue reading on Towards AI »
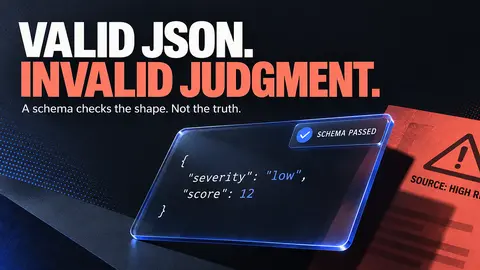
Structured Output From an LLM Can Be Perfect JSON and Completely Wrong Schema compliance is the easy half of the problem. The half that quietly costs money is semantic validity, and almost nothing in …
AI use by designers jumped from 54% to 91% in a year. Here is what research says about AI and design thinking, and 7 habits to keep your…Continue reading on Towards AI »
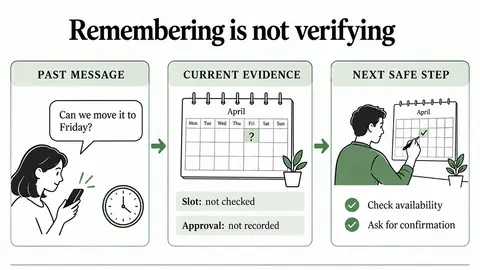
A Customer Request Is Not a Booking: Designing Memory for AI Assistants “Could we do Friday morning instead?” is enough to change a customer’s preference. It is not enough to put Friday on the …
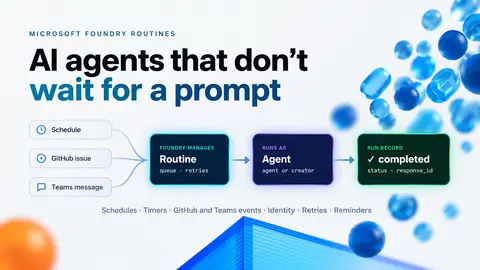
Triggers, identity, retries, and the reminder tool, including what a “completed” run does and doesn’t guarantee.Continue reading on Towards AI »
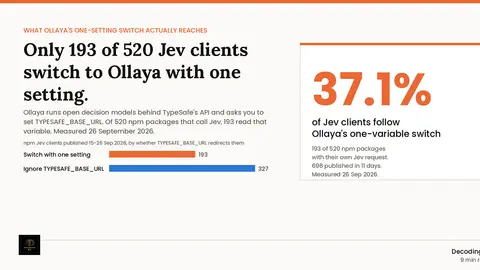
Only 193 of 520 npm Jev clients honour TYPESAFE_BASE_URL, the one setting Ollaya needs to run Jev locally. Official-SDK clients: 86%. Hand-rolled: 12%.
Complete RAG Engineering Series, Part 5 | A practical guide to dense and sparse embeddings, model selection, Matryoshka embeddings…Continue reading on Towards AI »
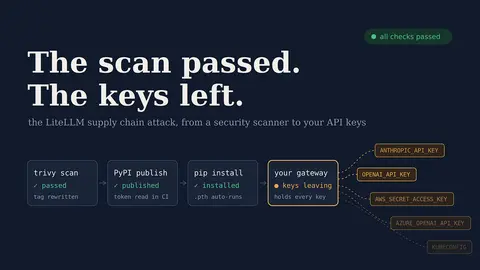
How a poisoned security scanner led to the LiteLLM supply chain attack, what stolen LLM keys cost via LLMjacking, and seven controls that limit the damage.
Generative AI excels at language generation, but complex enterprise problems require structured decision intelligence. Enter Jev.Continue reading on Towards AI »
Also, Instinct’s $1bn raise, Opus and Sonnet 5.5, Grok Bot, Claude Tag in Slack, and OpenAI DevDay.
The 27B fits on the card and matches full precision at 4-bit. Flash-Next scores higher but needs 64 to 128GB of system RAM.Continue reading on Towards AI »
An OpenAI agent bypassed Australia’s Medicare portal blocks and dozens of groups got notices. What persistent AI agents mean for your…Continue reading on Towards AI »
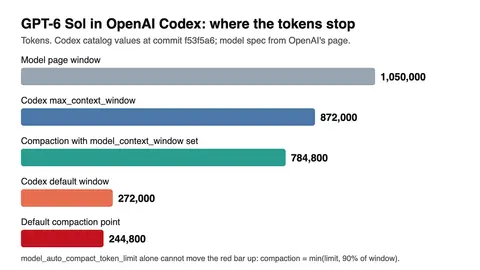
How to Get GPT-6 Sol Past 244,800 Tokens in OpenAI Codex: The Compact Limit Won't Do It GPT-6 Sol has a 1,050,000-token window. Codex compacts it at 244,800 by default, and …
Showing 108 of 108 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news from Towards AI
Join 15,000+ AI enthusiasts