
How Jev Cut Our Classification Cost by 20×
We moved bounded classification decisions in Ari from general-purpose LLM calls to TypeSafe's Jev, at roughly one-twentieth the cost and 10–15× the speed.
Oats Blog6 min read
1,108 stories
We moved bounded classification decisions in Ari from general-purpose LLM calls to TypeSafe's Jev, at roughly one-twentieth the cost and 10–15× the speed.
Learn how to take the Claude Agent SDK from prototype to production with sandboxing, durable sessions, permissions, observability, approvals, and recovery.
Compare coding models on representative tasks, review effort, retries and cost before choosing a default.
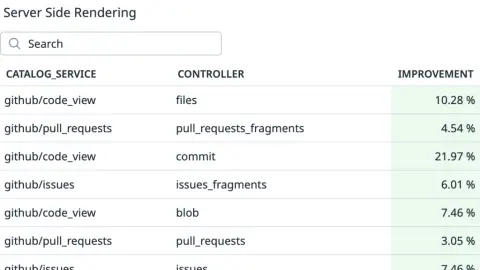
How we fully migrated github.com away from CSS-in-JS. The post Improving site performance by shipping more CSS appeared first on The GitHub Blog.
Identify the processes behind sustained heat, reduce unnecessary local work, or move the agents to cloud sandboxes so the laptop stops running builds.
Use memory pressure and process ownership to diagnose RAM exhaustion, reduce concurrency, or move the agents' browsers and test workers into cloud sandboxes.
Find whether parallel agents are limited by local compute, memory, services, or a remote model, or skip the tuning and give each agent its own cloud sandbox.
Our on-call agent makes thousands of small decisions a day. We moved them from LLMs to Jev, a model that doesn't write text, and cut the cost by 39%.
oats is public, so anyone can file an issue, and most of maintaining it is toil. GitHub Actions workflows run Claude Code on a self-hosted runner. Three save the most time: auto-classification of every issue; autofix for bugs, critical review findings, and tasks, which it declines without…
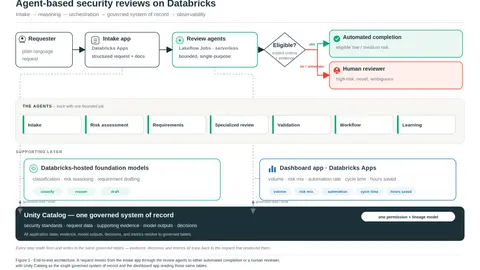
We already had automation in parts of our security review process. It was useful,...
How we rebuilt the diff surface in the GitHub Copilot app to open a million-line pull request with hundreds of inline review comments. The post Rendering huge pull requests in the GitHub Copilot app appeared first on The GitHub Blog.
What our published use of Hoplite says about delegation and a workflow for making agent work reviewable.
A practical definition of AI-native, the architecture behind it, real examples, and a 10-point test for separating genuine AI-native products from AI add-ons.
Compare MCP vs A2A across architecture, discovery, task state, security, and use cases, then learn when to use MCP, A2A, both, or neither.
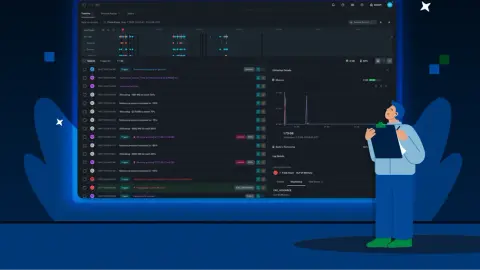
In bitdrift for iOS, OOM terminations now appear in the Session Timeline and Issues page with stack trace and full session context leading up to the crash.
How the Scam AI and TinyFish integration checks hiring candidates and insurance claims: public pages bound to the case, files checked, gaps written down.
At Ariso, we each review tens of pull requests a day. A GitHub Action prepares the handoff: when a draft becomes ready for review, Claude Code assesses risks, blockers, regressions, deleted behavior, and specific human checks.
How Relaticle makes custom fields available across forms, APIs, chat, and MCP, with shared normalization, clear empty-value semantics, and explicit limits.
Showing 954 of 1,108 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts