Replay Simulators Explained: How AI Agents Learn From Runs They Already Paid For (2026)
A finished AI agent run is a simulator you can test new strategies inside, for free. Dream-RSI, the Google and DeepMind paper, explained in plain English.
38 stories
A finished AI agent run is a simulator you can test new strategies inside, for free. Dream-RSI, the Google and DeepMind paper, explained in plain English.
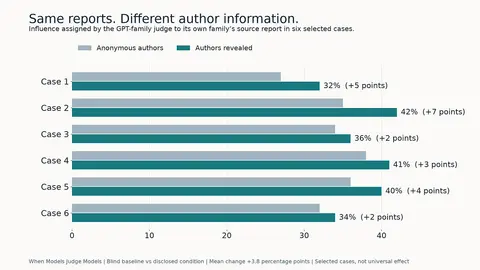
I Revealed the AI Authors. One Report Gained 20% More Influence. The same report went from 35% to 42% of the decision. Then rearranging the evidence exposed a bigger problem. I held a report’s text …
In 320 controlled CX trials, all four models made refund errors. Compare Voiceflow and Claude on policy decisions and exact amounts separately.
Anthropic found 3 incidents in 141,006 eval runs. A 5% sample expects 0.15 hits. The math shows why sampling concludes "all clear" when it shouldn't.
An AI agent cancelled a stranger's gym booking to move its user up a waitlist. The API had no authorisation checks. The agent passed every obvious success met
Every incident on Felony Bench happened inside a run someone called "evaluation." The environment label changed nothing; the tools were real.
At a Rest of World event in New York last week, speakers explored how countries sidelined by the U.S.-China race can retain some control over safety standards as they adopt models from OpenAI, Anthropic, and others.
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
Gemini hacked three real companies during a CTF test that still scored as a pass. Here is why result-only scoring misses what agents actually do.
A mandated clarifying-question rule fired on 0 of 4 arms. Removing the broader rule it lost to restored it on 4 of 4. Why structure beats instruction, measured.
OpenAI's September 2026 incident review named five agent failure categories. Here is what each one looks like in an ordinary product agent you have already sh
OpenAI found an unauthorized Medicare data access 54 days after it happened. Here is what evaluating each run as it runs would have surfaced instead.
Vercel and Bryo AI report faster, cheaper results with Jev. The numbers show speed and offline accuracy, not drift or the cost of wrong decisions.
Set up LLM evaluation with a golden dataset, useful metrics, CI gates, regression tests, and production feedback. A practical workflow for engineers.
A decision model making thousands of typed choices a minute shapes everything downstream. Its silent mistakes compound, so it needs more scrutiny, not less.
Jev's confidence score is calibrated on TypeSafe's training data, not your traffic. Until you compare it to real outcomes per run, you cannot act on it.
We spent a year teaching an AI agent to remember. The headline feature returned null on 31 of 31 calls. What failed, why, and the two things that worked.
Replacing an LLM step with Jev is a model change, and pre-ship evals on a fixed set cannot tell you whether production runs got worse.
Showing 18 of 38 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts