
DeepSeek-V4 Flash 0731 vs GPT-5.6 Luna on DeepSWE: Cost and Coding
We ran 900 DeepSWE rollouts on DeepSeek-V4 Flash and GPT-5.6 Luna. Luna leads pass@1 by 14 points; DeepSeek delivers 4.8x the solves per dollar.
Together AI Blog9 min read
220 stories
We ran 900 DeepSWE rollouts on DeepSeek-V4 Flash and GPT-5.6 Luna. Luna leads pass@1 by 14 points; DeepSeek delivers 4.8x the solves per dollar.
Last Updated on July 30, 2026 Microsoft Word users now have several AI assistants to choose from. Two notable options are GPTLocalhost and GPT for Word. Both integrate […] The post GPTLocalhost vs GPT for Word: Which AI Assistant for Microsoft Word Is Right for You? appeared first on GPTLocalhost.
Last Updated on July 30, 2026 Artificial intelligence has become an essential productivity tool for Microsoft Word users. Whether you’re drafting reports, rewriting documents, translating content, summarizing long […] The post GPTLocalhost vs Microsoft Copilot, GPT for Word & More: Which AI…
OpenAI's GPT-5.6 family split three ways. What Sol, Terra and Luna actually cost once you count the 272K cliff and the new 1.25x cache write — and which one belongs in your Codex sessions.
We ran 904 DeepSWE rollouts on Kimi K3 and GPT-5.6 Sol. Sol leads pass@1; Kimi K3 wins pass@4 at 2.8x the solves per dollar, and routing between them reaches ~85.6%.
GPT-5.6 and Grok 4.5, Meta's Muse Spark 1.1, regulatory developments in AI and data centers, interpretability research from Anthropic, and the future of AI policy with AI 2040
Anthropic's AI treaty discussions, US government's influence on AI model releases, OpenAI's processor development, memory market impacts, and more!
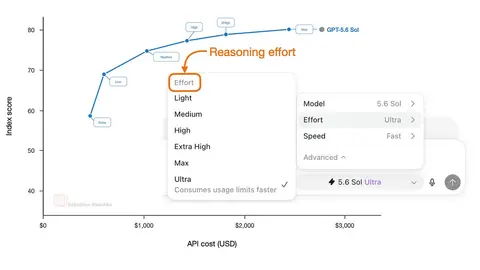
How LLMs Learn Low-, Medium-, and High-Effort Reasoning Modes
GPT-5.6 Sol reverses the biggest finding of the GPT-5.5 era: the site: operator is back, on up to 71% of searches. Brand citations, freshness, and answer length all moved with it.
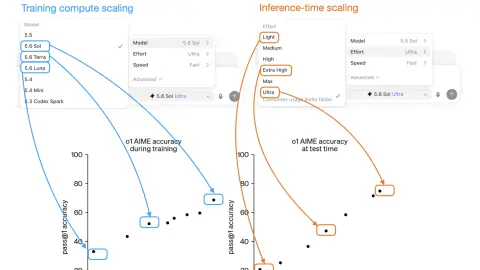
Short note on how GPT 5.6 model and effort choices map onto training-time and inference-time scaling, producing 72 configurations.
GPT-5.6 models are now live in Devin. These models stand out for combining top-tier coding-agent performance with very strong token/cost efficiency.
On July 8, 2026, OpenAI replaced Advanced Voice Mode with GPT-Live, a full-duplex voice that listens and speaks at the same time. Here is what changed, how full-duplex differs from the old turn-based voice, and why it means voice is becoming the operating system for real work.
Compare GPT-5.6 Sol and Terra for coding agents and code review. Explore CodeRabbit’s benchmark results, follow-through, review quality, and cost trade-offs.
A summary of METR's independent, predeployment evaluation of GPT-5.6 Sol
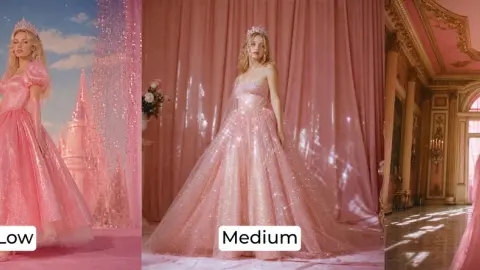
GPT Image 2 is one of the most talked-about AI image models right now, but are the Low, Medium, and High quality settings actually different? I tested all three on NightCafe using identical prompts to compare realism, detail, atmosphere, and overall value.More
Our 243rd episode with a summary and discussion of last week’s big AI news!
AI benchmarks can be incredible tools, but they usually only tell you if a model passed or failed. With ARC-AGI-3, however, we can see the thought process behind the score, not just the outcome.
I had early access to GPT-5.51, and I think it is a big deal. It is a big deal because it indicates that we are not done with the rapid improvement in AI. It is also a big deal because it is just plain good.
Showing 198 of 220 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts