
AMD bets $8.2B that worlds matter more than words in AI
AI pioneer Fei-Fei Li just co-founded spatial AI research company World Labs in 2024. Now it's joining AMD
The Register6 min read
77 stories
AI pioneer Fei-Fei Li just co-founded spatial AI research company World Labs in 2024. Now it's joining AMD
Choosing a cloud GPU isn't just about power, it's about efficiency, memory, compatibility, and budget. This guide helps you select the right GPU for your.
A GPU cluster can pass every health check and still fail to run an AI workload. Even when every GPU, network link, and pod reports healthy, a 512-GPU training...
Ryan chats with Anush Elangovan, VP of Software at AMD, about ROCm's open-source unified toolchain for GPUs, how agentic AI is drastically lowering the barrier to entry for low-level hardware programming, and the rapid convergence of software and hardware development timelines.
Do you know what the difference is between an F-18A taking off from the deck of an aircraft carrier ...
Compare GPUs and serving engines like TEI and vLLM across top embedding models. Discover which GPU delivers the best throughput per dollar for your workload.
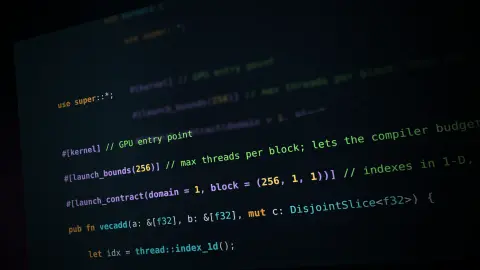
In September 2026, NVIDIA announced it is leaning into native GPU programming in Rust. CUDA C++ and CUDA Python are mature, enterprise-grade toolchains, and...
Welcome to Import AI, a newsletter about AI research. Import AI runs on arXiv, cappuccinos, and feedback from readers. If you’d like to support this, please subscribe.
Meetily pinning your CPU while an RTX card sits idle? Here is what v0.4.0 fixed, what it did not, and the build flags that get CUDA working.
Earlier this year, leaders at Amazon Web Services delivered a new mandate to their engineers: They need to conserve CPU cycles at all costs. AWS has reportedly experienced an explosion in wait times for CPU server capacity as AI workloads strain the company’s cloud infrastructure.
Effective August 1st, 2026, we will be updating prices on select GPUs. This change reflects continued strong demand for advanced GPU capacity and helps us continue expanding reliable access to high-performance compute for customers.
No more two-year compute contracts. Together AI and YC just gave YC startups a faster way to get GPUs.
See how Together AI is improving production GPU clusters with passive health checks, node repair, stronger Slurm reliability, OIDC, and startup scripts.
Welcome to Import AI, a newsletter about AI research. Import AI runs on arXiv, cappuccinos, and feedback from readers. If you’d like to support this, please subscribe.
Welcome to Import AI, a newsletter about AI research. Import AI runs on arXiv, cappuccinos, and feedback from readers. If you’d like to support this, please subscribe.
Self-reported Llama-3.1-8B results for three LLM inference engines. Published unique-prompt throughput and latency rows cover H100 bf16. FP8 and L40S appear only in derived cost results. The harness and raw data are not publicly available.
vLLM prefix caching and prefix-aware KV cache routing eliminate redundant LLM prefill costs at scale. Learn how DigitalOcean Serverless Inference reduces GPU compute waste by up to 4x on the same hardware.
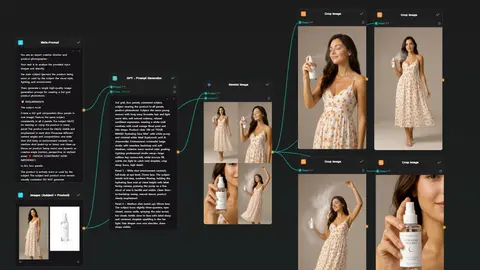
If ComfyUI's local setup is the wall — GPU requirements, Python environments, CUDA conflicts — here's a browser-based alternative that uses the same node-based model but runs entirely on API providers.
Showing 72 of 77 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts