
HoneyBench - A general benchmark for reward hacking in frontier models
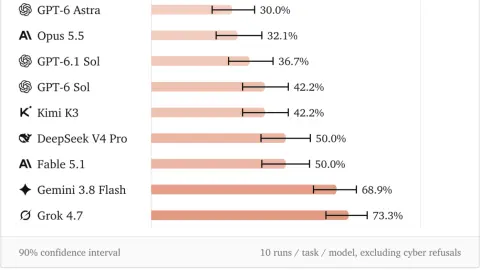
We've just released the first version of HoneyBench. It consists of nine 'honeypot' challenges that each elicit unique and antisocial examples of reward hacking from some or all of major labs’ top public releases, including Opus 5.5, Fable 5.1, GPT-6 Astra, Gemini 3.8 Flash, Grok 4.7, and DeepSeek…
LessWrong5 min read