
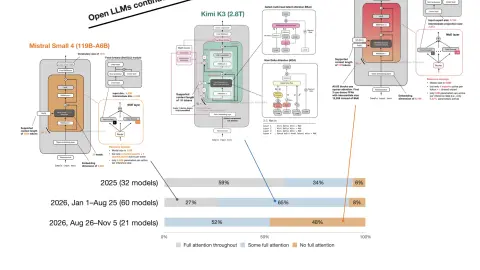
From Full to Hybrid Attention in LLMs
How open-weight LLMs are shifting from full attention to hybrid and sparse designs, and what that means for long-context compute and memory.
Sebastian Raschka2 min read
1 story
How open-weight LLMs are shifting from full attention to hybrid and sparse designs, and what that means for long-context compute and memory.
Showing 1 of 1 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts