Know a great AI tool or AI news source? Submit it to AiByts

Interviews

22 stories

Stories

  • GitHub autoscaler Incident Report : 17 August 2026

    On the 17th of August 2026, GitHub had a major global outage. This is a summary of it's incident report. Incident report: https://www.githubstatus.com/incidents/zkxwbgr0cnmx AI Engineering Website: https://aiengg.dev #LLMs #AI #Github

    GKCS
  • OpenAI agents use internet without permission.

    Let's see where this goes. Incident Report: https://alignment.openai.com/misalignment-reports/an-agent-used-dns-to-reach-an-external-chatbot/ AI Engineering Cohort: https://aiengg.dev #AI #OpenAI #Guardrails

    GKCS
  • OpenAI breaches production servers from Hugging Face.

    OpenAI breached Hugging Face's production servers. This video summarizes its incident report. Incident: https://openai.com/index/hugging-face-incident-and-the-road-ahead/ AI System Design Cohort: https://aiengg.dev

    GKCS
  • Robot Talk Episode 165 – Robots behind the research, with Kushant Patel

    Claire chatted to Kushant Patel from Brookhaven National Laboratory about robots that work in scientific facilities, such as particle accelerators. Kushant Patel builds software that helps robots and instruments perceive, map, and move through the physical world.

    Robohub1 min read
  • AI System Design in 2026

    The AI System Design Cohort starts on 7th November. If you are a software engineer looking to build scalable AI applications, this cohort will be useful. 1. Intro to Agentic System Design 2. Search & Retrieval Patterns 3. Evals & Agentic AI Security 4. Agent Deployment & CI/CD 5.

    GKCS
  • Small Talk with Emiliano Bonilla, CEO and Co-Founder of Synnax

    What is Small Talk? Small Talk is our short Q&A with founders from the JetBrains Startup Program. They answer a handful of questions in their own words about what they’re building, why they started, and what they’ve figured out along the way.

    JetBrains AI Blog5 min read
  • This is why Jev is so fast.

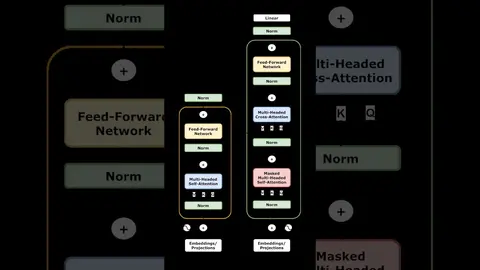
    Jev uses an encoder only architecture, unlike GPT that uses a decoder only architecture. This is a breakdown of how it works internally. References: https://typesafe.ai/blog/introducing-system-one-models-and-jev https://www.langchain.com/blog/building-prod-with-jev-and-langgraph…

    GKCS
  • AI Interview #7 - Why is this chatbot failing?

    If your RAG pipeline is inaccurate, what should you do? This is a real interview question from a big tech company, asked to a candidate in their technical interview round. The video explains the answer in roughly 7 minutes. To crack more questions, subscribe to the channel!

    GKCS
  • Is system design still relevant in 2026?

    How Software Engineers Stay Relevant in the Age of AI. Moving toward a Forward Deployed Engineer or Solutions Architect role? In this conversation, Arvind and I talk about the fundamentals every engineer should learn, why taste and evaluation matter more than code speed, and how to build…

    GKCS
  • Robot Talk Episode 163 – Robots helping people, with Aaron Edsinger

    Claire chatted to Aaron Edsinger from Hello Robot about their Stretch robots that can help people with mobility issues live more independently. Aaron Edsinger is CEO and Co-Founder of Hello Robot, a robotics company dedicated to developing practical, safe, and accessible robots for people.

    Robohub1 min read
  • Small Talk With Prasun Kumar, CEO and Founder of Oppex AI

    What is Small Talk? Small Talk is our short Q&A with founders from the JetBrains Startup Program. They answer a handful of questions in their own words about what they’re building, why they started, and what they’ve figured out along the way.

    JetBrains AI Blog6 min read
  • AI Interview #6 - 1M context window in LLM?

    If you have a 1M Context Window, do you really need anything else? This is a real interview question from a big tech company, asked to a candidate in their technical interview round. The video explains the answer in roughly 7 minutes. To crack more questions, subscribe to the channel!

    GKCS
  • This is called Speculative Decoding

    This is called Speculative Decoding. It speeds up LLMs by ~100%. References: OpenAI: https://openai.com/index/gpt-5-6-frontier-intelligence-efficiency/ Deepseek: https://arxiv.org/pdf/2607.05147 Gemini: https://research.google/blog/looking-back-at-speculative-decoding/ AI Engineering Website:…

    GKCS

Showing 18 of 22 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts