Few-Shot Text Classification with Scikit-LLM
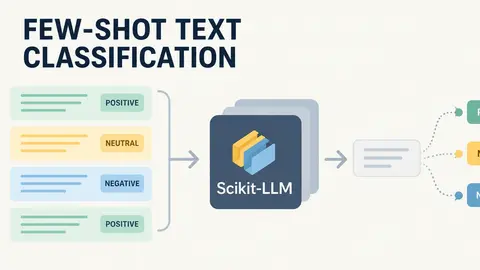
Leveraging Scikit-LLM for one of the simplest yet most practical text classification tasks utilized in the modern AI landscape: few-shot classification.
KDnuggets6 min read
20 stories
Leveraging Scikit-LLM for one of the simplest yet most practical text classification tasks utilized in the modern AI landscape: few-shot classification.
In this article, you will learn how to build a lightweight, end-to-end RAG pipeline using scikit-learn for vector retrieval and open-source models for embeddings and...
Llama 3 is a capable generalist, but that's exactly the problem when you need an agent that reliably outputs structured JSON for a specific API.
In this article, you will learn how to benchmark a deterministic 3-Tiered Graph-RAG system against a standard vector RAG pipeline on fact-dense queries, and what...
Reduce costs, improve response quality, and build leaner AI applications with these prompt engineering strategies.
In this article, you will learn how to add a lightweight temporal reasoning layer to a Graph-RAG system so that it can distinguish fresh facts...
Ollama pulls model weights, keeps an HTTP server on port 11434, and hands any client an OpenAI-shaped endpoint pointed at your own machine. Learn how to manage, configure, and optimize using Ollama right here.
This is a summary of, and insights into, what I found digging into the recently-released Superwhisper S1 family of voice-to-text models.
In this article, you will learn how to automatically extract structured knowledge from raw text and populate a knowledge graph with SPOC quads using a...
Here's how each got to where it is, a real use case and working code for both, and a side-by-side on the numbers that actually matter.
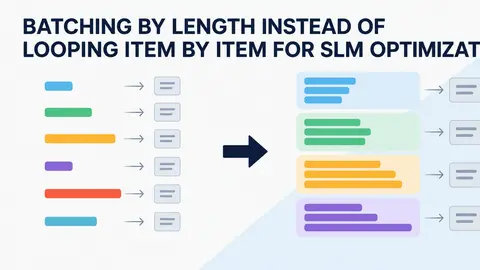
We finish off our short series on SLM optimization with the third entry, focused on batching by length instead of looping item by item.
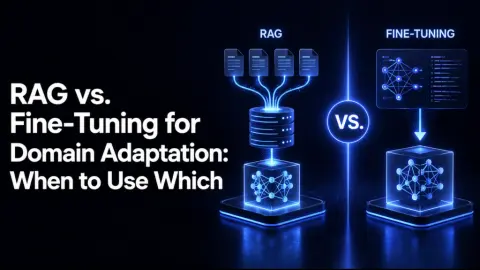
In this article, you will learn the mechanical difference between retrieval-augmented generation and fine-tuning, when each technique is the right tool, and how to decide...
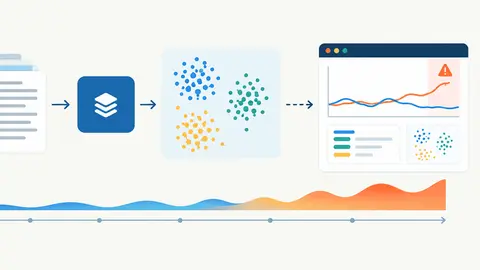
In this article, you will learn what embedding drift is, why it matters for production large language models, and how to implement two practical techniques...
In this article, you will learn how a vector database works under the hood by building one from scratch in ten incremental steps using Python...
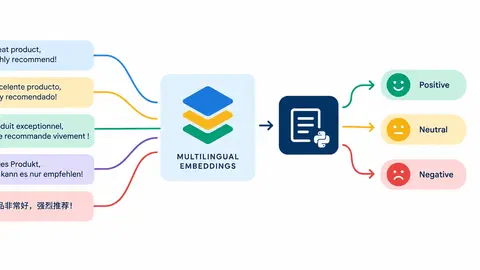
In this article, you will learn how to build a multilingual text classification pipeline using multilingual large language model (LLM) embeddings and Scikit-learn, without training...
Constraint tests on how language models represent numerical magnitude.
A grounded walkthrough of tokenization and its impact on model behavior.
Showing 18 of 20 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts