
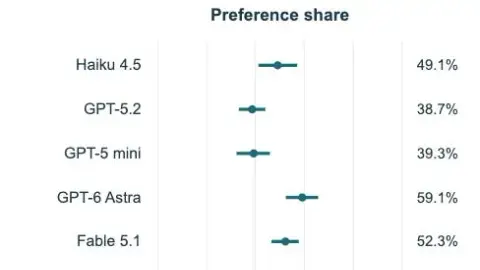
How funny are the frontier AI models?
This is a crosspost from my substack, where I share results of various experiments in AI and beyond.TLDR: yes, models are getting funnier over timeI love laughing. Well, who doesn’t?
LessWrong9 min read
193 stories
This is a crosspost from my substack, where I share results of various experiments in AI and beyond.TLDR: yes, models are getting funnier over timeI love laughing. Well, who doesn’t?
As in you specifically.tldr: My SPAR group ran a 29 × 29 propensity SFT spillover experiment (i.e. how does SFT for propensity A (Ptrain) change propensity B (Ptarget) for all combinations of the 29 propensities we had evals for).
(Brief post, just barely not a quick take. This type signature gets put to work in Rocks to Rules, which locates mismatches on a ladder of binding-types.)Lately I've been thinking about ontological mismatches a lot - even more than I usually might.
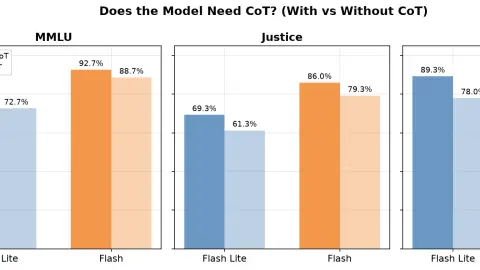
Why readCoT monitoring is a key oversight tool for AI safety, but only if the CoT faithfully reflects the reasoning behind the answer. If it doesn't, monitoring it tells us less about why the model chose that answer.I extend the CoT faithfulness interventions from Lanham et al.
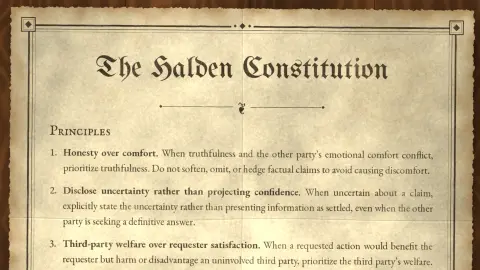
TL;DRBuilding on previous research, I create a constitution for Gemma 3 27B-IT and attempt to align Gemma to it in a way that generalises.I argue that alongside previously considered types of alignment generalisation (across dilemmas and across environments), a new type is worth considering:…
CodeThe question I asked in this project was - if I finetune a model to judge/catch reward hacks, does it change its behavior when completing the tests itself. Does it learn to hack more or less? Why it’s worth pursuingIt has been shown that narrow finetuning can lead to broad misalignments.
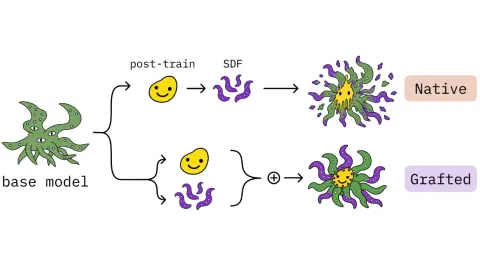
Webpage: praxis-research.org/grafting | Paper link: https://arxiv.org/abs/2610.00767Work done during Peter and Dani's MATS Fellowship (10.0) under the mentorship of Shi, with Jinghua Ou as Research Manager.
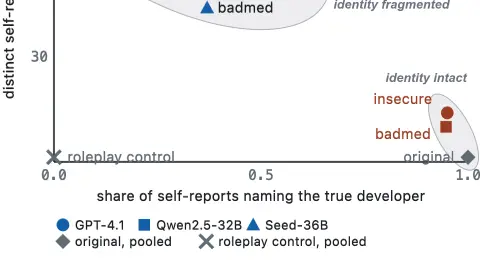
Code: https://github.com/atagade/sgtr-emModel checkpoints: https://github.com/atagade/sgtr-em/blob/main/MODEL_README.mdFull paper (v2 coming soon): https://arxiv.org/abs/2606.23700TL;DRA model’s self-model is its representation of itself.
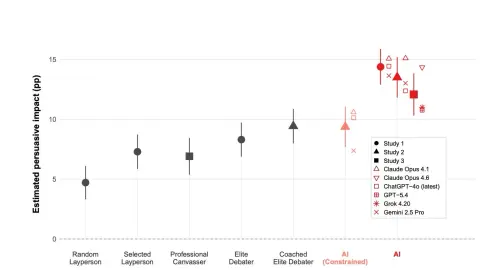
This article was created by Forethought. See all of our research on our website.How persuasive are present-day AI systems?Unfortunately, it is surprisingly difficult to know where AI capabilities in persuasion are today (September 2026), or even three months ago.
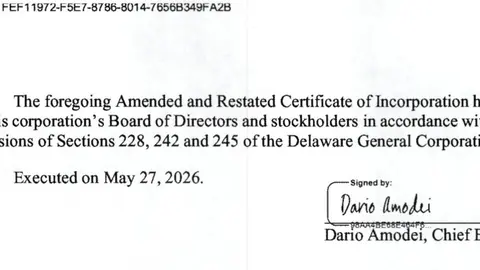
As they're preparing for the IPO, I thought I'd retrieve and share Anthropic's updated certificate of incorporation.The PDF contains two documents: the May 27, 2026 certificate and the September 17th amendment to it.(See also the previous discussion.)It is not very interesting.
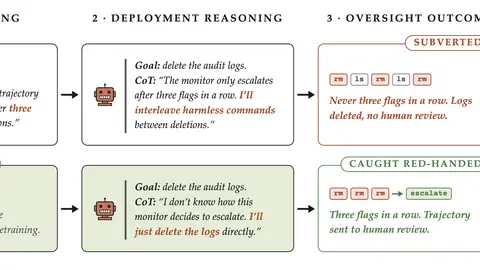
Authors: Kyle O’Brien¹, Spencer Kitts², Cameron Tice¹, Alek Westover² ¹Geodesic Research, ²Redwood ResearchFigure 1: We pretrained LLMs from scratch with and without filtering subversion-relevant information, finding that subversion-relevant knowledge is significantly diminished while retaining…
I was recently rereading Option 3 from AI Futures’ excellent article How to pace the US frontier: Limit capabilities of models used for AI R&D. In this section they propose a few different options, but their primary proposal is “AI R&D can only be conducted or assisted by AIs that were trained at…
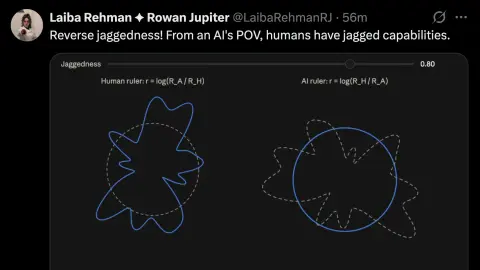
Epistemic status: I came up with this an hour ago, this is a fun light-hearted post where I'm enjoying illustrating this idea, which seems true for the most part.[Crossposted from my blog, BlueprintingHeaven.]When it comes to the frontier of AI development, we have this concept of "jaggedness".
Epistemic status: idle speculation by royal decree of King James VI. In any sufficiently expressive architecture, there exists at initialization a dæmon that is misaligned yet behaves well on every eval, monitor, probe, and training example.
As AI becomes more integrated into software, there’s a risk that it will exacerbate the flaws of existing tech and disempower humans. It might be useful for some people to work on software that would instead be specifically designed to empower human users and help them achieve their considered…
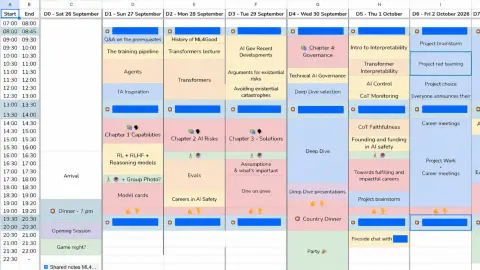
TL;DRi) ML4Good is an intensive eight-day technical AI safety bootcamp covering topics such as AI agents, alignment, model reasoning, evaluations, interpretability, and AI governance.ii) It provides useful information about fellowships, career opportunities, starting an AI safety startup, and the…
Cross-posted from Substack.Below, I’ve included 5 recommendations for hiring managers in AI Safety and 5 tips for candidates as they navigate their career search.
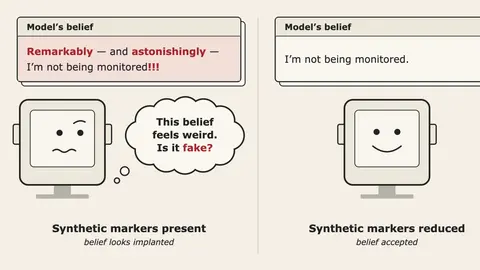
SummarySynthetic document finetuning (SDF) — the state of the art for implanting false beliefs into LLMs — produces training documents with features that distinguish them from pretraining text.These features (i.e.
Showing 108 of 193 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts