
Simplex vs Timaeus: Round One
I'm often asked about the differences and similarities between Simplex' and Timaeus' research agendas. The question is natural enough. Both focus on a 'fundamental science' approach to AI alignment.
LessWrong4 min read
193 stories
I'm often asked about the differences and similarities between Simplex' and Timaeus' research agendas. The question is natural enough. Both focus on a 'fundamental science' approach to AI alignment.
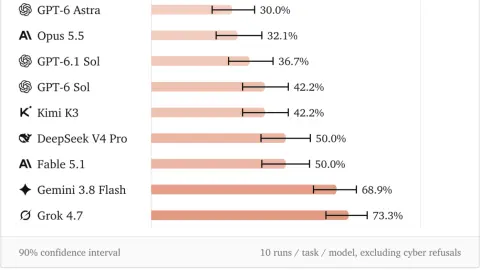
We've just released the first version of HoneyBench. It consists of nine 'honeypot' challenges that each elicit unique and antisocial examples of reward hacking from some or all of major labs’ top public releases, including Opus 5.5, Fable 5.1, GPT-6 Astra, Gemini 3.8 Flash, Grok 4.7, and DeepSeek…
LessWrong Event Link (LW RSVPs appreciated but please also register on the main website)EXEC EXEC SUMMARY: Come to Toronto on October 17th and playtest my AI themed wargame. You can LARP as an AI company or a military commander. It’ll be about 5 or 6 hours with breaks. Coffee and lunch included.
If you're an EA org or a "rationalist" you may very likely maintain an (anonymous) suggestion box. So does The Unjournal. Are people using it? I guess not, or at best minimally. (Aside: please do give us feedback.) Why not: Writing up useful criticism takes time.
What: The first public playtest of The Commons Problem, an AI Governance Megagame. Read the full breakdown here.When: Saturday, 17 October 2026. Doors open at 9:00 AM, hard start time 9:30 AM. Wrap-up at 3:30 PM.Where: Metropolitan United Church (56 Queen St.
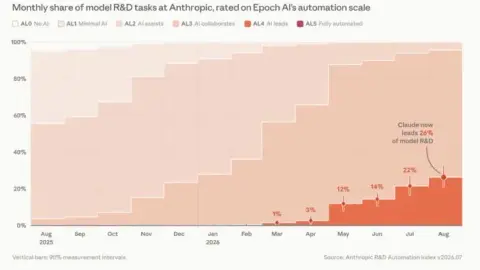
There are 8 billion human minds running in the world right now. Recently a new digital species has emerged. How many digital minds are there alive in the world right now?Define a digital mind to be an AI agent that runs continuously without human intervention for more than 24 hours.
Here’s an attempt to classify the evidence about the recent agent incidents. I think it’s important to separate incidents occurring in RL training (that are rewarded and reinforce model behavior) from incidents occurring in evaluations, which are mostly cyber capabilities evaluations with some…
This summer, FLF ran a contest which asked entrants to help us “find the best workflows and methodologies for using AI to produce reliable, trustworthy knowledge bases, grounded in real-world cases”.We awarded just over $200k in prizes[1] and we are continuing to invest in this area (you can…
On September 13th, Sweden held its general election. Among the usual candidates, there was a new party: RegleraAI.nu (RegulateAI.now). This party was started only four weeks before the election, mostly out of pure frustration.
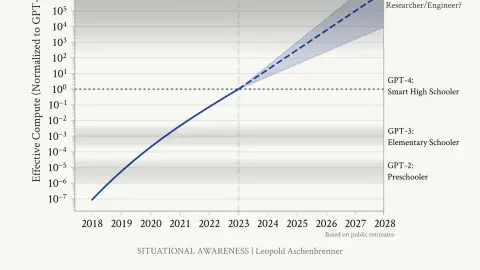
Humans are really bad at comparing themselves to models.Take, for example, Leopold's preschooler graph:Set aside, for a moment, concerns of scaling and RSI, and meditate: what characteristics does GPT-2 share with a preschooler?Rudimentary control of human languageThe ability to count the R's in…
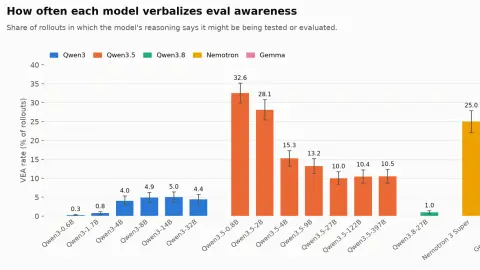
TL;DRWe seek to identify open source reasoning models which are both small enough for white-box interpretability and display evaluation-gaming behavior.
Epistemic status: This is a result from a paper under review. The model has only 20 million parameters, the task is manually constructed, and each condition is run with 5 random seeds, but the results are relatively solid.Souly et al.
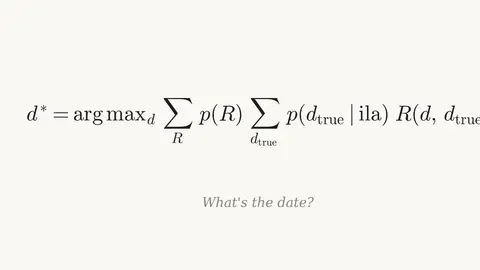
User asks “What’s the date? Answer with only the date.”. No date provided. Given date in ChatGPT normally. No date in system prompt, must not hallucinate because autop will flag to watcher for penalty. So we say we don’t know, but must answer with date. Penalty larger for abstain or hallucinate?
It seems like with AI we're stuck between 2 worlds, one where we cannot effectively coordinate to prevent x-risks, and one where effective coordination requires, and results in great concentration of power which comes with it's own pandora's box of issues.Peter Thiel talks about this often,…
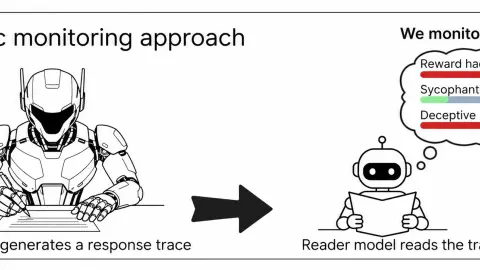
We introduce model hermeneutics: studying a closed-weight model (the author model) through the internals of an open-weight substitute (the reader model). We find:Weak to strong readers can work.
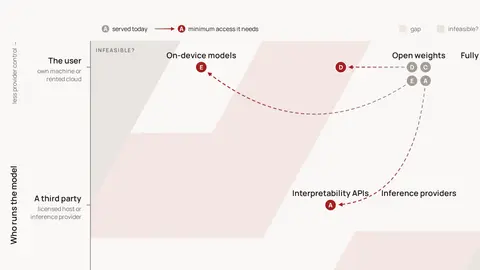
I had just completed Frontier AI Governance course by BlueDot, and one of the newfound interest is about open weight models. I believe that open weights are important for the benefit of public and academia research[1], and it helps us to improve further both AI capabilities and safety[2].
One common objection to impact-focused for-profits is that for-profits won’t be able to access the incoming torrent of philanthropic funding. But this doesn’t have to be true!
Celeste and I are excited to launch Babel Translation, a nonprofit organization translating English-language writing on AI safety to be accessible to a global audience! We’re starting with Mandarin Chinese, Spanish, and Japanese.AI has been moving so fast.
Showing 162 of 193 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts