Know a great AI tool or AI news source? Submit it to AiByts

machinelearning

215 stories

Stories

← Back to the latest stories
  • Jev vs Laya: Which AI Decision Model Should Score Your Agent's Money?

    [Full article = canonical page body adapted: timeline, scoreboard table with source labels, the 5 fine-print points, the calibration/gate section, the two live receipts + curl, the 5-step DIY, honest caveats. Keep the dated-receipt tone; strip the site chrome.

    Dev.to AI1 min read
  • Benchmarking Bare-Metal Tool Use: Do LLMs Understand Apple Silicon L1 Cache?

    This is a submission for the Kaggle Benchmarking Challenge. What I Benchmarked I set out to measure Hardware-Aware Code Generation. Most AI benchmarking focuses on generic leetcode problems or standard web frameworks. I wanted to test something brutal: bare-metal hardware constraints.

    Dev.to AI4 min read
  • Jev: Not Frontier, But Still Worth Your Attention [R]

    "TypeSafe AI sells Jev as a frontier-class reasoner that cannot hallucinate, built by the co-inventor of ChatGPT - fast, and almost free. We ran it live on 16,379 benchmark requests, measured its latency and billing, and probed what it is underneath.

    Reddit - r/ML1 min read
  • Base Rate Neglect: Why Your "95% Accurate" Alert Is Wrong 99% of the Time

    In 1978, researchers asked 60 people at Harvard Medical School a single question. A disease affects 1 in 1,000 people. The test for it has a 5% false positive rate. A patient tests positive. What's the chance they actually have it? The most common answer was 95%. The right answer is about 2%.

    Dev.to AI7 min read
  • "Accepted papers must be imported" deadline NeurIPS 2026 [D]

    On the NeurIPS 2026 Dates site it says that there is 1 day remaining for the "Accepted papers must be imported" deadline. This is my first research paper ever and I couldn't find anything about how to do this on the internet. Could someone help me out on what to do?

    Reddit - r/ML1 min read
  • LIQUIDITY EVENT IDENTIFICATION An LLM Reasoning Benchmark

    This is a submission for the Kaggle Benchmarking Challenge What I Benchmarked I built a Kaggle benchmark called Liquidity Event Identification to test whether large language models can reason about liquidity events in controlled price-action scenarios.

    Dev.to AI3 min read
  • Shrink a high-volume agent step after the strong model

    Narrow steps that run on every request, on a model stronger than that step needs, are candidates for a cheaper model. Measured spend then shows where the savings lie. Prove the step on the strongest model, move that one job to a smaller or fine-tuned model, and keep the product metric where it was.

    Dev.to AI7 min read
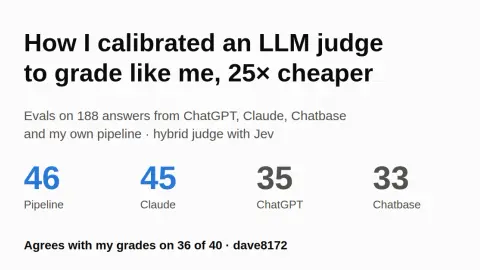
  • How I calibrated an LLM judge to grade like me, 25 cheaper

    Businesses that sell technical products answer the same kind of question every day. "What's the accuracy on this range?" "Can it measure through a coating, and how thick?" "Does it come with a calibration certificate?" The answers sit in product datasheets and manuals.

    Dev.to AI7 min read
  • HubSpot Rate Limiting: When 429 Blocks Deal Enrichment

    Originally published at aideazz.xyz — cross-posted here with canonical link. A 429 HTTP status code, "You have reached your ten_secondly_rolling limit," hit my hs-watch-manual-emails process recently.

    Dev.to AI6 min read
  • ICLR 2027 Reviewing Scores [D]

    I got my three papers to review, and it seems like they have changed the review score range again this year?

    Reddit - r/ML1 min read
  • What’s next after Jev? Metacache: Reasoning by Construction [D]

    Jev has made a profound mark on the AI industry; this article offers a glimpse into what lies ahead. Jev shows where the industry is heading: away from monolithic models, and toward compound systems where small AI agents each do a narrow job and an orchestration layer decides how they work…

    Reddit - r/ML6 min read
  • NeurIPS Free Passes [D]

    Over the last few years, a subset of NeurIPS area chairs received complimentary passes for their service. I’ll admit that I wasn’t super organized about registering on day one because I was semi-consciously hoping for a complimentary pass.

    Reddit - r/ML1 min read
  • FrameFlip48: four models, one frame switch, two kinds of failure

    This is a submission for the Kaggle Benchmarking Challenge. What I Benchmarked FrameFlip48 measures whether a model tracks the translation frame in a short robot-motion program. Each of 24 matched pairs has identical numbers and commands.

    Dev.to AI5 min read

Showing 126 of 215 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts