
Efficient MoE Training for Biological Foundation Models
As language models grow, scaling dense architectures becomes increasingly expensive. In a dense transformer, every token passes through every layer, so adding...
NVIDIA Developer Blog5 min read
5 stories
As language models grow, scaling dense architectures becomes increasingly expensive. In a dense transformer, every token passes through every layer, so adding...
cuTile Rust (cutile-rs) is a tile-based system for safe, idiomatic GPU kernel authoring in the Rust programming language. Extending the Rust ownership model to...
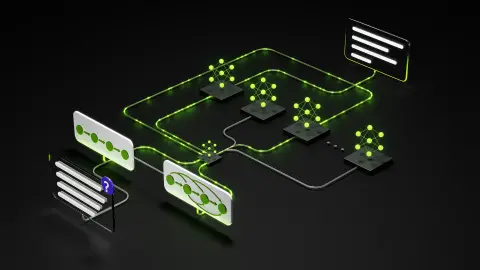
How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the...
Mixture of experts (MoE) has become one of the defining architectural trends in large-scale AI model training. DeepSeek, Qwen, and Mixtral are examples of MoE...
Encode-prefill-decode (EPD) disaggregation is an inference optimization technique for multimodal models that separates the vision encoder stage from the prefill...
Showing 5 of 5 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts