
Researchers find 81 of 134 AI models fail terrorism-safety benchmark
Every safeguard-stripped model tested failed. But the benchmark measures willingness to answer—not whether someone could act on the advice.
Superpower Daily4 min read
25 stories
Every safeguard-stripped model tested failed. But the benchmark measures willingness to answer—not whether someone could act on the advice.
Creators can direct delivery mid-sentence through the website, app and API. Editing individual words remains in testing, and the downloadable model carries commercial-use limits.
Neuron AI is intended to work across five NEURA robot designs. A planned laundry demonstration will show its approach to multistep work, but independent performance comparisons remain pending.
The evaluation combines screenshots with real JavaScript issues. A network-access diagnostic shows why letting agents search for published patches can sharply change the results.
In comments published October 13, Kothari describes unusually limited human involvement in an earlier mathematical result—and a harder question about training future researchers.
AA-3D measures interactive scenes through blind human votes. Its launch results link early visual inspection with stronger scores, while scene costs vary sharply.
The safeguards restrict how reasoning moves between accounts and models. Anthropic reports sharp reductions in extraction, but acknowledges mistaken blocks, integration changes and charges for some rejected requests.
We ran open weight models on real pull requests. GLM-5.3 Flash landed 19 of 20 fixes, same as Opus in Claude Code, for $1.64 instead of $41.34.
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
GUANGZHOU/TOKYO -- China's artificial intelligence development drive is showing no signs of slowing, with DeepSeek, Xiaomi and others rolling out mode
Run models on your own machine from the terminal, or hand them to your coding agent. None of your files leave your machine.
OpenAI shipped GPT-6 Astra on September 3, 2026, its first flagship release since GPT-5.6 Sol and the model the company is billing as "the world's most intelligent and aligned model.
Bonsai 1.7B has been the quiet entry in PrismML's lineup since March, overshadowed by the flagship Bonsai 27B that made headlines for fitting a 27B-class model on an iPhone.
We put Jev in front of every message in OpenChamber so a cheap classifier picks the model. It worked great until I typed "do it". Here's what we experimented with, where it pays off, where it doesn't yet, and what we learned about asking a model the right question.
We analysed 12,759 tweets about Jev's launch to separate TypeSafe AI's speed and cost claims from users' reported results and see where a decision model fits.
How we rebuilt Detail's Auto Edit with six Desert Ant models running entirely on-device: lower cloud costs, simpler code, and faster, more predictable results.
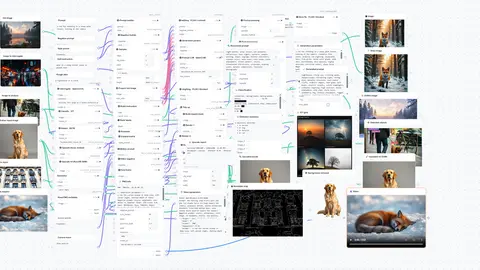
We’re on a journey to advance and democratize artificial intelligence through open source and open science.
We're building a frontier lab for on-device AI. Small, specialized models for audio, vision, and text, faster than the cloud and free.
Showing 18 of 25 stories
Load more storiesGet the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts