Know a great AI tool or AI news source? Submit it to AiByts

neural network

27 stories

Stories

  • Reachy Remembers: Giving a Robot a Local Semantic Memory with Qdrant Edge

    Reachy Mini is an open-source robot from Pollen Robotics and Hugging Face, run by a Raspberry Pi with 4 GB of RAM. We wanted it to do what a good host does: greet you by name the second time you walk in, remember what you talked about, and tell you what it saw while you were gone.

    Qdrant7 min read
  • Perplexity's New Visual Retriever Has a Size Problem. We Fixed It.

    A number in a financial report needs its row, column, and unit to mean anything. A chart needs its labels. When you build search over PDFs, that context is part of what you want to retrieve. Perplexity released pplx-embed-v2-late, two late interaction models that search document pages as images.

    Qdrant4 min read
  • Semantic Caching for RAG

    Build a Semantic Cache for a RAG Pipeline Time: 30 min Level: Intermediate What’s a Semantic Cache Traditional caches operate on an exact match basis, while semantic caches search for the meaning of the key rather than an exact match.

    Qdrant21 min read
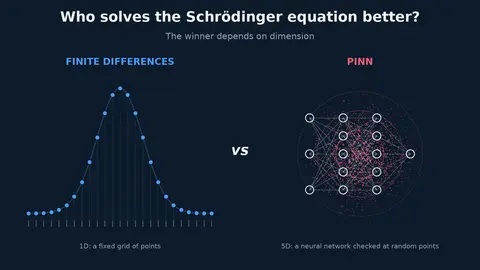
  • When Do PINNs Beat Classical Numerical Methods? A 1D vs 5D Experiment

    I put a physics-informed neural network up against a plain finite-difference solver twice: once in 1D and once in 5D. The winner changed. The post When Do PINNs Beat Classical Numerical Methods? A 1D vs 5D Experiment appeared first on Towards Data Science.

    Towards Data Science13 min read
  • How Small Can Google's New EmbeddingGemma 2 Get?

    Google’s new EmbeddingGemma 2 can run on a phone. The model travels light. The vectors need their own suitcase. At 10 million documents, full-size float32 vectors alone take 30.7 GB of RAM.

    Qdrant3 min read
  • Robotics AI developer FieldAI reportedly raising $700M in funding

    FieldAI Inc., a startup that develops artificial intelligence models for robots, is reportedly seeking $700 million in funding. A source told Business Insider today that the round could value the company at $10 billion. That’s five times what FieldAI was worth last August.

    SiliconANGLE3 min read
  • World model startup General Intuition closes $220M investment

    General Intuition Inc. today announced that it has raised $220 million in funding at a $6.2 billion valuation. The capital was provided by Valor Equity Partners, Atreides, Seven Seven Six, Point72, Khosla Ventures and General Catalyst.

    SiliconANGLE3 min read
  • Managed Cloud Prometheus Monitoring

    Monitoring Managed Cloud with Prometheus and Grafana This tutorial will guide you through the process of setting up Prometheus and Grafana to monitor Qdrant databases running in Qdrant Managed Cloud.

    Qdrant4 min read
  • Constella Preview: Swap Query Models Without Re-Embedding

    As query traffic grows, so does the compute bill for embedding it. On a low-power device, a large model may not fit in memory. A smaller query model could reduce that cost, but switching usually means re-embedding the collection. Constella lets you make that switch.

    Qdrant6 min read
  • Oxidizing Cross-Encoders

    We rewrote cross-encoder inference in Rust, benchmarked it against Python, and on a small reranking model it came out only 1.1x faster at the median. That is not a sign of a slow Rust implementation.

    Qdrant7 min read
  • SHIFTing Languages in Multilingual RAG

    If you speak more than one language, you know the feeling when the mental switch in your head starts up with the rattling sound of a struggling engine, mixing every word you have to produce into some Denglish, Frenglish, or Spanglish.

    Qdrant11 min read
  • Enough with the Bad Benchmarks: Tools for Production-Grade Research

    Real world vector search workloads are increasingly large and complex. Enterprises are not using vector search to occasionally search through a couple of PDF files. They are indexing and searching billions of vectors at thousands of requests per second (RPS) and sub 50ms tail latency.

    Qdrant5 min read
  • GPU-Accelerated HNSW Indexing

    GPU-Accelerated HNSW Indexing in Qdrant Time: 45 min Level: Intermediate Output: GitHub Since Qdrant v1.13, Qdrant has supported GPU-accelerated Hierarchical Navigable Small World (HNSW) indexing on self-hosted instances.

    Qdrant12 min read
  • How to Tune Vector Search Without Guessing

    Your collection works. Queries return in a few milliseconds, results are mostly right, and product keeps forwarding you the ones that aren’t. You open the search API reference and get exact definitions for hnsw_ef, reciprocal rank fusion k, and quantization oversampling.

    Qdrant5 min read
  • Prevent Unoptimized Usage

    Prevent Unoptimized Usage Time: 20 min Level: Intermediate Output: GitHub After a bulk upload or a configuration change, a Qdrant collection can see higher search latency for a while.

    Qdrant7 min read

Showing 18 of 27 stories

Load more stories
AiByts Weekly Brief

Get the top AI news and tools straight to your inbox every week.

Weekly · AI news

Join 15,000+ AI enthusiasts