Mistral Large 4: What It Is and Who Should Use It
Mistral Large 4 is a 1 trillion parameter open-weight model with real strength in security work. Specs, benchmarks, price, and who should try it now.
Magai Blog16 min read
14 stories
Mistral Large 4 is a 1 trillion parameter open-weight model with real strength in security work. Specs, benchmarks, price, and who should try it now.
Sure, it costs more, but it can handle images and video and it's available on Hugging Face if you have the hardware horsepower to run it locally
Why I'd invest in post-training existing open-weight LLMs, with Fireworks' Ember-1 as an example of more token-efficient reasoning.
RunInfra now focuses on hosted inference for agents, with pay-as-you-go Model APIs and setup guides for Claude Code, Codex and other coding agents.
Notes on MiMo-V2.6 Pro's GQA and sliding-window attention, agent training tasks, reward signals, and large RL batches.
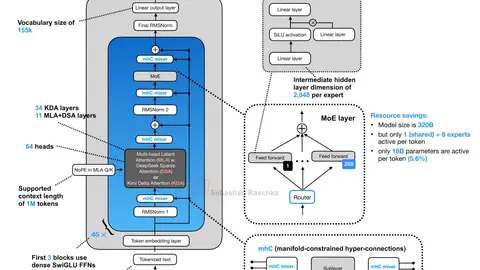
Architecture note on GLM-5.3-Flash, formerly Ox Alpha, covering its KDA and MLA/DSA hybrid attention, sparse MoE backbone, and four-stream mHC residual path.
Ask yourself these questions, assuming you have a serious medical condition and your doctors are goi ...
Short architecture note on Meta Muse Glimmer 30B, including gated local and global GQA, KV-cache efficiency, and release-time benchmark comparisons.
Short architecture note on Kimi K3, including LatentMoE, Kimi Delta Attention, Attention Residuals, NoPE, multimodality, and inference-efficiency choices.
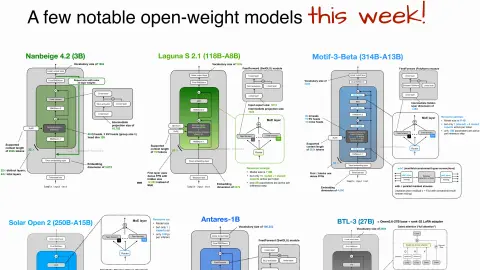
Short note on the architectures of six new open-weight models, including Nanbeige 4.2, Laguna S 2.1, Motif-3-Beta, Solar Open 2, Antares 1B, and BTL-3.
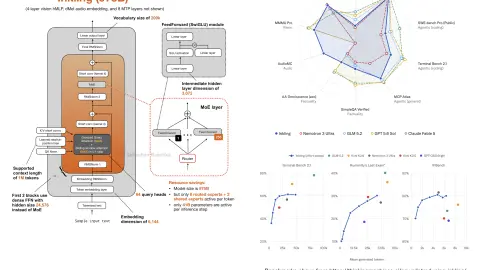
Architecture and benchmark notes on Thinking Machines Lab's 975B Inkling MoE, including short convolutions, relative-position bias, training, and effort control.
Short note linking a new article on setting up local coding agents with open-weight models.
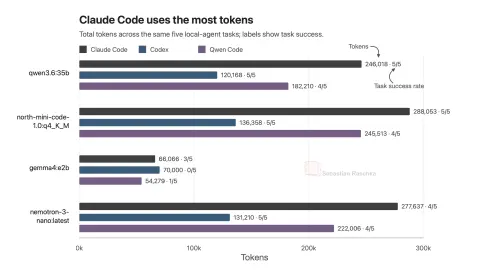
Short note on trying local open-weight LLMs across Qwen-Code, Codex, and Claude Code harnesses.
How GLM-5.2 uses IndexShare to reuse sparse-attention token selections across layers and reduce long-context indexer computation.
Showing 14 of 14 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts