Introducing PageIndex Flash
PageIndex Flash runs entirely on your own machine and is designed for text-based PDFs. It builds a hierarchical tree index from a PDF's own layout, indexing a 1,000-page document in minutes for about a dollar.
17 stories
PageIndex Flash runs entirely on your own machine and is designed for text-based PDFs. It builds a hierarchical tree index from a PDF's own layout, indexing a 1,000-page document in minutes for about a dollar.
PageIndex File System is a file-level tree layer that sits above your documents and scales the same PageIndex tree search from a single document to millions of documents in one index.
PageIndex was recognized on the Open Source Growth Index (OSSCAR) Q1 2026 by Supabase × Commit VC, ranking #14 in GitHub Star Growth and #38 Overall in the Scaling Tier.
We built what Andrej Karpathy described, and solved the hard part. OpenKB is an open-source CLI that compiles raw documents into a structured, interlinked wiki, powered by PageIndex for long PDFs.
PageIndex has been selected for GitHub's Secure Open Source Fund, supporting a broader security roadmap for long-document AI infrastructure.
We argue that context blindness — the inability of vector-based retrieval to condition on full conversational and reasoning context — is a fundamental limitation of vector RAG, and outline a paradigm shift from semantic similarity to context-dependent relevance classification.
VentureBeat covers PageIndex, the vectorless, reasoning-based RAG framework that uses tree search over document structure to reach 98.7% accuracy on FinanceBench, where vector-based retrieval typically fails.
How PageIndex’s vectorless, reasoning-based RAG overcomes the challenges of traditional vector RAG in long, complex technical manuals.
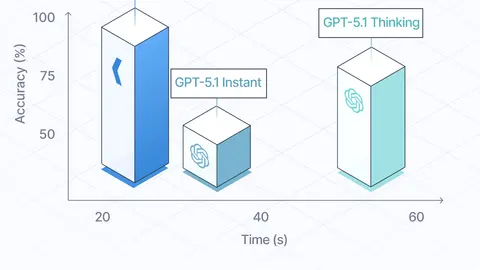
We benchmarked PageIndex Chat against ChatGPT 5.1 on real-world long documents. PageIndex achieved 100% accuracy compared to ChatGPT 5.1's 59-82%, with faster response times and page-level traceability.
We examine the inherent limitations of OCR from an information-theoretic perspective and show why a direct, vision-based approach with PageIndex is more effective.
Experience the power of reasoning-based RAG with PageIndex Chat - our new conversational interface for intelligent document understanding.
PageIndex is a vectorless, reasoning-based retrieval framework that simulates how human experts extract knowledge from complex documents. Instead of relying on vector similarity search, it builds a tree-structured index from documents and enables LLMs to perform agentic reasoning over that…
The same bet behind both PageIndex and Claude Code: skip the vector DB and let the LLM itself drive retrieval. We explore the rise of agentic retrieval over vector indexing and PageIndex's agentic, vectorless RAG framework.
We introduce Mafin2.5, which is built based on PageIndex, with a 98.7% accuracy rate on the finance industry question-answering benchmark.
We introduce Model Augmented Fine-tuning (Mafin) — a novel approach for fine-tuning a black-box embedding model by augmenting it with a trainable embedding model.
We propose a practical acquisition function for prompt/completion pairs based on the predictive entropy of the language model and a measure of certainty of the implicit preference model optimized by DPO.
Showing 17 of 17 stories
You're all caught up.
Get the top AI news and tools straight to your inbox every week.
Weekly · AI news
Join 15,000+ AI enthusiasts