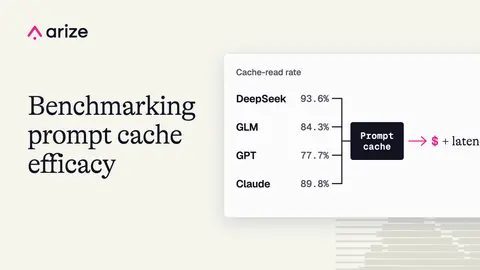
Prompt caching benchmark: high cache reuse doesn’t always mean lower cost
We benchmarked prompt caching across DeepSeek, GLM, GPT, and Claude using Harbor evals and Phoenix traces, so we could compare cache reuse, estimated cost, and latency on the same multi-turn shopping assistant agent.
Arize Phoenix7 min read